❌

Reading view

There are new articles available, click to refresh the page.

Victoria Derbyshire confronts Richard Tice over 3 key Brexit lies he told

Victoria Derbyshire has challenged Richard Tice over three key claims he made to persuade people to vote for Brexit that were “not true”.

The BBC Newsnight presenter reminded the Reform UK deputy leader of some of the things he said while campaigning for Britain to leave the EU in the 2016 referendum.

Derbyshire said: “You said Brexit would reverse unnecessary regulatory burdens and costs on businesses. Not true.”

Tice did not challenge Derbyshire’s point. 

She added: “You said leaving the single market would boost the UK economy. Not true.”

Tice interjected, and said it was true, because the UK economy is growing faster than France and Germany. 

“We’re not growing faster than Poland and others,” Derbyshire pointed out.

The UK’s annual GDP growth rate is around 1.9%, which puts it above Germany and France. However, the country is still growing far slower than countries such as Croatia, Poland and Cyprus. 

Tice responded: “I didn’t say we were, did I? If you’re going to quote me, then quote me correctly. We’re growing faster than France and Germany, I know it’s inconvenient for you and the BBC but that is the truth.”

Derbyshire said: “No, just giving some other facts as well.”

She then reminded Tice that he said prices would fall after Brexit. 

“Not true”, she said. 

“So why should voters trust what you say about Brexit now?,” Derbyshire asked.

Tice said “What we said is we would take back control, it is then up to the government of the day to take advantage of it.”

In a speech last night at the Lord Mayor’s banquet, Andy Burnham said “we have lost more than we have gained in the last 10 years”, due to Brexit.

Burnham also said that Brexit was what Russia wanted, as Putin knew it would cause disunity within NATO and a weaker Europe.

His comments come ahead of a crunch summit with EU leaders on Friday, where the Prime Minister is expected to negotiate a closer relationship with the EU.

Reform has said it would renege whatever deal Burnham negotiates. Burnham’s reset deal includes clauses to remove post-Brexit border checks on food and agriculture exports to cut bureaucracy for businesses and reduce trade friction.

The EU has said if a future prime minister pulls out of the deal, the UK would have to pay a multi-million pound “Farage fee”. 

Tice claimed that the reset deal would be “bad for Britain”, despite it reducing trade friction and said the concessions “are not worth it”.

“Reform would campaign to bring back bureaucracy for British business?,” Derbyshire asked Tice.

He said “far from it”, adding: “We need the freedoms to be able to get rid of the regulations”.

Asked by Derbyshire if Reform would refuse the pay the “Farage fee”, Tice said: “Of course, it’s ridiculous you can’t bind a future government.”

Derbyshire pointed out that “it’s a standard clause in an international treaty”.

“Forget it, we’ll just rip it up,” Tice responded. 

Olivia Barber is a reporter at Left Foot Forward

The post Victoria Derbyshire confronts Richard Tice over 3 key Brexit lies he told appeared first on Left Foot Forward: Leading the UK's progressive debate.

ICE Shot Pepper Spray Into a Car in a Traffic Stop, Then Broke a Detainee’s Collarbone

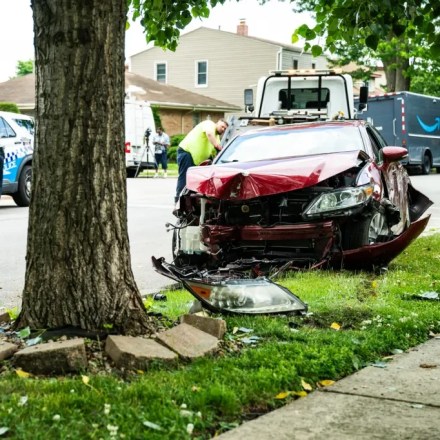
Jose Rosito Roca Estrada and his friends were on their way to work in a van on June 27, when a car in front of them slammed on its brakes, forcing them to crash into it and ricochet backward on the busy highway.

Three more cars surrounded theirs, and an estimated 10 to 12 officers poured out. The agents screamed at the men to get out of the vehicle despite traffic whipping by, Roca Estrada and fellow passenger Elvis Manuel Mejia told The Intercept. The stalemate ended with the sound of shattering glass and an asphyxiating cloud of chemicals flooding the car.

According to a new federal lawsuit and photos from the scene shared with The Intercept, federal agents smashed the car’s back windows and “sprayed the occupants with pepper spray through the lowered side windows.”

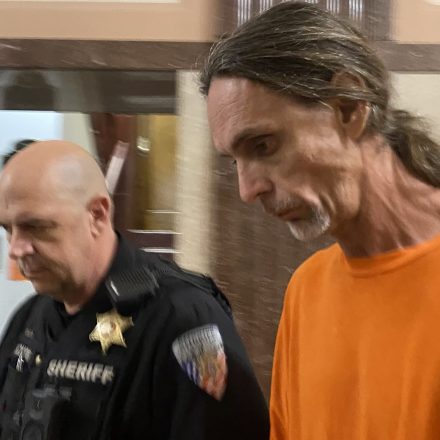
Officers then dragged a scared and temporarily blinded Roca Estrada from the car. “I was afraid they might be robbing me,” 24-year-old Roca Estrada told The Intercept through a translator. “They did not identify themselves. I was worried they were kidnapping me because they were asking very personal questions.”

“They did not identify themselves. I was worried they were kidnapping me.”

The June attack is one of six stories described in a lawsuit brought by several groups — including the American Civil Liberties Union of Virginia, the Washington Lawyers Committee for Civil Rights and Urban Affairs, the Legal Aid Justice Center, and multiple law firms — alleging widespread “unlawful and dangerous” warrantless arrests by immigration officials in Virginia. 

On behalf of Roca Estrada and other plaintiffs, the groups are suing the Department of Homeland Security, DHS Secretary Markwayne Mullin, Immigration and Customs Enforcement, Acting Director of ICE David Venturella, and ICE D.C. Field Office Director Robert Guadian. They’re asking the court in the Eastern District of Virginia to force DHS to comply with congressional limits on warrantless immigration arrests and prohibit the agency from making immigration arrests without legally required individual assessments.

“They have a mandate from the Trump administration … to get creative and make arrests, however they see fit,” said Sophia Gregg, an immigrants’ rights attorney at the ACLU of Virginia. “The agents are ill-trained, and even when they do violate the law, there are no consequences.”

Roca Estrada said that the officers demanded to search his pockets, and when he declined, an agent threw him to the ground headfirst and dug his knees into his upper back. He remembered screaming as pain began to radiate through his collarbone. An X-ray reviewed by The Intercept would later confirm it was broken. 

According to Roca Estrada and the lawsuit, officers began to punch and hit him in the back, eventually twisting his arm to place him in handcuffs and into the vehicle. Roca Estrada said that nurses who examined him after the alleged assault told him that blood had filled his lungs, and the lawsuit notes he was diagnosed with a broken clavicle and a lung injury. At no point, the lawsuit alleges, did officers ask the necessary questions to determine whether Roca Estrada was deportable or whether he was a flight risk.

Immigration officers are only supposed to make warrantless immigration arrests if they have determined “probable cause” to believe a person is unlawfully present likely to escape before a warrant can be obtained. But in an effort to meet the Trump administration’s nationwide quota of 3,000 immigration arrests per day, the lawsuit alleges, the Department of Homeland Security has chosen to pursue an unlawful policy and practice of “arrest-first, investigate-later” — leaving a trail of traumatized victims who should have never been arrested in the first place.

In the first year of the Trump administration, immigration arrests drastically increased in Virginia. According to the lawsuit, in 2025, ICE made “970 arrests each month in Virginia and Washington, D.C. — nearly five times the average monthly arrest volume in 2024.”

Reached by The Intercept, a DHS spokesperson said that agency had “arrested Jose Rosito Roca Estrada, an illegal alien from Guatemala,” using Roca Estrada’s full name even though The Intercept had not provided it, but denied that its officers “fractured a detainee’s collarbone.” The spokesperson did not deny that officials had deployed chemical weapons, saying, “staff relied on their training to gain compliance.”

“Claims that agents did not properly identify themselves are FALSE. When our heroic law enforcement officers conduct operations, they clearly identify themselves as law enforcement,” wrote the spokesperson. “At NO time were any of the detainees thrown to the ground during the arrest. Allegations that our officers fractured a detainee’s collarbone during the arrest are FALSE.” 

Six weeks after Roca Estrada’s arrest, 18-year-old Britney Ramirez Corona was home caring for her 4-year-old sister in Norfolk, Virginia, when she found out ICE had detained her fiancé, his brother, and his brother-in-law. 

It was another traffic stop, and Ramirez Corona, a U.S. citizen and recent high school graduate, had to go pick up their abandoned car. There, according to the lawsuit, an ICE officer demanded her identification, refused to let her get her wallet, and accused her of lying about who owned the vehicle. They handcuffed and pinned her, the lawsuit alleges — leaving her little sister to cry and wander into a busy road.

Eventually, ICE allowed another sister, 15, to come pick up the 4-year-old, then took Ramirez Corona into custody. She sat in “handcuffs, ankle shackles and a waist chain” for hours, according to the lawsuit, until her 15-year-old sister was able to bring her birth certificate — showing she was a natural-born U.S. citizen.

The lawsuit argues that Ramirez Corona’s arrest exemplifies an out-of-control trend of warrantless and often nonsensical arrests. Stephen Miller, then homeland security adviser and now the White House chief of staff, directed agents to “just go out there and arrest,” and the department seems to have complied.

“More than half of all the people ICE arrested in July 2026 did not have a criminal record,” the plaintiffs note. “And more than 500 people detained by ICE since January 2025 are U.S. citizens — another likely undercount — like Ms. Ramirez Corona.”

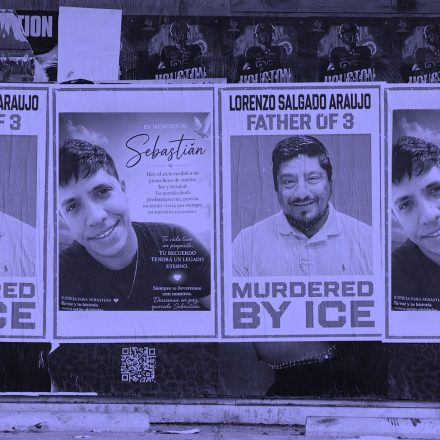
The same month that Roca Estrada says that federal agents temporarily blinded him, broke his collarbone, and beat him until his lungs filled with blood, Congress approved another $72 billion in funding for Immigration and Customs Enforcement. Immigrant advocacy groups warned ahead of the funding vote that additional money for ICE and President Donald Trump’s brutal immigration crackdown would mean more people would suffer a fate like Roca Estrada’s — or worse. The next month, ICE agents fatally shot Lorenzo Salgado Araujo in Texas and Joan Sebastián Durán Guerrero in Maine, both in their cars. 

Physicians for Human Rights and the UC Berkeley Human Rights Center documented over 412 incidents of misuse of force by law enforcement agents at immigration protests from June 2025 to May 2026, including the use of chemical irritants like pepper balls and pepper spray — the same family of weapons Roca Estrada and Mejia suspect was set off in their car.

In ICE custody, 52 people have died during the first 500 days of the second Trump administration, according to Human Rights Watch, while use-of-force by guards remains largely unknown.

“We have received many more reports of violent use of force against people,” said Jeff Migliozzi, the communications director for Freedom for Immigrants, which runs the National Immigration Detention Hotline, referencing hotline numbers from June and July. “The overwhelming forces of intimidation and fear and retaliation, the M.O. of ICE has not changed. But certainly, as more people are detained, there’s more incidents [of violence].”

The DHS spokesperson claimed that Roca Estrada and everyone arrested along with him were offered medical care but declined, adding that “one of the detainees indicated that he had a prior shoulder injury.” 

Roca Estrada tells a very different story. 

He says he spent the next month tossed between detention centers in Virginia and West Virginia. Because he was not given a sling, Roca Estrada fashioned one for his broken collarbone out of bedsheets. He said he largely went without medical care despite agonizing pain that prevented him from laying down at night.

Roca Estrada said it got so bad he nearly fainted, at which point he was taken to a hospital.

“After medical personnel offered to document his injuries and consult a forensic physician, officers abruptly removed him from the hospital and returned him to detention,” the lawsuit alleges. “For weeks thereafter, Defendants failed to provide the promised follow-up care.”

According to the lawsuit, none of this should have happened because Roca Estrada never should have been detained in the first place.

The suit alleges that immigration officers never asked the 24-year-old “about his immigration history, whether he possessed lawful status, where he worked, how long he had lived in Virginia, whom he lived with, whether he had family or community ties in the United States, or similar questions to assess whether he was likely to escape before a warrant could be obtained.”

Other stories in the lawsuit follow a similar pattern. Catarina Rebeca Us Lopez, a 24-year-old woman from Guatemala, was detained in Centreville, Virginia, during a traffic stop around 6:00 a.m. with her husband. She alleges that masked officers blocked her car at a traffic light and forced her and her husband from the vehicle.

The officers falsely claimed that her husband had a deportation order, according to the lawsuit. But when her husband asked questions about the stop, Us Lopez alleges an agent pepper-sprayed him in the face and threatened to draw their weapons.

According to Us Lopez, officers did not “inquire about her immigration status, ask where she lived, inquire about her family, ask about her ties to the community, or otherwise conduct any individualized investigation concerning whether she was lawfully present in the United States or likely to escape before a warrant could be obtained.”

Instead, she claims that officers ignored her as she explained that she had work authorization and did not have a deportation order in place, and allegedly mocked her requests for answers and legal assistance.

For Roca Estrada, his physical injuries and trauma left him unable to work for a month. While he was detained, he also lost his apartment and had his personal belongings sent back to Guatemala without his consent, according to the lawsuit.

“The way that I was arrested … and the immense pain that I had to go through during this whole experience,” said Roca Estrada. “What happened to me was not just.”

The post ICE Shot Pepper Spray Into a Car in a Traffic Stop, Then Broke a Detainee’s Collarbone appeared first on The Intercept.

💾

Will Senate Religious Freedom Bill Actually Protect Land Sales for Israeli Settlements?

A proposed “buffer zone” around religious facilities across the country — touted as protecting the right to worship — is alarming free-speech advocates who say the Trump administration could use it to crack down on protests.

The new bill, a national version of a controversial law passed in smaller jurisdictions, could hamper demonstrations against illegal sales of land in the West Bank to Jewish settlers that occur inside U.S. synagogues, the advocates say.

The bipartisan legislation could face another layer of opposition from a surprise corner, however, in the form of reproductive rights groups worried it would undermine an existing law that protects abortion clinics.

“Protecting religious freedom must not come at the expense of other Constitutional rights.”

Called the Right to Worship Act, the bill cosponsored by Sens. Ted Cruz, R-Texas, and Elissa Slotkin, D-Mich., will be the subject of a Tuesday hearing in the Senate Judiciary Committee.

The bill has drawn backing from Christian, Jewish, and minority religious leaders who say it could be used to prevent hate crimes. Major Muslim groups, however, have been notably absent from supporter lists.

That isn’t just because Cruz regularly demonizes Muslims. Muslim leaders also worry that while in theory the law would be used to promote religious freedom, in practice it would be used to punish non-violent, pro-Palestine protesters, said Dahlia Taha, the director of the First Amendment Center at the Muslim Public Affairs Council.

“Protecting religious freedom must not come at the expense of other Constitutional rights,” she said. “We believe that this can have very detrimental and long-term impacts. And under this administration, specifically, we’re concerned about those long-term implications.”

Slotkin and Cruz’s offices did not respond to requests for comment.

Land Sales as “Religious Services”?

Under the bill, the Department of Justice could seek civil fines or injunctions against anyone who engages in a “course of conduct” that disrupts religious services, or disrupts access to them, within 100 feet of a church, mosque, synagogue, or other religious facility. Worshippers and state attorneys general could also file lawsuits.

Numerous states have already passed similar legislation creating “buffer zones” around religious buildings. In New York City, Mayor Zohran Mamdani vetoed a buffer zone for protests near schools and colleges, while allowing another one for religious institutions to pass.

Supporters of the federal bill argue that it is needed to protect worshippers from harassment or worse.

“Attacks on synagogues, mosques, churches, and other houses of worship are unfortunately on the rise in Michigan, and across the country,” Slotkin said in an August press release. “No one should ever fear going to their house of worship. Period.”

The law’s authors tout it as a narrowly tailored guardrail, but critics say that the “course of conduct” subject to fines and lawsuits is so ill-defined that the Trump administration could use it to target peaceful protesters.

“There is no relationship between this legislation and the prevention of violent acts at synagogues, mosques, or churches.”

One of critics’ top fears is the “religious services” protected by the law could be defined to include real-estate pitches for land illegally seized from Palestinian people in the West Bank. In a press release, the Anti-Defamation League cited two West bank land-sale protests in New York City as examples of the need for the legislation, along with the March ramming attack on Temple Israel in West Bloomfield, Michigan.

When it comes to violent attacks, argued Eli Williams-Szenes, the director of advocacy and political affairs at the progressive Jewish group Bend the Arc, synagogues are better protected by an existing federal law called the Freedom of Access to Clinic Entrances Act. The FACE Act makes a federal crime out of force, threats, or physical obstruction near both religious institutions and abortion clinics.

“There is no relationship between this legislation and the prevention of violent acts at synagogues, mosques, or churches,” Williams-Szenes said of the new bill. “The idea that telling someone that if they wave a pamphlet 97 feet from the entrance to a synagogue, they’ll get a $10,000 fine would be the reason that someone didn’t try to drive a car into Temple Israel is crazy.”

Abortion Rights Angle

The Right to Worship Act faces long odds in the final weeks of the Republican-controlled Congress. Still, Williams-Szenes said he is concerned that even a hearing could set the stage for eventual passage.

Abortion rights groups are also worried. They fear that if the Right to Worship Act passes, Republicans will be inclined to repeal or weaken the FACE Act because of its protections for abortion clinics.

One of President Donald Trump’s first actions upon taking office last year was to pardon anti-abortion rights protesters convicted of blockading a clinic under the FACE Act.

“The Right to Worship Act is a wolf in sheep’s clothing,” Kelsey Ryland, a policy counsel at the National Abortion Federation, said in a statement. “The impact of this policy could become a backdoor FACE Act repeal, weakening enforcement against violent disruptors at abortion clinics.”

The post Will Senate Religious Freedom Bill Actually Protect Land Sales for Israeli Settlements? appeared first on The Intercept.

💾

Euro-Office, the ONLYOFFICE fork, now has a desktop app

Euro-Office, the Nextcloud-backed fork of ONLYOFFICE, is now available to download and install on desktops as Nextcloud Office Desktop. Announced in March 2026, Euro-Office is a European-based alternative to Microsoft 365 and a fork of ONLYOFFICE. It’s currently something users can run and host (or pay someone to host) on a server, and then access via a web browser or mobile app. Much like ONLYOFFICE Docs. That’s no longer needed, Nextcloud Office Desktop is Euro-Office desktop client that installs and works like a traditional desktop office suite. You do not need to host a server or be online to use […]

You're reading Euro-Office, the ONLYOFFICE fork, now has a desktop app, a blog post from OMG! Ubuntu. Do not reproduce elsewhere without permission.

Euro-Office, the ONLYOFFICE fork, now has a desktop app

Euro-Office, the Nextcloud-backed fork of ONLYOFFICE, is now available to download and install on desktops as Nextcloud Office Desktop. Announced in March 2026, Euro-Office is a European-based alternative to Microsoft 365 and a fork of ONLYOFFICE. It’s currently something users can run and host (or pay someone to host) on a server, and then access via a web browser or mobile app. Much like ONLYOFFICE Docs. That’s no longer needed, Nextcloud Office Desktop is Euro-Office desktop client that installs and works like a traditional desktop office suite. You do not need to host a server or be online to use […]

You're reading Euro-Office, the ONLYOFFICE fork, now has a desktop app, a blog post from OMG! Ubuntu. Do not reproduce elsewhere without permission.

Trump Subpoenas Teachers Union for Info on Pro-Palestine Students

The Trump administration quietly broadened its crackdown on campus pro-Palestine protests over the summer, moving to ensnare one of the largest unions in the country in a case revolving around alleged incidents of vandalism.

The national headquarters of the American Federation of Teachers, or AFT, received a grand jury subpoena in August as part of an ongoing federal investigation into protests at the University of Michigan. Twelve pro-Palestine activists have been charged with felonies in the case.

The subpoena against the AFT, which has not been previously reported and was obtained by The Intercept, shows the administration casting a wider net in its investigation into student protesters than was previously known.

“They’re using this language around conspiracy and trying to draw in all of these different organizations.”

The Graduate Employees’ Organization, or GEO, an AFT local at the university, also received a notice to provide information and testimony to a grand jury around the same time, according to a copy of the previously unreported subpoena obtained by The Intercept.

The effort to draw a powerful, liberal union into a case that revolves around spray-painting charges represents a dramatic escalation in Donald Trump’s war on the left.

“They’re using this language around conspiracy and trying to draw in all of these different organizations that are taking stances against fascism, against the government, and anything that’s counter to their ideology,” said Natalie Chen, who serves as GEO’s communications director. “This is perhaps another ‘in’ for them to broaden their attack

on labor.”

Subpoenas to Crush Dissent

As pro-Palestine protests swept campuses across the country in 2024 and widespread demonstration broke out against U.S. Immigration and Customs Enforcement this year, the Trump administration has sought to paint left-of-center protest, nonprofit work, and labor organizing as a nefarious far-left conspiracy, even labeling some activists and groups as terrorists.

Critics of the administration’s crackdown on Palestine solidarity and protests against ICE see moves like the ones against AFT and GEO as part of an effort to silence dissent.

“Historically, federal grand jury subpoenas have been used against social movements and political dissent to gather information, to isolate individuals, and of course to try and prosecute people,” said Xavier de Janon, executive director of the National Lawyers Guild. “What is different in politicized cases is the extent of people and places that get subpoenaed, which many people see clearly goes way beyond what they’re supposedly trying to prosecute.”

Activists at the University of Michigan said the effort to extract information about students from the union was an attempt to further target pro-Palestine protesters and their relationships with labor organizers.

“What is different in politicized cases is the extent of people and places that get subpoenaed.”

The grand jury subpoenas came as part of a case that has seen a dozen protesters become caught up in serious federal charges against the students, dubbed “the Michigan 12.” They allege that protesters committed illegal acts like vandalism as part of a pressure campaign seeking to push university officials to divest school holdings tied to the Israeli genocide in Palestine.

The subpoenas against the GEO and AFT were requested by federal prosecutor Margaret Smith with assistance from FBI agent Kara Phipps — two federal officials deeply enmeshed in the investigation into the Michigan 12. (The Department of Justice declined to comment for this story.)

GEO Under Fire

The subpoenas were issued as the GEO was already reeling after its president, Hiab Teshome, was charged with felony embezzlement by local prosecutors working in conjunction with the University of Michigan Police Department.

Authorities alleged that Teshome, who was a bargaining team member in the middle of intense contract negotiations between the union and the school, misused organizational funds to purchase laptops for a campus club.

In a statement, the GEO called the charges meritless and characterized them as an attempt to limit protected union activity. Teshome was later cleared of any wrongdoing by the university’s student government, and the charges against her were thrown out by a judge.

Federal prosecutors issued the subpoenas the same day the charges against Teshome were dismissed, leaving activists little time to regroup.

Although GEO is not mentioned in the federal indictment against protesters, the AFT chapter is a prominent member of the Tahrir coalition, a pro-Palestine student collective that is referenced repeatedly in federal filings and characterized by prosecutors as having ties with defendants.

Broad in Scope

The scope of the information requested of the unions by the federal government is broad. GEO and AFT are being compelled, according to the subpoenas, to surrender information including complete membership rolls, payroll records on officers, reimbursement policies, audit reports, and all transcribed minutes on membership and executive board meetings of the University of Michigan local since January 2023.

The American Federation of Teachers has more than 1.7 million members and more than 3,000 local chapters.

After receiving the subpoena, GEO immediately obtained attorneys and filed a motion to quash the order. The national office of the AFT, however, has not publicly acknowledged receiving the directive or stated whether it intends to comply. (AFT did not respond to requests for comment about the subpoenas, including whether the union would be complying.)

Teshome, the GEO president, believes that the subpoena against the AFT may be an attempt by the federal government to circumvent the local union and force the national organization to comply.

“GEO has taken the stance that we will do everything in our power to protect the data and the information of our membership,” Teshome said. “I think that this is a strategy that the federal government is using in order to try to actually receive the information that they are trying to get by usurping us as a local union and going instead to AFT national.”

Additionally, Teshome likened the GEO’s case to similar surveillance activities conducted by federal agents against trade unionists in Minnesota as part of the Trump White House’s National Security Presidential Memorandum-7, a presidential directive that attempts to criminalize leftist political organizations.

“All of the repression we are seeing across the country is the federal government’s attack on anyone who has political thought,” Teshome said. “Michigan is no different than all of these other cases in that we are one of the testing grounds for NSPM-7 and how much oppression can be applied through the federal government in order to demobilize and disorganize.”

The post Trump Subpoenas Teachers Union for Info on Pro-Palestine Students appeared first on The Intercept.

💾

Oklahoma Drops Murder Charge Against Richard Glossip, Avoiding Third Trial

Less than a month before he was scheduled to stand trial a third time, accused of a murder he has always sworn he did not commit, Richard Glossip on Thursday agreed to plead guilty to a lesser charge, a final step toward bringing his three-decade legal saga to an end.

Glossip, 63, was twice convicted and sentenced to death for the 1997 murder of his boss Barry Van Treese inside Room 102 of the rundown motel the Van Treese family owned on the outskirts of Oklahoma City. A 19-year-old maintenance man named Justin Sneed admitted to killing Van Treese, but he insisted Glossip put him up to it. Sneed, who is currently serving a life sentence, escaped the death penalty by becoming the star witness against Glossip.

During a brief hearing that was originally scheduled to address pretrial matters, Oklahoma County Court Judge Natalie Mai instead accepted a plea from Glossip to accessory after the fact and dismissed the murder charge against him. With members of Van Treese’s family looking on from their seats in the jury box, Glossip stood to answer a series of routine questions to confirm that his plea was voluntary. Mai did not ask any specific questions about the crime itself.

Under Oklahoma law in place at the time of the killing, the maximum punishment for accessory after the fact was 45 years. Taking into consideration the decades Glossip spent on death row and credits earned for good behavior, Glossip’s attorneys say he would have been eligible for full release in 2016 and should serve no more time behind bars. But defense lawyers did not reach an agreement with the state as to a proposed sentence. In a statement released after the hearing, Oklahoma Attorney General Gentner Drummond, who once expressed deep concerns about the state’s case against Glossip, made clear that his office will be seeking additional prison time.

Ultimately it will be up to Mai to decide if Glossip should be sentenced to time served or if any additional punishment is warranted.

The contours of Glossip’s plea are remarkably similar to a behind-the-scenes agreement made in 2023 between Drummond and Glossip’s lead attorney Don Knight. At the time, Drummond told Knight that if a court were to overturn Glossip’s conviction, he would resolve the case by accepting a plea to accessory after the fact in exchange for time served – and a promise that Glossip would not sue Oklahoma for anything related to his arrest and incarceration.

“We believe Rich has more than paid his debt to society.”

But after the U.S. Supreme Court overturned Glossip’s conviction in 2025, finding that it was rooted in false testimony and prosecutorial misconduct, Drummond, who by then was running for governor, did an abrupt about-face, announcing he would once again prosecute Glossip for first degree murder.

In the year and a half since then, it has become glaringly apparent that prosecutors from Drummond’s office are grossly ill-equipped to take Glossip’s case to trial. Since his original trial in 1998, the state has lost or destroyed evidence, numerous witnesses have died, and prosecutors have conceded that their own star witness — who has sought to recant his testimony multiple times — can’t actually be expected to remember what happened the night of the killing.

“For 30 years, Richard Glossip has maintained his innocence,” Knight said in a statement after the hearing. “After nearly executing him 9 times, the State of Oklahoma has now dismissed the murder charge against him. This morning, to finally put this matter to rest, Rich pleaded guilty to being an accessory after the fact. We believe Rich has more than paid his debt to society.”

Glossip had originally been charged as an accessory after the fact for initially failing to give police information about the killing. The night Van Treese was killed, Glossip said, Sneed woke him up around 4 a.m. by knocking on the wall of his apartment, which was adjacent to the motel’s office. Standing outside with a black eye, Sneed told Glossip he had chased off some drunks who had broken a window in one of the motel rooms. According to Glossip, he asked Sneed about his black eye, and Sneed flippantly replied, “I killed Barry.”

According to Glossip, it wasn’t until the next morning, when Van Treese was missing, that he realized Sneed might have been serious. Still, Glossip didn’t tell the cops right away; he said his girlfriend suggested waiting until they figured out what was going on.

But Sneed told police Glossip was the mastermind behind the plot to kill Van Treese, and, with no other evidence tying Glossip to the crime, Sneed’s statement became the basis of the state’s case. At Glossip’s 1998 trial, prosecutors said that he had taken advantage of the younger, more vulnerable Sneed, offering him money to kill their boss so that Glossip could take over the motel. “Glossip encouraged, aided and abetted and sent Mr. Sneed off to do his dirty work,” then-prosecutor Fern Smith told the jury.

But this story began falling apart not long after Glossip arrived on death row. A video of Sneed’s police interrogation cast serious doubt on the state’s version of events, revealing coercive questioning by Oklahoma City detectives who pressured Sneed into implicating Glossip.

Glossip’s defense failed to present the tape to the jury, which led an Oklahoma court to overturn Glossip’s first conviction based on ineffective assistance of counsel. Although a second jury convicted him and sent him to die in 2004, doubts over Glossip’s guilt continued to grow.

Glossip subsequently came close to execution many times and may well have been executed if Drummond hadn’t intervened upon taking office in 2023. He ordered an independent investigation into the case, which concluded that rampant prosecutorial misconduct had infected Glossip’s conviction. Drummond asked the Oklahoma Court of Criminal Appeals to overturn the case. When that failed, joined Glossip in asking the Supreme Court to intervene, arguing that Sneed – whom the state has described as its “indispensable witness” – had lied on the witness stand.

Drummond’s concessions about the flaws in the state’s case and his unprecedented advocacy on Glossip’s behalf made his announcement in June 2025 that he would seek to retry Glossip for murder all the more shocking. According to Glossip’s lawyers, the decision also betrayed the long-standing agreement with Drummond to resolve the case and set Glossip free.

After that, Drummond essentially washed his hands of the case to focus on his ultimately failed attempt to become Oklahoma’s next governor, handing off prosecutorial duties to other lawyers in his office. Prosecutors declared that they intended to use the same discredited evidence to try Glossip a third time and spent months fighting to keep him in jail. Despite those efforts, Mai ordered Glossip’s release.

With a December 2026 trial date looming, tensions between the two sides have ratcheted up. Glossip’s lawyers have complained about prosecutors failing to turn over evidence as required under the law. Prosecutors have tried to limit what the defense can present to jurors at trial regarding the history of the case – including asking Mai to bar any mention of Drummond’s previous advocacy on Glossip’s behalf.

Glossip’s sentencing hearing is scheduled for December 17.

Since his release, Glossip has “been living a peaceful and law-abiding life,” Knight said in his statement. “We look forward to an opportunity to show why returning him to custody would not serve the interests of justice, and to ending this nightmare for Rich and all concerned.”

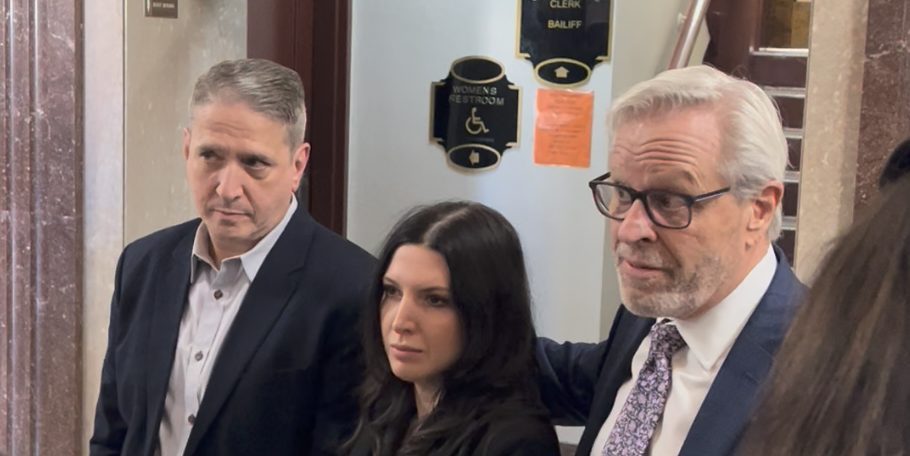
After the hearing, Glossip and his wife, Lea, stood with Knight to address reporters. Glossip thanked Knight and Lea for their support. “It was a hard day,” Lea told The Intercept, “but Richard and I are both people of faith.” She expressed that “today marks a meaningful step toward finally bringing this case to an end. We are both deeply grateful for the tireless efforts of his legal team.”

The post Oklahoma Drops Murder Charge Against Richard Glossip, Avoiding Third Trial appeared first on The Intercept.

💾

New Trump Rule Threatens Immigrant Families With Separation or Homelessness

The Trump administration is preparing to kick nearly 80,000 people, about half of them children, off federal housing assistance over their family’s immigration status, threatening to drive thousands into homelessness. 

On Thursday, the Department of Housing and Urban Development published a final rule that’s on track to effectively bar families of mixed immigration status from receiving most federal housing assistance, which allow people to receive housing vouchers to reside in privately owned rental homes or in government-owned or -assisted public housing units.  

As it stands, undocumented immigrants and temporary non-residents in the United States already are barred from personally receiving most forms of federal housing assistance. But if some members of the family are eligible, the eligible members can receive prorated assistance to help cover their housing, and the non-eligible family member can live with them.

The new rule, which goes into effect in mid-December, would disqualify an entire family if one member is ineligible after a temporary grace period, forcing them to choose between separation and eviction. 

Families are “going to be faced with the impossible choice of deciding whether they want to split up so that some people can stay housed, or to stay together and risk homelessness and eviction,” said Marie Claire Tran-Leung, Evictions Initiative Project director at the National Housing Law Project. 

Children will bear a disproportionate burden, Tran-Leung said. Of the nearly 80,000 people who could be affected, according to estimates from Center on Budget and Policy Priorities, nearly 37,000 are children.

Of the nearly 80,000 people who could be affected, nearly 37,000 are children.

Many families have one parent who doesn’t qualify, one parent who’s a citizen or otherwise eligible immigrant — i.e. a permanent resident — and kids who hold U.S. citizenship. According to Tran-Leung, the typical mixed-status family in HUD housing is a family of four that fits that profile.

This rule is “going to tear families apart and take adults away from their children,” said Deborah Thrope, chief program officer at the National Housing Law Project.

Beyond potentially leaving tens of thousands of families and children homeless or separated, the change could cost the already beleaguered federal housing agency hundreds of millions of dollars, housing experts told The Intercept. This would likely worsen conditions across the board for the roughly 9 million people in federal housing, who would now be subject to onerous documentation requirements. 

“The impacts are not just limited to mixed-status families,” said Renee Williams, senior advisor for public policy at the National Low Income Housing Coalition. 

This rule is “going to tear families apart and take adults away from their children.”

Currently, both U.S. citizens and non-citizens are required to submit a declaration under penalty of perjury attesting that their citizenship or immigration status makes them eligible for housing assistance. Non-citizens under age 62 must submit a document that proves their immigration status. And additional documentation can be requested by local housing agencies or landlords. 

The rule change would upend the current system. U.S. citizens would have to go through the Systematic Alien Verification for Entitlements program, also known as SAVE, to verify their eligibility status.

“It’s a system that hasn’t been used to verify citizenship before but now is because of the work that DHS and DOGE did together on a very expedited timeline at the beginning of the Trump administration,” said Tran-Leung. “This causes a lot of concern for us about the very significant risks of residents who are citizens being caught up in verification issues and potentially losing their housing.”

If SAVE cannot verify someone’s eligibility, the new rule requires the person to provide documentation proving their status. The rule would give families 30 days to obtain evidence of immigration status, in addition to the initial 30-day grace period where families can receive pro-rated assistance before having to go through verification.

Tran-Leung and other experts worry that the new documentation requirements could make it harder for low-income tenants — particularly older immigrants over the age of 62, who were previously exempted from verification requirements — to access the program.

Older people, low-income people, and people who’ve experienced homelessness are far more likely to lack access to proof of citizenship such as a passport, valid photo ID, or birth certificate. That means an untold number of the millions of eligible people in federal housing programs could lose assistance just for lack of documentation. 

“For folks who may not have easy documentation accessible, who may not have access to a birth certificate, who may not have access to a passport, we’re really worried,” said Williams. 

The changes would also burden housing agencies financially by requiring their staff to review documents that were previously not required by federal law.

It is unclear just how expensive these additional administrative costs will be for HUD. But an analysis from HUD itself found that because mixed-status families receive assistance prorated, it would cost the federal government $300 million in additional funds to serve the same number of families as it does now.

For example, a family of four with one ineligible member currently receives 75% of a full household subsidy. A family of four that is not mixed status receives 100% of the subsidy, making it more expensive for the agency to house the non-mixed-status family even though the two families have the same number of people.

“At the same time, HUD is requesting fewer funds from Congress to end homelessness,” said Kayla Blackwell, senior housing policy analyst at the National Low Income Housing Coalition. President Donald Trump recently proposed cutting $3.8 billion from the agency’s affordable housing, homelessness, and community development programs.  

HUD Secretary Scott Turner has justified the rule by claiming that mixed-status families are “pushing aside hardworking U.S. citizens” for housing. But experts said the changes will make the system worse for everyone.

“This is scapegoating immigrant families, and HUD is doing less,” said Blackwell. 

For the families who either are forced out of the program or leave willingly due to fears around their status, the road ahead is difficult. The majority of mixed-status families live in California, Texas, and New York, where the cost of living can be incredibly high.

“It’s going to be really difficult, I think, for families to be able to stay in their communities and not be displaced if they lose their access to HUD assistance,” said Blackwell. 

The post New Trump Rule Threatens Immigrant Families With Separation or Homelessness appeared first on The Intercept.

💾

Scottish Web Folk 2026: UX team reflections

With others from the Website and Communications team, Nick and Mel headed up to Dundee to attend the Scottish Web Folk conference. In this post, they share their reflections on the day.

Nick’s reflections 

This was my fourth trip to Dundee for the Scottish Web Folk conference and my third time presenting. Scottish Web Folk is a great chance to hear from people working in digital roles in higher education, and catch up with how people across the sector are approaching similar challenges. 

We presented about optimising content for AI summaries 

This year, Mel Batcharj, Katie Spearman and I presented about AI summaries, such as the ‘AI Overview’ that Google now presents at the top of a search results page. These summaries take information from our websites and repackage it for users, who in some cases no longer click through to the websites themselves. 

In our presentation, we talked about how to create content that is optimised for these summaries, and how we created a Content Improvement Club session to address this topic. 

We emphasised that much of the guidance for creating content optimised for search engines hasn’t completely changed in the age of AI. It’s still important to write clear, structured content that addresses user needs and presents people with the information they need to take their next step. It’s also still the case that following good  digital accessibility practices will help AI tools and search engines to process the information included in your content. 

Read Katie’s write-up of our  Content Improvement Club training session ‘Is your content AI ready?’ 

Speakers discussed the theme of ‘Human versus machine’ 

There were various talks looking at how we can use AI to support and inform our work with websites in higher education. 

In the panel discussion, Marta Krukowska (Web and Digital Manager at Bangor University) described her experiments with using AI tools to interview colleagues to gather information for course pages. If asked to describe their course, colleagues sometimes provided vague information. For example, they might talk about how the university provides access to “state-of-the-art facilities”. But the AI interviewer could push back and ask for the names of specific facilities, and what their availability means for students. This turned out to be a more efficient way to get the information needed to write marketing copy for a course. 

The panel also addressed questions of how prospective students are using AI tools to support their search for a university course. The discussion made me reflect on how difficult it can be to identify a starting point for a complex user journey like this. It’s easy to fall into the trap of thinking that a user journey is a linear process or a series of steps, but this frequently isn’t the case. When people are thinking about what they want to study and where they want to study it, there are typically a wide range of information sources feeding into that decision. The information is coming in from these disparate sources over a broad period of time. So it’s probably not accurate to say that the journey starts with an AI search, even if that forms part of the information environment that a prospective student is using. 

The Prospective Student Web team presented about their content playbook and how they’re appraising degree finder 

Two presentations I particularly enjoyed during the day were from our Edinburgh colleagues Lauren Tormey and Pete Watson. 

Lauren was presenting about how her team had put together a content playbook: a set of patterns that staff can follow when working with content. The playbook helps content designers to take a consistent approach when using page elements such as feature boxes, pull quotes and page summaries. It was interesting to hear Lauren’s account of how they found alignment within their team to produce the guidance in the playbook. I’d sat in one of the alignment sessions myself and liked how everyone had had a chance to put forward their views by editing the same page of content. In her talk, Lauren described how meeting up to discuss a piece of content helped to clarify shared standards and supported a more consistent approach to editorial work. 

Pete’s talk was about how he has been appraising the performance of Edinburgh’s degree finder. Pete used a scorecard similar to the one Lou Rosenfeld describes in his article ‘Stop redesigning and start tuning your site instead’. The scorecard lays out your most important audiences, and for each one, a prioritised list of their tasks and information needs. The final column on the scorecard is a grade for how easy it is to complete those tasks or find that information on your website. 

The challenge then was to find a robust way to give these grades. To do this, Pete created a set of marking criteria of the type you might see associated with educational assessments. With this in hand, he ran a series of usability tests to see how easily people could complete tasks on Degree Finder. The result was a table showing how effectively we’re supporting prospective students to complete their key tasks, and highlighting where further development effort is needed. 

Read Pete’s blog post about appraising the new postgraduate study website 

Thanks to the Dundee team for hosting the event 

As always, the day was brilliantly organised, with a wide range of interesting talks. We’re still learning about how AI is changing our use of digital tools, and this event was a good chance to reflect on how this is having an impact on those of us who work on websites in the higher education sector. 

Mel’s reflections 

This was my second time attending Scottish Web Folk in Dundee, but my first time presenting. I’d been looking forward to returning, as it’s always a welcoming room and a great opportunity to hear what others across the sector are working on. 

We took our AI research into a wider conversation 

Our session, ‘AI search summaries: a new lens on old content problems’, built on a Content Improvement Club training session we’d run recently. Preparing that training was the first time I’d really explored how AI relates to the content we produce, and it involved a lot of research. So it felt like a nice full-circle moment to bring some of that learning to Scottish Web Folk and share it as part of a wider discussion about AI. 

Our presentation focused on AI and content design, while some of the other sessions took a more technical angle. It was interesting (and reassuring!) to hear that our points resonated with others, particularly the idea that well-structured, maintained and accessible content matters for AI as well as for people. 

It was also a lovely surprise to find Claire Gregory from the University of Dundee in the room. Her UCISA talk, ‘Feeding the bot: making content work beyond the webpage’, had been a really useful source when preparing our training. 

Watch Claire Gregory’s talk: ‘Feeding the bot’ 

We also had questions about the training itself and how we get people involved. Our sessions have developed quite a bit over the past year, so it was nice to have a moment to reflect on that and chat about the process with a room of peers. 

Andrew Millar’s opening talk put AI in a wider context 

Beginning the day, Andrew Millar’s got us thinking about how we approach new technology. He took us through a timeline of major technological turning points, from the printing press to the web, and asked what became less scarce, what became more valuable and who lost out. With the printing press, for example, copying text became easier, but judgement and trust became more important. 

We’d actually considered using a timeline in our own presentation, so it was interesting to see a similar approach being used elsewhere. It felt like a useful way to tackle the AI elephant in the room, putting the changes we’re seeing into a wider context rather than treating AI as something entirely without precedent. 

A new acronym has really stuck with me from Andrew’s talk: GIGO, or ‘garbage in, garbage out’. It’s a simple idea, but an important one in the context of AI. If the information we’re putting out there isn’t good in the first place, we can’t expect the systems using it to produce reliable answers. Definitely relevant to what we were talking about! 

Andrew also talked about how, more than ever, we need to advocate for users who aren’t in the room. That really resonated with me. I don’t think the rise of AI search tools means we should start rewriting everything for bots. Rather, it’s another ‘audience’ to consider, while keeping our human audiences at the centre. The things we already think about as content designers (understanding user needs, using plain language and making content accessible) still matter.  

The morning panel discussed making university information work harder for prospective students 

The panel discussion was another highlight for me. I enjoyed the conversational format, which offered something a little different from listening to a series of presentations. 

A key part of the chat was around how prospective students’ questions go well beyond course details. They’re also thinking about the cost of living, student welfare and the practicalities of studying, including whether they’ll be able to work alongside their course. These priorities are changing, and universities need to be upfront about the answers rather than burying the lead. 

This is particularly important as AI search tools may draw on information from outside university websites, such as forums and online discussions. If universities don’t provide clear answers themselves, AI may turn to other sources that aren’t always accurate or complete. There’s an opportunity here for universities to answer people’s questions directly and reliably. 

I also enjoyed hearing about Marta Krukowska’s (Bangor University) example of using AI to introduce a bit of friction when gathering course information from colleagues. Rather than accepting vague descriptions, AI could push people to dig deeper and provide more specific answers. I liked this idea of using AI not simply to speed things up, but to challenge people to provide the useful detail that prospective students actually need. It was another example of finding a suitable use for AI that wasn’t about creating content. 

A day of shared learning 

Overall, it was a really good day and well worth the early start. The ‘Human vs machine’ theme could easily have made the day all about the latest AI tools and technologies. What I took away instead was how much of the conversation came back to the human side. 

Big thanks again to the Dundee team for hosting.

Arizona Town’s Probe on Sex Abuse Claims Could Block Prison Firm Building New ICE Camp

This story was published in partnership with LOOKOUT News.

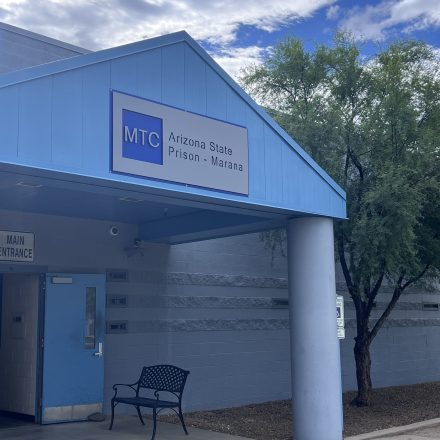
An official from Marana, Arizona, is seeking clarification from the private prison giant Management and Training Corporation about its handling of sexual abuse allegations at the former state prison in the town, following an investigation from LOOKOUT and The Intercept.

In an October 28 letter, reviewed by LOOKOUT and The Intercept, Marana Finance Director and License Inspector Yiannis Kalaitzidis asked MTC Senior Vice President Mary Calvin for a written explanation of what the town official called an “apparent inconsistency” between state records and the facility’s 2023 Prison Rape Elimination Act, or PREA, audit, a report required by the federal law.

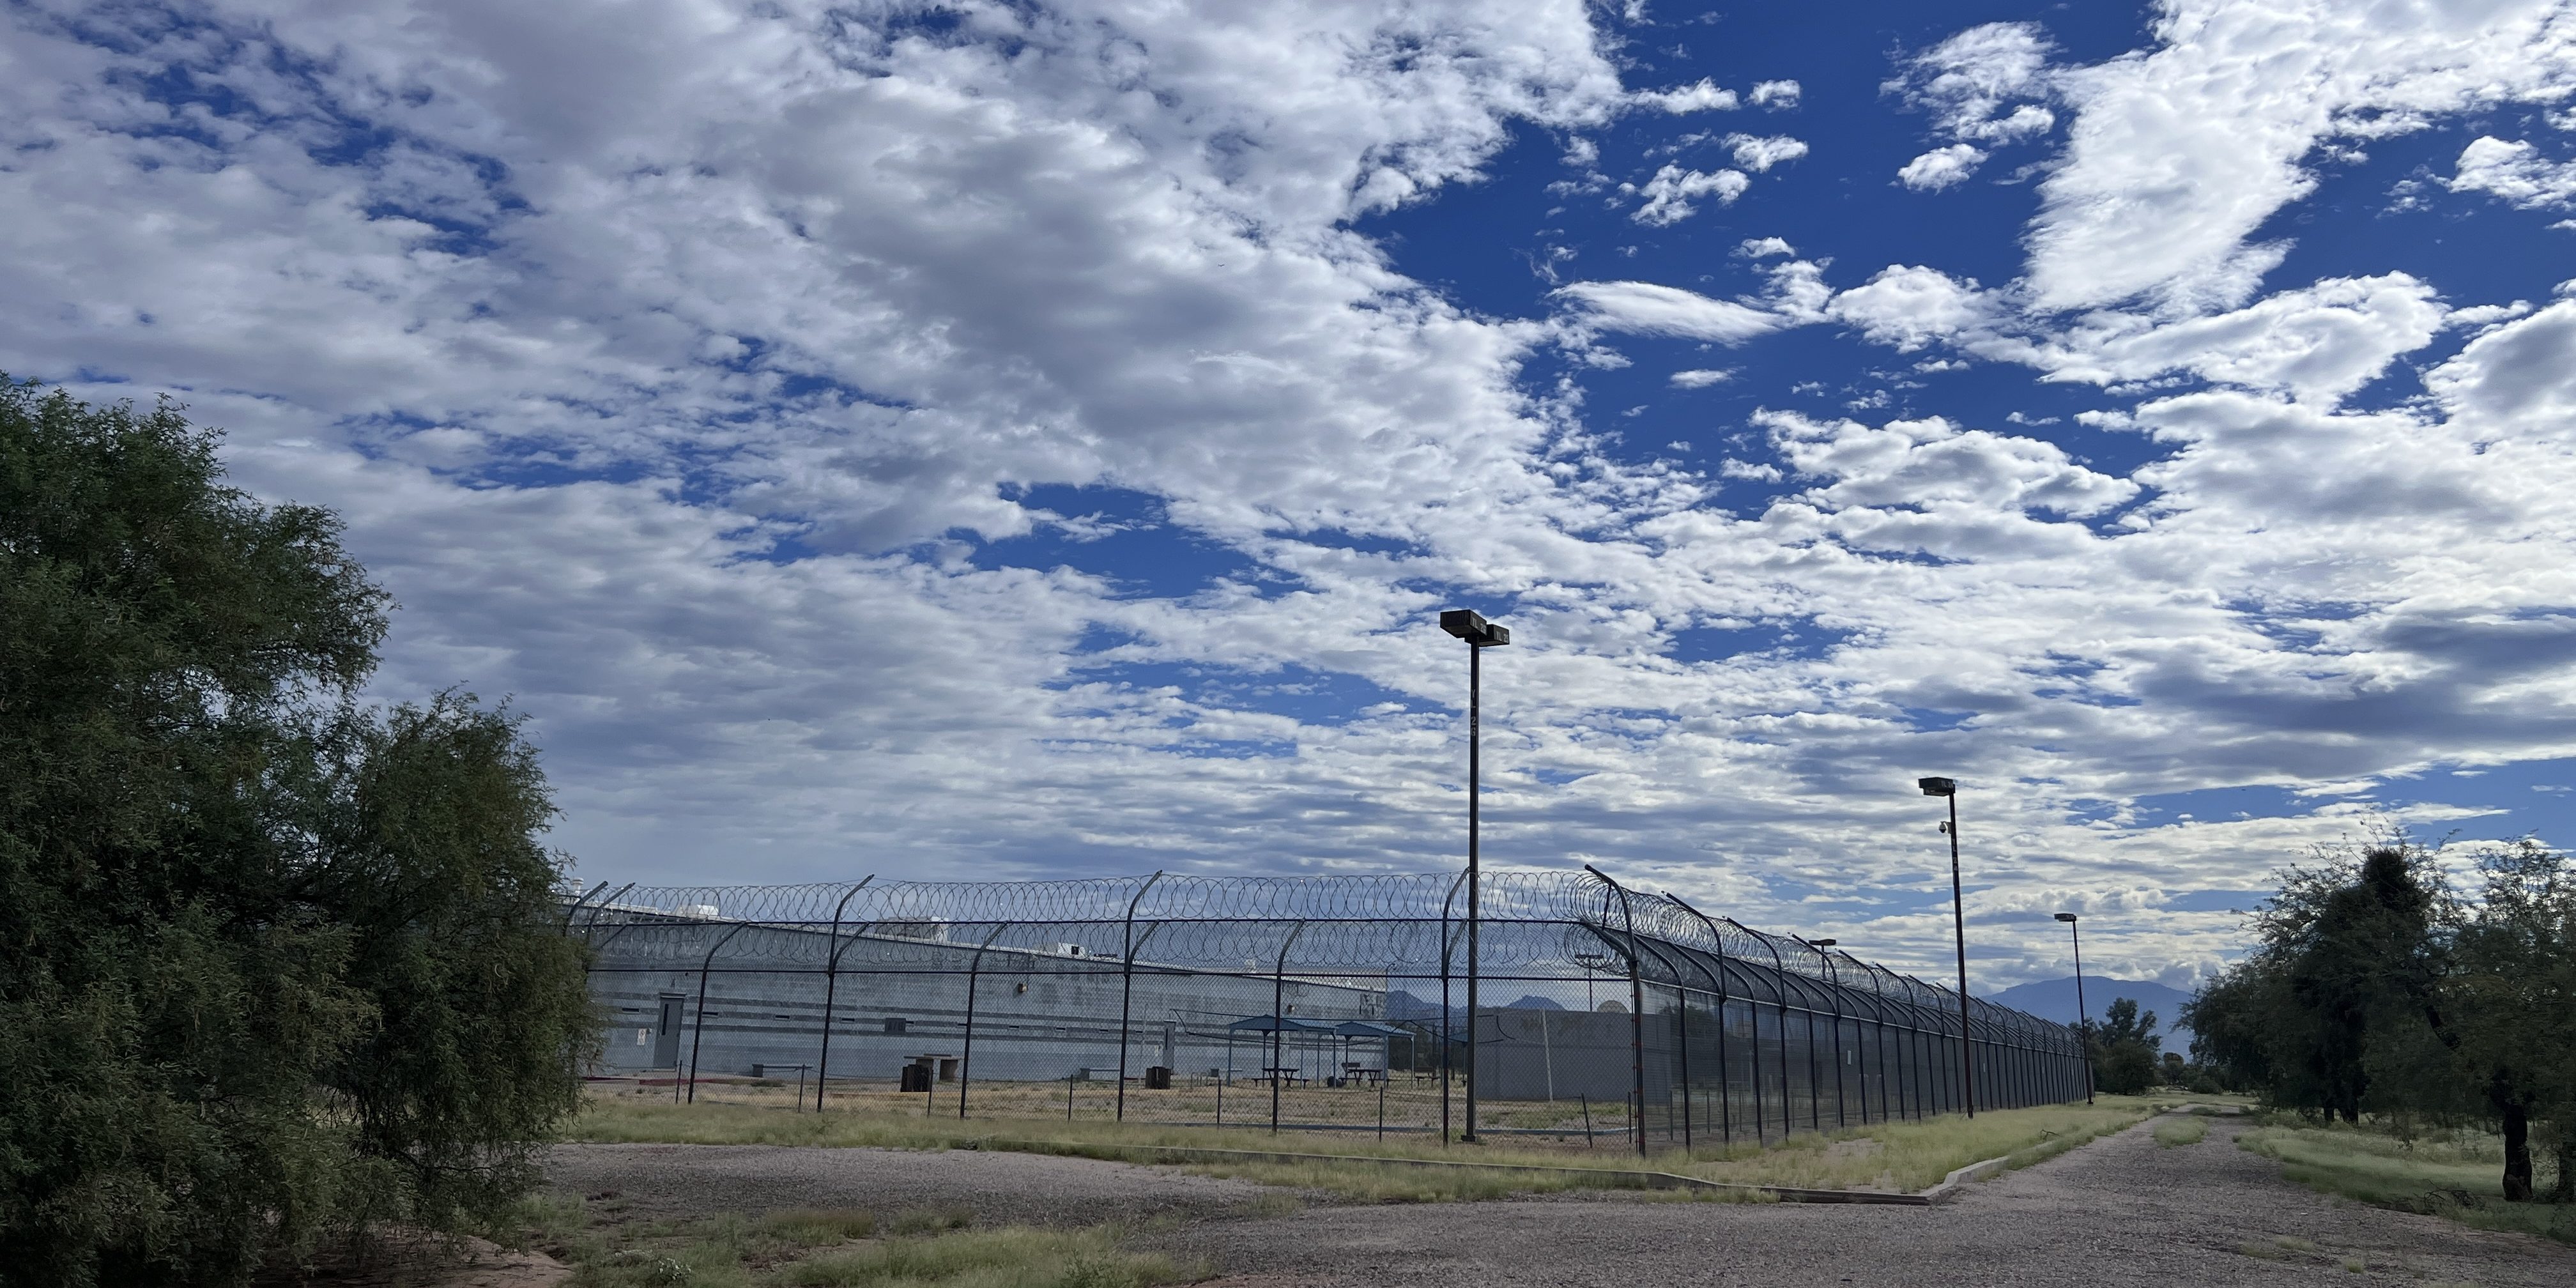
MTC ran a former state prison in Marana, Arizona, and plans to reopen it as an ICE detention camp.

The request is part of the town’s review of MTC’s October 1 application for a business license to “Operate Marana Detention Facility.” The company ran a former Arizona state prison in Marana and plans to reopen it imminently as a U.S. Immigration and Customs Enforcement detention camp.

The letter cites a September 29 LOOKOUT and Intercept investigation about how state records reference three allegations of sexual misconduct at the prison in 2022 and 2023. 

PREA audits — which are required for jails, prisons, and detention centers at least once every three years — must record all allegations of sexual misconduct at detention facilities, whether they are substantiated or not. Certified in December 2023, MTC’s report for the Marana prison, however, recorded none. 

Kalaitzidis noted in his letter that the audit says the finding of zero incidents was verified by the warden, chief of security, PREA compliance manager, and internal investigator. He also wrote that, despite the apparent reviews by several company officials, the report “does not appear to be certified or signed by any MTC personnel.”

The letter says the town of Marana is requesting the explanation as part of an investigation into whether MTC “made a material false statement in conducting the business” of the state prison facility, which would be grounds for denial of a business license according to the town’s code.

“The Town of Marana is currently reviewing MTC’s business license application,” said Andrea De La Cruz, the assistant town manager, told LOOKOUT and The Intercept by email. “As part of our review process and due diligence, the Town has contacted MTC to request additional information. The application remains under review, and no final determination has been made at this time.”

MTC did not respond to multiple requests for comment.

Changing Political Context

Local residents and officials say the state, the federal government, and MTC left them out of meaningful discussions about reopening the prison as an ICE camp, LOOKOUT and The Intercept previously reported.

For now, a town business license is among the few levers local officials have.

In an October 2 letter from the local group Pima Resists ICE, or PRICE, to a Marana official who specialized in licensure, organizers cited not only the discrepancies between state investigations into sexual abuse and the PREA audit, but also alleged violations involving an escape from an MTC prison in Kingman, Arizona, in 2010, as well as abuses in a New Mexico immigration camp run by MTC as revealed in a 2017 DHS Office of Inspector General report.

The inquiry comes as Arizona’s political landscape is shifting. The midterm election gave Democrats control of both chambers of the state legislature as well as the governor’s office — a historic change in state power. Republicans will be in the minority at the state Capitol for the first time in 60 years.

That has Democratic lawmakers talking about taking on one of the most contentious laws in recent Arizona history. Following protests across the state, Democrats took up the cause of repealing a controversial 2010 anti-immigrant law known as Senate Bill 1070. In 2012, the U.S. Supreme Court struck down three of its provisions, leaving a requirement that police check the immigration status of people they stop under certain circumstances.

“I would absolutely love to see a repeal of SB1070,” state Sen. Analise Ortiz, a Democrat from Glendale, told LOOKOUT and The Intercept. “There are still parts of that law on the books that are enabling cities to collaborate with ICE to rip families apart, and that needs to stop.”

State Rep. Betty Villegas, D-Tucson, echoed Ortiz: “We already have bills aligned to focus on what other states have done to control ICE from coming into private property.”

Following the lead of neighboring New Mexico’s prohibition on local jurisdictions entering into contracts with ICE for immigrant detention camps, Villegas said Democrats in Arizona see an appetite for doing something similar in their own state.

“We do not want the Democrats to wait until things get bad to investigate conditions.”

Ortiz agreed, saying there is “likely an appetite” for something similar in Arizona, and that the Latino Caucus would address the issue.

Local nonprofits said lawmakers should also conduct a review of no-bid contracts like the one inked between the Department of Homeland Security, ICE’s parent agency, and MTC. 

“This was literally handed to them with no review and no public input,” said Caroline Isaacs, the executive director of Just Communities Arizona, a nonprofit working on criminal justice reform. “We do not want the Democrats to wait until things get bad to investigate conditions.”

“We want them to do this now, before people get hurt.”

The post Arizona Town’s Probe on Sex Abuse Claims Could Block Prison Firm Building New ICE Camp appeared first on The Intercept.

💾

How to create consistent content using the editorial style guide: What we covered in October’s Content Improvement Club

We’ve been refreshing the editorial style guide to make it more useful for colleagues across the University. In October’s Content Improvement Club, we explored why consistency matters, what’s changing and how you can use the guide in your own work.

You can read more about the reasons behind the project in Nick Daniels earlier blog post:

Why we’re refreshing the editorial style guide

Using the editorial style guide to make consistent decisions

The editorial style guide helps us make consistent decisions about how we write and present information. It’s designed to help us create content that’s more accessible, readable and inclusive.

Editorial style guide

It covers a range of everyday editorial decisions, including:

  • when to capitalise something and when not to
  • how to spell words that have multiple possible spellings
  • how to explain abbreviations and acronyms

Exploring consistency through examples

In the session, we started by looking at some everyday editorial decisions to explore how the style guide can help us create consistent content.

How we write the University’s name

We looked at the different ways we might write the University’s name. It’s surprising how many variations we can come up with for something so familiar.

But using different versions can be confusing, particularly for people who don’t know the University as well as we do. A name is an important part of our identity, so we need a shared approach rather than everyone deciding what feels right.

Luckily, we don’t have to guess. The editorial style guide provides clear guidance (the correct wording is the University of Edinburgh).

University terminology style guide page

A slide with the question 'What are we called?' in the centre. A group of blue squares surrounds this, containing a variety of ways people have referred to the University of Edinburgh. These include 'UoE', 'Edinburgh Uni', 'Edinburgh University' and the correct version, 'The University of Edinburgh'.

How we write dates

We also looked at some of the smaller editorial decisions we make every day, using dates as an example. We showed four date formats in a poll and asked attendees which they would naturally use when writing University content.

Our options were:

  • A) 27/10/2026​
  • B) 27 October 2026​
  • C) 27th October 2026 ​
  • D) 27th Oct 2026  ​

Looking at the options, we discussed how it’s not that one format is universally right and all the others are wrong. Different formats can be appropriate in different contexts. For University content, though, we’ve agreed to use option B) 27 October 2026. Following the same convention helps us keep our content consistent, wherever it appears.

Dates and days editorial style guide page

Why consistency matters

Having looked at some practical examples, we asked attendees why they thought consistency was important when creating content. Using sticky notes, people shared their ideas. There was a lot of overlap between the reasons they identified and the ones we’d thought about beforehand.

One reason is brand reputation. We want people to recognise us as one University, wherever they come across our content. Using consistent terminology and conventions helps build that recognition and trust.

Consistency also supports readability and accessibility. Familiar, predictable formats make content easier to scan, understand and use.

It contributes to clarity and accuracy, too. Having an agreed approach helps avoid confusion and makes it easier for people to understand the information we’re sharing.

Finally, consistency helps create a joined-up user experience. Whether someone is visiting our website, reading an email or looking at social media, we want their experience of the University to feel connected.

Putting the style guide into practice

The session was a little different from some of our previous Content Improvement Clubs. Rather than spending most of the time presenting guidance, we wanted to give attendees the opportunity to explore the style guide for themselves.

We included two practical activities to help people get familiar with the guide.

Exploring the guide through example pages

We looked at two mocked-up webpages we’d created. Both contained deliberate editorial inconsistencies and mistakes. Attendees explored the guide for themselves, find the relevant sections and use the guidance to identify possible improvements.

They used sticky notes to highlight things they’d spotted and consider what they might change. This included things like flagging unexplained acronyms, link text that needed to be placed on a new line and incorrectly formatted bullet lists.

A page titled 'Tuition Fees and Loans for Students from Scotland' with eight sticky notes annotating issues with the content. These include comments like 'Use sentence case for page titles', 'Do not use all caps for emphasis' and 'Explain acronyms on first mention'.

The first example of a mocked-up page used in the session

A page titled 'Sports clubs' with 11 sticky notes annotating issues with the content. These include comments like 'Use -ise endings instead of -ize endings', 'Avoid ampersands' and 'Bullet list items do not end in punctuation'.

Second example of a mocked-up annotated page from the session

This gave everyone a chance to become more familiar with the guide and see how it can support everyday decisions when creating and editing content.

Where should you start with the style guide?

One thing we hear from colleagues is that there’s a lot to remember in the style guide. It can be difficult to keep every convention in mind when you’re busy creating and maintaining content.

Our advice was not to try to remember everything. Instead, we suggested starting with four priority areas:

  • Acronyms and abbreviations
  • Headings
  • Links
  • Dates and numbers

These are useful areas to focus on when reviewing your content. It’s also worth asking someone else to read it over. A fresh pair of eyes can often spot inconsistencies or things that you might have missed.

Reviewing our own content with other publishers

For our second activity, we used these four priority areas as a starting point. Attendees worked in breakout rooms to look at content from their own websites. People took turns sharing their screens and reviewing each other’s content.

The breakout rooms generated some interesting discussions about the practical challenges of applying editorial guidance. For example, we talked about using links within bullet lists and how much information to divide into separate headings and sections.

These decisions don’t always have a straightforward answer. The important thing is to think about what works best for the people using your content and use the guidance to help inform your decisions.

The activity also gave publishers a chance to get feedback from colleagues they might not usually work alongside and look at their content from a different perspective.

Experimenting with ELM to check content against the style guide

In the session, we also talked briefly about whether ELM (the University of Edinburgh’s AI innovation platform) could help publishers check their content against the editorial style guide.

We haven’t always had reliable results when using ELM for this purpose

As John Wilson explored in his February 2025 blog post, ELM can sometimes identify errors and correctly explain why they don’t follow our guidance, but it can also miss other errors or refer to guidance that doesn’t exist.

Testing ELM’s ability to return useful results and prompts about the editorial style guide

A text-based Markdown version of the style guide is what we’ve tested more recently

We’ve been experimenting with giving ELM the style guide as a text-based Markdown file. This means it can use the actual guidance to check a webpage against, rather than relying on its existing knowledge.

We tried this approach with the two mocked-up pages used in the session. ELM was able to identify the majority of the deliberate inconsistencies, although it still missed some issues, including an example relating to capitalising ‘University’ when referring to the University of Edinburgh.

It’s an interesting experiment, and one we’re continuing to explore. While tools like ELM may be able to help identify potential issues, they should not replace checking the guidance yourself and using your own editorial judgement.

We shared a couple of examples of what we’ve been working on in the guide

It’s been a big undertaking working through each section of the guide. We wanted to give attendees a flavour of the work by looking at a couple of examples.

Bringing University-specific terminology together

We’ve expanded the previous ‘Referring to the University’ page into a broader University terminology page. You can read more about the development of this page in our blog post:

Creating a new style guide page on University terminology

Restructuring the punctuation guidance

We’ve also restructured the punctuation guidance into separate pages.

Punctuation section of the editorial style guide

Previously, much of this guidance was grouped together using accordions. We wanted to move away from this format, which can make content less accessible and harder to navigate.

We’ve reviewed how the different topics are grouped, too. For example, colons and semicolons now sit together, making it easier to compare the two and understand when to use each.

Separating the guidance gives us more flexibility to provide the right level of explanation and include examples where they’re most useful, without simpler guidance getting lost among more detailed sections.

Keeping the guide up to date

We want the editorial style guide to remain a useful, living document rather than something we publish and leave untouched.

Alongside those mentioned in this blog post, some of the changes we’ve made to the guide have been much smaller tweaks or clarifications. We’ve been logging changes on the guide’s updates page, so if you’re interested in following how it continues to develop, you can see what’s changed there.

Updates page (editorial style guide)

How to hear about future Content Improvement Club sessions

We promote these sessions via our mailing list. If you’re interested, please sign up:

Join the UX and Content Design mailing list (University login required)

Suggest a topic for a future session

We’re keen to continue covering topics that colleagues across the University would find useful. It would be really helpful if you could let us know any ideas you have using this form:

Suggest a topic for Content Improvement Club (University login required)

Other training that we offer

More training is listed on the User Experience Service website:

Training | User Experience Service


Just do it for me? Balancing human and AI input in content improvement

Working with student interns and contributing to the Drupal community, I’ve experimented with AI in various  tools designed to support content improvement. I reflect on what I’ve learned about peoples’ preferences for engaging with AI tools and consider wider design challenges for web content to support co-browsing.

Writing good quality, user-centred content has always been a challenge, and accordingly, a suite of tools evolved to address this; Hemingway, Grammarly and many more. With their ability to learn patterns and predict word sequences, the advent of LLMs provided a new direction for content improvement. Where previous tools had used fixed rules, algorithms and formulas to flag content problems and score sentences, LLMs changed the playing field as they were able to be prompted to rewrite and create text and to adapt words and sentences not only in line with fixed rules, but also aligned to different interpretations of style.

The UX Service’s content design course, Effective Digital Content, and our ongoing Content Improvement Club meet-ups are both designed to help staff publishing digital content for the University. It’s been encouraging to see a positive uptake for both training formats, however, we realise we can do more to help staff publish the best quality content they can, and to this end, for the past few years it’s been a privilege to support a series of interns in the UX Service to look at how we can innovate and apply AI to the persistent challenge of writing good quality, user-centred content.

Thinking beyond – embracing the spirit (or grasping the nettle, depending on how you look at it) of AI innovation, it’s sensible to note that, more broadly, the browsing landscape of the web is increasingly shifting to include AI agents as well as humans, giving cause to consider what using AI to design content to be consumed by AI might look like. That’s the subject of another blog post (or several).

For now, as I begin another phase of work with a new student in the role of AI and UX Innovation intern (Viktor Sharha), it felt timely to pull together what I’ve learned so far.

Designing, creating and editing content happens in various ways

When designing any user-centred assistive features, a good place to start is the current workflow or user journey people adopt to achieve the task in question. In other words, to look at the stages content editors currently go through to make sure their content is as good as it possibly can be.

One of my earliest research tasks when I joined the University was to usability test the Editorial Style Guide, to find out how publishers used it to keep their content consistent in EdWeb. This work gave me insight into the type of workflows publishers followed to get compliant content published. Some publishers worked in Microsoft Word, using the in-built spelling checker for typos, and cross-checking against a printed-out copy of the style guide for University-specific errors before pasting content into the EdWeb body text. Others went straight to EdWeb, checking their content line-by-line with a PDF version of the guide. Others relied on colleagues giving their work the once-over before pressing publish. Some used Grammarly and Hemingway, some didn’t.

Overall, there wasn’t a dominant content-publishing workflow, with unified friction points waiting to be alleviated through a standard user-centred design process. Instead, there were varied approaches, habits and ways of working which people had adapted over time to suit their specific circumstances and to address the areas they found difficult as individuals. Tools were used at different stages of the process, and to a greater or lesser extent depending on personal preferences.

Therefore, designing content improvement tools isn’t one-size-fits-all

It follows that, since people follow different pathways to create, design and edit content, tools to assist this process need to be developed in different ways to suit varied preferences. Since 2025, interns in the UX team have prototyped our own different content improvement tools to test with publishers, and we’ve also tested open-source tools that exist already, developed within the Drupal community. From our testing and research, we found pros, cons and nuances associated with different tools. The summary below pulls together detail of the tools and how they compared.

Tool 1: Drupal Editoria11y – no AI, flags errors in the editing interface

Editoria11y is a Drupal module built by John Jameson from Princeton University that automatically checks content inside the editorial interface. It was originally designed to catch accessibility issues, but it can be configured to check content against other rules too, such as institutional style guide conventions.

What it does and how it works: Editoria11y checks content as authors type, and also on previews and published pages. It includes an indicator bar to show how many issues are on the page and has inline markers to show where each issue is, as well as a dashboard summarising site-wide errors. When an issue is opened, a pop-up modal explains the problem and suggests a fix.

What worked well: In tests, publishers were able to make sense of the inline markers and understand how these related to the indicator bar for the whole page. They liked the tracked change visualisation in the pop-up modals, and were able to work through successive modals, accepting or ignoring the suggested changes.

What needed improvement:  Some publishers found the number of markers overwhelming, and since the pop-ups covered the text, it was difficult to judge each recommendation in context. In the pop-ups, some of the rule descriptions used formal grammatical terms (such as ‘ordinal suffixes’) which were unfamiliar to some publishers meaning they were confused about the problem to be fixed. Since rules were applied mechanically, there were instances where errors were missed, or where awkward fixes were suggested (such as swapping ‘1st floor’ for ‘1 floor’ due to straight removal of the ordinal suffix) – these degraded publishers’ trust in the tool.

Read more about what we found testing Drupal Editoria11y

Embedding the rules: What we learned UX testing a style guide helper tool built with Drupal Editori11y

Tool 2: ELM-powered content design chatbot – with conversational advice

This tool was developed by student Mostafa Ebid during a 2025 summer internship. It connected ELM, the University’s AI platform, to EdWeb2, so publishers could get help with their content by conversing with the University’s suite of LLMs without leaving the Drupal editing interface.

What it does and how it works: This tool sits in a chat sidebar next to the main Drupal editorial interface and offers three modes: Write Content, Design Content and Proofread. In response to a user prompt to improve content, it activates an orchestration of agents (each with specific tasks such as checking the style guide, structuring pages, profiling audiences) which read the page content and act on it accordingly, publishing the revised content in the chatbot window.

What worked well: In tests, publishers understood how the tool could be used as a writing partner, and were impressed with the way it restructured content with headings, bullet points and calls to action and hyperlinks.

What needed improvement: When faced with the empty chatbot interface, some publishers weren’t sure where to start, and they didn’t notice the three modes to work on content. Some were also unsure of the sources the chatbot was using for its revised content and skeptical that the revised content contained hallucinogenic content. They would have appreciated tracked changes to be able to pinpoint what had changed and found the long thin sidebar chat interface awkward to review the updated text. The chatbot was also limited to reviewing body text content, whereas publishers needed it to review content in other page components used in Drupal.

Read more about what we found developing and testing the ELM-powered content design chatbot:

Initial insights from UX testing our Drupal AI content assistant tool

Tool 3: QuillMark v1 and v2 – some AI, clusters errors with correction suggestions

QuillMark was an AI-enhanced tool which worked in Drupal to check content against the University’s Editorial Style Guide. Shlok Gupta built and tested two iterations of Quillmark during his 2026 summer placement as AI and UX Innovation Intern.

What it does and how it works: QuillMark sits in a side panel of the Drupal editorial interface and scans content on the page in two stages. The first stage uses code-based pattern matching (without AI) to catch straightforward errors. The second stage brings in AI to find deeper issues (such as passive instead of active voice) and to suggest fixes. Findings from both stages are displayed in the side panel – each finding describes the problem, links to the relevant rule in the style guide and offers an ‘Apply fix’ button (which can be reverted). Findings are grouped by category, and this panel also includes an indicator of the environmental impact and cost of the scan.

What worked well: In tests, publishers understood that the tool was there to help them correct content on the page, they liked the environmental and cost indicator, the suggested fixes and the links to the style guide reassured them that the tool was applying University-specific rules.

What needed improvement: Publishers reported feeling overwhelmed by the number of findings on a single page and they wanted a way to deal with related findings and fixes in bulk, to avoid going through them one-by-one. Related to this, they wanted

Read more about what we found developing and testing the QuillMark tool:

QuillMark, iterated. How user research helped us evolve an AI-enhanced Drupal style guide assistant

Tool 4: Drupal AI Content Review – full AI, with a plan provided to improve content

As part of the Drupal AI Initiative, I’ve contributed to shaping the self-explanatory Drupal AI Content Review module. This module plugs into a Drupal site, references content rules and good practice from context items in Drupal Context Control Center (within the same site) and uses the configured AI provider to review site content

What it does and how it works: The feature reads the page content and checks it against criteria set by the site owner, such as tone and voice guidelines, inclusive language rules and target readability levels. These rules are stored in the Drupal Context Control Center, along with examples of good and bad content. The review gives the page a score for each criterion and recommends fixes to improve it. Accepted recommendations become an improvement plan, which is applied in the editorial interface. Re-reviewing the page shows the updated scores, with the option to keep making improvements. Over time, the rules can be refined by adding more examples of good and bad content to the Context Control Center.

Read more about Drupal AI Content Review on Drupal.org

Read more about the Drupal Context Control Center on Drupal.org

View a demonstration of AI Content Review in a mocked-up university website as part of the Drupal AI demo on the Drupal Forge platform

What worked well:  In tests of this module within the AI demo, people liked seeing the red, amber and green indicators against page content for an easy visual highlighting areas to be worked on, and they liked being able to select a checklist of recommended improvements to apply to improve their content.

What needs improvement: The screens explaining the recommended improvements were difficult to scan read, and it was also difficult to compare the original text and the text with the recommended improvements side-by-side (despite colour shading to denote which was which). The stage where the recommendations were turned into an improvement plan felt like an unnecessary extra step, it would have been better to have implemented the recommendations directly. Also, it was presumed that implementing the plan would have corrected all errors resulting in a score of 100%, without the need for further work and re-review. Finally, it wasn’t immediately clear how to use the Drupal Context Control Center and the AI Content Review together.

When designing AI-enhanced tools, consider three AI design maxims

Taking on board variations in blending human effort and automated operations, there are three approaches to designing AI features and AI-assisted workflows worth considering. These are defined below, with ideas for how they may apply to content improvement.

1.      Human-in-the-loop

In this set-up, humans typically share the task-load with AI – actively working alongside an automated operator to supervise or influence actions, and to approve AI decisions before they happen (ensuring AI outputs are not released without the green-light from a person).

Human-in-the-loop tends to be adopted when:

  • there is a need for human judgement to get something correct
  • the consequences of an error could be high-profile or damaging
  • trust in an automated tool is still being built, and the boundaries of its capabilities are still being realised
  • the goal is for the system to facilitate shared learning between the person and the automation

For content improvement, human-in-the-loop is appropriate in these scenarios:

  • ensuring correctness of important factual data – for example, prices, dates, contact details, terms and conditions
  • checking the tone of sentences in line with inclusive language guidance
  • verifying accuracy of high-stakes published content such as legal information, policy wording or written instructional content
  • rewriting complex topics in plainer language
  • writing meta descriptions or page summaries to be accessed by search mechanisms
  • translating content into other languages

2.      Human-on-the-loop

These systems involve the AI or automator acting on its own, with the human reviewing and spot-checking at intervals, monitoring output quality over time, and intervening to correct failures periodically, where required.

Human-on-the-loop tends to be adopted when:

  • there is a high volume of low-risk tasks to be completed, which would be tedious for humans to do themselves
  • consequences of errors are minimal
  • there’s a need for tasks to be completed quickly, and including human-input at each task would be too time-consuming
  • consistency is required across tasks, and there’s a risk of human error introducing variability

For content improvement, human-on-the-loop is appropriate in these scenarios:

  • fixing straightforward style rule violations such as correcting spelling errors
  • categorising and tagging text content (for example, to facilitate its discovery in search)
  • scanning content for readability and accessibility, to flag or report areas to be addressed

3.      Human-out-of-the-loop

In this arrangement, the human sets up the AI to act autonomously, and leaves it to proceed, with no routine review.

Human-out-of-the-loop tends to be adopted when:

  • there are very low-risk, behind-the-scenes tasks to be completed where errors have little or no consequence and can be fully reversed

For content improvement, human-out-of-the-loop is appropriate in these scenarios:

  • autocorrecting typing errors
  • detecting content duplication
  • auto-optimising media content to defined parameters

Choice, pacing and transparency are constant design requirements

Testing four different tools has showed that options always need to be available, whatever balance of human and AI the tool includes. People approach AI differently based on preferences and past experiences. Some love nothing more than a good grappling of a sticky sentence, some just want an agent to do the work for them, and many sit somewhere in between, happy to have some AI help as long as they have the final say.

Alongside humans in, on and out of the loop, it’s important to remember the fourth option: human only, where people can choose to do their content unaided, using the methods they relied on before AI came along. AI shouldn’t be forced on anyone, so all tools need to come with a ‘no thanks to AI’ option.

AI is a fast-evolving and non-deterministic technology, so at any point in time it may work differently to the way it did before.  Responding to challenge from a design perspective, it’s important to factor in pacing. People need to be taken through how a tool works, and the options available. They need time and space to experiment and try it out, so they can learn for themselves how it can work for them. Pacing not only matters in the way tools are introduced, but also in the way their outputs are presented, to avoid the overwhelm that comes when AI does the heavy lifting all at once, and so people know what changed and how, and they have a way to accept, decline or edit what it produced.

If people don’t trust an AI tool, they won’t use it. Earning trust requires transparency, explainability, relatability and reliability – so AI tools need to be upfront about what they can and can’t do, with clear, intuitive interfaces and labels. Reliability will always be hard to promise given AI is probabilistic, so instead of accuracy guarantees which may fall short, a better approach is to design for experimentation, so people can find their feet and make their own judgements.

Designing for humans and AI together – metadata, markdown and MCPs

Looking at the broader digital landscape, the challenge widens from designing tools that help humans make content to designing websites with content ready for both humans and agents to use.

In co-browsing, people are increasingly arriving at a website with an agent alongside them, handing off some tasks while keeping control of others and wanting to see what their agent is doing. That means firstly deciding which tasks belong to humans and which one to AI, and secondly designing for each. Humans need intuitive interfaces. Agents need data they can read and act on without ambiguity:

  • metadata, such as schema markup that tells an agent what a page is about, who it’s for and how it connects to other content
  • markdown versions of pages and llms.txt files, which give agents clean, structured text without layout and navigation getting in the way
  • MCPs (Model Context Protocol servers), which let sites expose what they can do as well as what they say, from simple actions declared directly in HTML to more complex ones written in JavaScript – in preparation for use by the emerging WebMCP browser standard.

Labels matter for humans and agents alike, because words are becoming a currency that machines read as well as people. Alignment on terminology facilitates the creation of a single source of truth, to prevent the human experience from drifting from the agentic experience. On another level, humans need a way to consistently communicate with AI – to give AI the rules and instruct it and to train it with new insight. ‘Rosetta stone’ mechanisms like the Drupal Context Control Center will play an important part in designing for human and AI interaction and collaboration and I am excited to keep working and researching in this area to address these evolving design challenges.


Show me your sources! What students make of content provenance data, AI signifiers and sparkles

The line between human-made and AI-generated content is blurring fast. I added a disclosure indicator to an AI-powered search tool and tested it with students, which taught me about perceptions of AI-influenced content and what signals authenticity. I reflected on the need for a shared language around provenance and disclosure.

Estimations of the proportion of AI-generated content on the web vary and are becoming progressively difficult to measure. New legislation advocates for disclosure of AI use, but the nuances of communicating how AI has been used within a feature, and detailing the finer points of the provenance of AI-generated content both remain a challenge.

Earlier in 2026, I took part in a study to design a C2PA provenance indicator into a prototype AI searchbot. I revisited my designs to test them with students, to assess if this authenticity data made sense and to understand its impact on students’ potential trust of the AI searchbot. In this blog post, I describe what I tested and what I learned, and make broader considerations of designing with provenance data, the impact of AI legislation and what makes people trust AI features.

People’s trust in technology depends on explicit and implicit factors

The ISO 9241-210 standard for UX defines user experiences as ‘a person’s perceptions and responses that result from the use of anticipated use of a product, system or service’, which sums up the influence trust can have on the way a person experiences a technology.

I was interested to explore more about the relationships between human trust and AI, so I read a selection of papers on the topic and extrapolated four factors that commonly affect how people trust AI technologies:

  1. Transparency (surface and presumed credibility)
  2. Reliability (earned and reputed credibility, how consistently it works and how dependable it is)
  3. Explainability (how clear the purpose of the AI is and how clear it is how it works)
  4. Relatability (how well the AI supports the person’s interests, how easily they can use it and how it resonates with them)

When it comes to designing AI features people trust, and communicating how AI has been used within those features, it’s important to try and convey each of these factors in ways that make sense to the user in context. In other words, striking a delicate balance of providing sufficient trust indicators to allow people to make reasoned judgements, without going overboard and running the risk of confusion or skepticism.

The EU AI Act has set out obligations to disclose AI usage

From an ethical perspective, advising people that they’re using an AI feature has always been the right thing to do, in order to foster a sense of user trust. Legislation published in August 2026 made the requirement to disclose AI usage more explicit and provided more detail. Article 50 of the EU AI Act details Transparency Obligations for Providers and Deployers of Certain AI systems and includes recitals which cover areas including the following:

  • Designing AI systems to ensure users know they are talking to AI
  • Marking content from AI systems (text, images, videos, audio) so it is detectable as such
  • Informing people of AI systems that include emotion recognition or biometric categorisation
  • Disclosing deepfakes (audio/video/image content that has been manipulated as well as public-interest text, unless human-reviewed with editorial insight) as AI-made
  • Clarity, timing and accessibility of AI disclosures – to be provided at the first interaction or exposure and to be clear and accessible.

With this legislation now in place, it’s anticipated that a growing number of ways to disclose AI usage will emerge, making AI disclosure as mainstream as AI features.

I adopted the C2PA digital content provenance standard into an AI searchbot prototype

When it comes to icons that disclose AI usage, sparkles, neurons, and robots are all widely used, but they only signify that AI is present or available, they don’t provide any detail of how it has been used or how it has shaped content. C2PA is an established provenance standard which has been designed to convey progressive levels of content provenance data. I incorporated C2PA to disclose how AI was used to shape synthetic chatbot responses in a search feature and wrote about my process in an earlier blog post:

How can people trust AI-generated content? Designing provenance data into our prototype AI searchbot

I concluded this design work with a resolve to test my designs with users to understand the following:

  • if they cared about seeing provenance data about the AI searchbot response
  • if they grasped the concept of provenance data
  • if they understood what the C2PA Content Credentials icon signified
  • if the names for the different categories of data made sense to them

Drawing on my recent reading into trust factors, and taking into account the new EU AI disclosure guidance I also wanted to use my designs to understand more about how users make sense of AI features, and what affects their trust of them in context.

Testing revealed students’ responses to progressive levels of AI disclosure in the searchbot

In a simple test, I asked the student participants to imagine they were in a scenario where they had used the AI searchbot to find information from a website. I then showed them mock-up screens with the indicator in progressive levels of disclosure, going from the C2PA ‘CR’ logo, to ‘content credentials’, ‘About this response’, ‘Certification data’, ‘Digital source data’ and ‘Transformation processing data’. At each stage, I asked them to speak aloud to describe what they saw, what they thought it meant, and how it resonated with them.

Screenshot showing the AI searchbot interface showing all the provenance data available

Screenshot showing the AI searchbot interface with progressive levels of provenance data on display

The C2PA icon was unfamiliar but content credentials made more sense

Students’ first exposure to the provenance data was as the C2PA ‘cr’ icon which was displayed at the opening interface of the searchbot (when the searchbot was ready to receive a user query). On its own, the icon was pretty meaningless to them. One felt it could be a watermark, others thought it was a button to make the chat window bigger, others said they would Google ‘cr’ to find out what it was. The next level of disclosure was a signifier that read ‘content credentials’, which appeared once the searchbot had received a query and produced a response. Students found this indicator more meaningful – they felt it was a way to verify where the response came from, and said they would be inclined to press it to find out more.

The level 1 disclosure ‘About this response’ was too vague to be useful

When asked what they thought they would find in the section ‘About this response’, students were largely unsure. Some thought it would contain a hallucination warning, others thought it would contain sources. When they read the generic descriptor about the C2PA provenance data, which explains that the response was AI generated and had content credentials and assertions to demonstrate authencity, they felt it was too vague to be useful to them, and didn’t feel it was telling them anything new. They were unfamiliar with ‘content credentials’ as a term and by the language, they reasoned that this message was aimed at a legal team rather than someone reading the output of the searchbot.

‘Certification data’ wasn’t a term that resonated with student participants

Reading the label ‘certification data’ students had mixed ideas of what this section would contain. Some felt it would reveal intellectual property details, some thought it would show licensing agreements relating to data entered in the searchbot, and others thought it would explain how the searchbot handled data. There was a further expectation that this section would contain the sources behind the searchbot response.

When they expanded this section to see the identity data (name of the organisation certifying the content) and the associated timestamp of when the content was certified, they were unclear what was being certified (the output of the searchbot or the AI model), and how they would use this information. Some reasoned that the responses from the AI searchbot were stored in a database and that this certification data could help keep track of a bank of these responses.

‘Digital source data’ made more sense to them

Of all the data categories displayed, ‘Digital source data’ was the one students gravitated towards. This is where they assumed they would find the links to the sources used to create the AI searchbot response, and their assumptions were correct. For many students, seeing the links to the sources proved the authenticity of the AI content more strongly than any other sections of the data they had seen. As well as the source links, this section included the C2PA Actions assertion (which recorded the stages used to create the digital content (or asset) including the AI model used). Students recognised the AI model but questioned the terminology ‘Actions assertion’, thinking it would be more straightforward to just list the AI model used.

In the ‘Transformation processing data’, detail of the AI prompts was of particular interest

Preconceptions of what they would find in the ‘Transformation processing data’ section varied from a logical set of steps to show how the responses were formed from source data, to details of how data inputs would be used to train AI models, to sustainability data showing energy expenditure in the formation of the AI searchbot responses. When they saw information labelled ‘Search mechanisms’ which detailed how embeddings were created and a vector database was used in semantic matching, most students felt this was too much technical detail. Some who were familiar with the process felt this section would be more appropriately labelled as a technical stack, rather than search mechanisms. The ‘Transformation processing data’ section also contained the AI prompt, and most students responded positively to this, saying they felt it gave them a fuller picture, it helped them understand ‘the personification of the AI’ and made the process more transparent.

The effectiveness of my C2PA designs largely depended on students’ existing knowledge

Reviewing the findings together, I concluded that my designs partly succeeded in communicating details of how AI had formed the searchbot responses, but this depended on students’ perceptions and what they knew already, as well as what they wanted to know. Overall, my designs fell short when it came to instilling a sense of trust in the students, largely due to unfamiliarity with the C2PA terminology, the challenges of targeting implicit trust factors and the partic.

Students familiar with AI responded positively, but others wanted a non-AI option

The C2PA indicators focused on the provenance of the AI-generated searchbot responses, but for some students this was irrelevant as they wanted a choice to be able to not use the AI feature at all. Several students were skeptical and negatively pre-disposed to AI features based on their previous experiences and concerns about the environmental cost, and therefore upon seeing the sparkle icon realising the searchbot was AI-powered they were sought for a way to turn it off, or to make a choice about whether to use it or not. This reinforced the need to ensure AI features are a choice, and in the case of the AI searchbot example, an alternative way to achieve the same task is provided.

The C2PA terminology was off-putting to students

As they read the data in the different categories, students felt alienated by some of the C2PA language, particularly terms like ‘content credentials’, ‘provenance’ and ‘assertion’. When they were able to see contextual detail associated with these terms, most were able to fathom what the terms meant, but I concluded that including these terms in the designs and in the labels of the different data categories was giving students an extra unnecessary hurdle of jargon to overcome before they could reach an understanding of the data presented to them.

Some C2PA data was clear and useful, other data felt unnecessary

The four categories of data resonated differently with the students, and, based on their reactions, some of these data sources felt unnecessary to show data provenance.

Most students found the source links useful, and what they expected in the category labelled ‘Digital source data’. They also found the AI prompt useful, but they didn’t expect to find it in ‘Transformation processing data’. Almost all felt the notification that the response was AI-generated (in the ‘About this response’ section) was unnecessary. Other data points that students felt confused and nonplussed by included the ‘CR’ logo, the identity data, the certification data (including the timestamp), and the technical terms describing the response-generation process.

Some of the data students were expecting was missing

As they reviewed the different categories of data they were presented with, students commented on data they would have expected to see. This included: environmental impact data, information about how input data would be used to train AI models, and details of how the data was processed and held by the searchbot feature. While these data points largely fell out of the realm of content credentials, it was interesting to understand the types of data students looked for when making judgements about whether to use and trust this type of AI feature.

The C2PA designs targeted some trust factors but not others

Re-examining factors that affect trust highlighted that trust is heavily influenced by implicit factors or emotional cues which are specific to individuals. Targeting subjective trust factors such as relatability, (which depends on how well something supports a person’s interests and resonates with them) was very difficult to achieve without research to understand the nuances of the target audience. Some students were reassured by the mention of AI models involved in generating the content, but for others, this merely caused confusion.

Targeting explicit trust factors like transparency and explainability in displaying content provenance was more straightforward, but it meant striking a balance. Providing too much technical detail about the production process, although this was intended to build trust by being upfront, could end up causing confusion and therefore result in the opposite effect, as I observed in the student tests.

Conveying reliability remains a challenge when AI is involved. Since AI is probabilistic, its results are variable, and in the context of a feature like an AI searchbot, it was not possible to make assurances in the provenance data. Instead, I used the progressive disclosure levels to encourage exploration and a gradual building of understanding, to help people come to their own conclusion about whether to trust the AI-generated content. I saw this working in the student tests, as they made reliability judgements about the AI responses when they saw the source data revealed.

Provenance indicators should replace the sparkles and it’s time for a unified AI vocabulary

The C2PA standard is several years old, yet content provenance is still a relatively unfamiliar concept. With new AI legislation published and the advent of more formalised requirements to disclose AI usage and application, I predict more rhetoric and discussions around disclosure, authenticity and provenance, to evolve the language and terminology around these concepts and to make them more mainstream.

Those who consume AI-generated content want to know how it was made, and the sources it came from, and those who use AI to generate or shape the content they publish have an obligation to disclose how AI was used, to ensure transparency from both perspectives. When designing AI features, consistent labelling will play an growing part in conveying meaning. As people become more familiar with AI, they will rely on these labels more and more to make judgements and decisions about AI features and AI-influenced content.

This small study has re-emphasised the importance of choosing terms and wording labels carefully, to strike a balance between technical and non-technical and to provide just enough detail to resonate with audiences but not so much that it confuses them. It highlights the need for a unified vocabulary for AI, to effectively communicate about its usage and application. As AI usage progresses, I expect provenance indicators and associated design patterns to continue progressing, and I’m keen to keep a close eye, to keep iterating on ways to display provenance data. I look forward to seeing sparkles replaced by more meaningful signifiers of AI usage and disclosure.

“Offensive Driving”: ICE’s Deadly Weaponization of Vehicles Against Civilians

As Miguel Parra Hernandez, a Mexican national, was fleeing from U.S. Immigrations and Customs Enforcement on foot last month, he turned into a parking lot. An unmarked government vehicle came screaming into the lot after him and struck him.

When a grand jury in Harris County, Texas, charged the U.S. Immigrations and Customs Enforcement officer behind the wheel last week, the indictment pointed to a broader pattern in the Trump administration’s crackdown on immigrants and activists. The charge was assault with a deadly weapon; the weapon was the vehicle.

The Department of Homeland Security, ICE’s parent agency, claimed Parra Hernandez ran in front of the government vehicle; surveillance footage of the incident shows him running away from the car moments before he is hit. (An attorney for the ICE officer accused of assault against Parra Hernandez told The Associated Press his client had not committed any crime.)

In the same month, an unmarked ICE vehicle speeding the wrong way down a one-way street in Long Beach, California, struck a bicycle ridden by Ricardo Gonzalez, whose daughter later said he was a U.S. citizen. An agent immediately drew their gun on Gonzalez, who was later hospitalized for his injuries. The government said the man was not struck, but video released by the New York Times showed the ICE vehicle swerving into the bicycle.

Three days later after the collision in Long Beach, Antonio Moreida stood in the street in Woodland, California, outside Sacramento, documenting an unmarked ICE vehicle when the black Chevy Tahoe accelerated toward him. When the SUV hit him, Moreida told a meeting at Woodland City Hall last week, he was knocked to the ground — and the driver of the Tahoe did not stop to check on him.

The Department of Homeland Security said Moreida jumped onto the hood of the unmarked car, but when video of the incident showed him standing in place, local police and the mayor publicly disputed ICE’s account.

Weaponized Vehicles

In the national conversation about ICE’s heavy-handed crackdown on immigrants across the country, much has been made of the Department of Homeland Security’s claims that immigrants and activists “weaponized” their vehicles against federal agents. After immigration officers shot and killed Lorenzo Salgado Araujo, who was targeted by ICE, and community defender Renée Good in separate incidents, the government said the civilians had used their cars to attack agents — allegations that have not been borne out in criminal charges, or were called into question by witness accounts and video analysis.

What happened to Parra Hernandez, Gonzalez, and Moreida, however, was the opposite of what the government said about Good and Salgado Araujo: It was ICE agents who weaponized their vehicles against civilians.

As the Trump administration ramped up deportations over the last year, federal agents have effectively turned their cars into massive, deadly blunt objects. Common tactics, known collectively as “offensive driving techniques,” include ramming the cars of immigrant targets and activists; “brake-checking” volunteers trying to observe ICE activity; and, in some cases, outright driving into civilians. The Intercept reviewed two dozen cases of ICE using vehicles against civilians in these ways, including multiple incidents where victims were hospitalized or even died from their injuries.

“Vehicles are another tool ICE agents are using with unchecked force, just like their guns, Tasers, and pepper spray.”

“Vehicles are another tool ICE agents are using with unchecked force, just like their guns, Tasers, and pepper spray,” said Hannah Stauss, co-director of Hands Off NYC, a group that opposes ICE’s presence in New York City. “ICE’s deranged use of vehicles effectively weaponizes them against our immigrant neighbors and rapid responders, and will continue to kill people. We are witnessing in real time the results of a federal agency being allowed to operate with impunity, in secrecy, and with unfettered violence.”

In a statement to The Intercept that compiled past responses to the incidents in this article, a spokesperson for the Department of Homeland Security said, “ICE is instituting additional training including, crowd control measures, additional training for high-risk vehicle stops, a live-fire cover course for officer safety, and medical training.”

The spokesperson did not respond specifically to allegations about the incident involved Parra Hernandez; said Gonzalez was not struck by an ICE car; and blamed Moreida for the accident because he was in the roadway.

“Offensive Driving Techniques”

In federal policies and memos, the maneuvers used in the incidents reviewed by The Intercept, along with testimony from rapid responders, are referred to by federal agents as “offensive driving techniques.” They are part of a wider patten of aggressive driving by law enforcement officers across the country, but especially by federal agents with little accountability and nearly blanket backing from the Trump administration.

Last October, Leo Martinez was monitoring immigrations agents’ activity as a volunteer with VC Defensa, a community defense group in Ventura County, California, when an unmarked ICE car rammed his pickup truck. ICE agents arrested Martinez and later released him without charge.

In March, they did it again: Three unmarked government vehicles rammed Martinez’s car as he sought to reverse away from them. The federal agents broke his window and dragged him out. Martinez, who was hospitalized from his injuries, was again released without charge. (The Department of Homeland Security spokesperson did not respond specifically to questions about the incidents involving Martinez.)

“They run stop signs, red lights, they’ll cut off complete intersections, and they rarely turn on their lights,” Martinez told The Intercept. “They’ll slam on their brakes in the middle of the freeway, in the middle of the street. Sometimes they’ll do sudden U-turns in the middle of nowhere and cut off traffic in both directions.”

When activists are monitoring federal agents, one of the most common ways for ICE to leverage their vehicles as physical threats is the “brake check,” a move where a car suddenly breaks to cause the car behind it to slow down — or slam into its rear bumper.

“Brake-checking” doesn’t appear in official guidelines as an “offensive driving technique” with good reason: It is considered to be illegal in all 50 states, covered by various statutes like reckless driving or other anti-road-rage laws. Yet VC Defensa volunteers, who like Martinez monitor ICE activity, said that when they follow ICE vehicles to alert the community with horn-honking, they keep a distance of two to three car lengths because federal agents so frequently brake-check volunteers.

Federal agents use “offensive driving techniques” so often in Ventura County that VC Defensa volunteers sometimes identify the unmarked cars by the body damage that characterizes them.

Customs and Border Protection, another agency that, like ICE, is under the umbrella of the Department of Homeland Security, expanded its agents’ discretion and ability to use these techniques during abduction operations after President Donald Trump took office for a second term.

A previous 2023 Customs and Border Protection pursuit policy largely prohibited officers from boxing in vehicles or making vehicle contact with another vehicle in motion. A partially redacted 2025 CBP directive gives officers broader discretion to use offensive driving techniques and ignore traffic laws.

“Most federal agencies are not well trained in police-citizen interactions, traffic stops, and pursuits.”

“Most federal agencies are not well trained in police-citizen interactions, traffic stops, and pursuits,” said Geoffrey Alpert, a criminology and criminal justice professor at the University of South Carolina who helped Customs and Border Protection rewrite their car-chase policy under the Biden and Obama administrations.

In December, ICE agents in Elgin, Illinois, chased a Venezuelan man until his car and the ICE vehicles crashed. State investigators found the ICE agents likely conducted an “unskilled precious immobilization technique (‘PIT maneuver’) and lost control of the vehicle.” (The Department of Homeland Security spokesperson said the target of the raid rammed an ICE vehicle into a tree.)

In January, Christian Molina, a U.S. citizen, was preparing to pull over for an ICE traffic stop in Minneapolis when the agents rammed the back of his car, injuring his back. The agents said they would pay for the damage, but left without providing contact information. (The Department of Homeland Security spokesperson did not respond specifically to questions about the incident involving Molina.)

In June, agents conducted a high-speed chase through a residential neighborhood of Chicago, blowing through intersections until finally ramming their target’s car. (The Department of Homeland Security spokesperson blamed the target of the immigration enforcement action for the accident because he fled from ICE.)

“It’s disheartening to see some sort of federal agents or law enforcement driving so aggressively in a residential area,” one neighbor told Block Club Chicago. “I have a kid who’s two and we go out for walks all the time. We could have been crossing the street when they came through the intersection.”

High-Speed Chases

Following the killings of Lorenzo Salgado Araujo and Johan Sebastián Durán Guerrero in July, the Department of Homeland Security ordered a temporary halt to traffic stops.

The day the directive was issued, ICE chased a group of roofers in Texas, blowing through a stop sign and over a speed bump without sirens. A mother driving her son to the theater was forced to swerve into a ditch to avoid a collision.

“They speeded right next to me,” the mother told the Texas Observer. “They hit the speed bump so bad that, when they got in front of me at high speed, I had to go to the right.”

If she had not swerved, she said, “they would have hit me.”

Some of these car chases have turned deadly in the very places where local police are restricted from chasing suspects because of the attendant dangers.

In February, agents undertook a high-speed chase in pursuit of Oscar Vasquez Lopez outside of Savannah, Georgia. Vasquez Lopez’s car struck a teacher, killing her.

The Savannah Police Department only allows pursuits when the suspect has committed or is attempting to commit a forcible felony, and the risk of not capturing someone outweighs the risk of the chase. Vasquez Lopez had no criminal record, only a civil deportation order from 2024.

Two immigration car chases in New Jersey, where police face similar restrictions at the statewide level, resulted in hospitalizations. (In the Texas case, the Georgia case, and the New Jersey case, the Department of Homeland Security spokesperson blamed the target of the immigration actions for causing unsafe conditions by fleeing.)

“They are not required to follow local agency policies (the same as other agencies), but they must be held responsible for their actions under state and federal law,” Alpert, the criminology professor, said. “The failure to evaluate these behaviors in a full, complete and transparent manner leaves us all in the dark.”

Earlier this month, the AP reported on an internal memo to ICE’s Enforcement and Removal Operations division that banned agents from conducting high-speed car chases. The directive still allows trained agents to make traffic stops and undertake offensive driving maneuvers.

Ramming Pedestrians

ICE agents’ vehicles are not just recklessly pursuing and ramming vehicles driven by who they thought were targets for immigration enforcement. In multiple filmed interactions, agents have driven into pedestrian rapid responders and protesters.

In Woodland, California, ICE agents crashed into Moreida as he sought to collect their license plate information. After a major workplace raid in Los Angeles in June 2025, a news helicopter filmed the moment a protester walked in front of several ICE vehicles. One slowly sped up until it knocked him to the ground.

“It’s a disproportionate use of force. An individual is not going to win a fight with a vehicle,” Alpert, the criminology professor, said. “I’ve never seen any state or local law enforcement ever use a vehicle properly to hit or to run into a civilian.”

In other incidents, federal agents have weaponized their vehicles against crowds of activists. (Asked about the protests incidents mentioned in this article, the Department of Homeland Security spokesperson blamed “anti-ICE agitators.”)

In the aftermath of an ICE shooting this month in the New York City neighborhood of Marble Hill, immigration agents were seeking to move a man with a gunshot wound — whose car, with his 5-year-old son in the back, smashed into a concrete barrier during the incident — from a hospital to a detention facility. As government vehicles left the hospital in a speeding caravan, a bicycle was nearly hit by an federal agent in a black vehicle, which honked its horn, according to video of the incident. In another social media post, an ICE agent in an unmarked vehicle continued driving even with six protesters walking in front of it.

In July 2025, in San Francisco, after ICE clashed with protesters while moving detainees from the immigration courthouse to unmarked vehicles, several protesters clung to the hood of the car until they were physically thrown off when the vehicle sharply accelerated.

“It is honestly only a matter of time until an ICE agent seriously injuries or kills a cyclist or pedestrian in New York City.”

“I absolutely worry about ICE agents hurting people or killing people with these aggressive driving maneuvers,” said a New York rapid responder. “In order to avoid having their movements in vehicles documented, ICE agents will dramatically accelerate far beyond safe speeds for a dense urban environment like New York City.”

The organizer, who requested anonymity to avoid retaliation from the government, reported that agents drive at high speeds into oncoming traffic, run red lights, and abruptly turn without signaling. They rarely use emergency lights or sirens. These tactics align with the pattern of behavior described by Martinez in California — but in a city where rapid responders and neighbors are more often on foot or riding bicycles, not in their own vehicles.

When ICE agents brought a detainee to a Brooklyn hospital after a violent arrest in May, hundreds protested outside the hospital. One TikTok video from the night captured the moment an unmarked ICE vehicle drove into several gathered people, accelerating sharply until they leapt out of the way.

“Given the frequency with which these agents are engaging in aggressive maneuvers to try and lose rapid responders or prevent documentation of their movements,” the organizer said, “it is honestly only a matter of time until an ICE agent seriously injuries or kills a cyclist or pedestrian in New York City.”

The post “Offensive Driving”: ICE’s Deadly Weaponization of Vehicles Against Civilians appeared first on The Intercept.

💾

💾

The Intercept reviewed more than two dozen incidents of ICE using its army of unmarked cars to attack immigrants and American activists alike.

Fergie Chambers Faces Extradition to U.S. Despite Never Being Indicted, Says Lawyer

The Trump administration’s extradition case against millionaire left-wing donor James “Fergie” Chambers, detained in Spain since July, ran into an apparent hurdle when two witnesses called before a federal grand jury announced their intention last week to refuse to testify.

Several observers familiar with the case said the grand jury is likely related to the extradition effort.

The refusal of the grand jury witnesses to testify takes on added importance because the U.S. is pursuing Chambers’s extradition based on a criminal complaint, not an indictment, according to his Spanish lawyers. The criminal affidavit, signed by a single FBI agent, includes three charges related to his support for pro-Palestine causes.

The distinction, critics of the extradition case say, highlights how the case is hung on one agent’s complaint, which remains under seal, rather than a grand jury investigation to determine if the state had sufficient evidence to indict Chambers.

“The complaint is not only vague and weak, it’s not normal,” said Aitor Martínez, one of Chambers’s Spain-based lawyers. “In 20 years of practice, I’ve never seen a U.S. extradition request based on a criminal complaint.”

Martínez pointed to a statement from a summary of the complaint contained in an international arrest order reviewed by The Intercept and directed at Spanish authorities that says, “If Chambers’ extradition to the US is granted, another charging document called an indictment will be sought from a federal grand jury.”

“In 20 years of practice, I’ve never seen a U.S. extradition request based on a criminal complaint.”

Xavier de Janon, the executive director of the U.S.-based National Lawyers Guild and who is not working directly on the Chambers case, said, “Seeking an extradition without there being an indictment puts the cart before the horse.”

“If he is extradited under a criminal complaint,” said de Janon, “he can’t even fully challenge the charges, because he hasn’t been indicted.”

The State Department referred questions to the Department of Justice, which declined to comment.

Two of the three charges underpinning the extradition request against Chambers — riot and incitement to riot — are related to allegations that he helped fund a late-2023 protest in Merrimack, New Hampshire, against an Israeli weapons manufacturer, according to the summary of the complaint contained in the arrest order. The summary says Chambers provided funds for demonstrators used to purchase materials such as smoke bombs and to help cover protesters’ legal fees.

The third charge is international money laundering related to more than $7 million he transferred to bank accounts in Tunisia, where he was living in 2024. The Trump administration, according to the international arrest order, says the money was used to fund Hamas, which is a proscribed terror group in the U.S. The order does not say he is charged with material support for terrorism.

Chambers’s family and supporters and multiple representatives of Club Africain, a Tunisian soccer club, have said the money was used to pay the club’s debts and related expenditures such as training grounds. The club’s fan base has long supported Palestinians.

Grand Jury Refusal

Two women who participated in the 2023 protest against a factory operated by the Israeli weapons manufacturer Elbit Systems recently announced their intentions not to cooperate with a November 4 grand jury hearing where they have been summoned as witnesses.

“If they are being summoned now, this suggests that the grand jury seems to be linked to Chambers’s case,” said Martínez, his lawyer. “It seems like a fishing expedition against him.”

Kira Kelley, an attorney for the two women, said, “Context clues suggest this is about Fergie.”

If the pair don’t answer questions from a federal prosector before the New Hampshire federal grand jury, they could risk a possible jail sentence for contempt.

Nonetheless, the two women — Bridget Shergalis and Sophie Ross — shared a statement with The Grayzone Thursday announcing their intention to refuse to testify. In an interview on the same day with The Intercept, the women recounted being under investigation for a year over the protest and being threatened with felony charges that carried potential sentences of decades in prison.

Shergalis and Ross said they turned down several deals for their cooperation. By the end of the ordeal, they were found guilty of misdemeanor offenses and received 60-day jail sentences.

Following that experience, said Ross, the pair decided to reject the subpoena to testify before a grand jury.

“It was an easy decision for both of us,” Ross said.

Shergalis and Ross are slated to testify on Wednesday, at which time they plan to assert their Fifth Amendment rights and decline to answer any questions from the federal prosecutor.

At that point, a hearing before a judge may be scheduled, to determine whether to hold Shergalis and Ross in civil contempt, which could result in up to 18 months of prison, according to Kelley.

Martínez, who also worked on WikiLeaks founder Julian Assange’s defense team, said the decision by Shergalis and Ross recalled that of Chelsea Manning, who twice refused to testify against Assange before a grand jury, serving time in prison in both instances. 

“It’s like Chelsea Manning, years later,” he said.

Shergalis and Ross decided to go public with their plans after speaking with organizers behind the recently-launched NSPM-7 Defendants Union, a nationwide project for protesters targeted by the Trump administration’s efforts to criminalize dissent as laid out in last year’s National Security Presidential Memorandum-7. The document, part of a broader effort to paint left-wing activism as terrorism, directs the FBI to go after “violent and terroristic activities” associated with “anti-fascism.”

The NSPM-7 Defendants Union is centered around signing a pledge to follow practices such as not cooperating with law enforcement, adopting collective legal strategy when possible, and publicly announcing those strategies — a goal that runs against the secrecy surrounding federal indictments.

While secrecy benefits prosecutors before a grand jury, said Shergalis, “It’s good for all of us to be as transparent as possible.”

“We’re seeing NSPM-7 result in unprecedented levels of prosecution against protesters.”

Shergalis, Ross, and Chambers have each signed the pledge, and the grand jury decision appears to be the first public test case of the union’s ideas.

“We should celebrate people across the country deciding to assert their legal rights boldly against the federal government and its NSPM-7 policy,” said de Janon, of the National Lawyers Guild. “We’re seeing NSPM-7 result in unprecedented levels of prosecution against protesters.”

“This Is Bad Faith”

Meanwhile, Chambers remains imprisoned in Madrid, as the Spanish courts decide whether to grant the U.S. extradition request or not.

Chambers has applied for asylum in Spain and, if his application is granted, he would be released and the U.S. extradition request would be denied. He cannot be extradited until the asylum case runs its course.

A self-described communist and anti-imperialist, Chambers is heir of the Cox family, owners of Atlanta-based telecom giant Cox Enterprises. As part of a settlement in which his family severed ties with him at the time, he sold stock back to them in mid-2023 worth about $250 million.

Since then, he has been funding an estimated 100 humanitarian and left-wing projects in 20 countries, according to his partner, actress and activist Stella Schnabel, including aid projects in the Occupied Gaza Strip.

“I believe this is part of the persecution against pro-Palestine protest.”

As for the Trump administration’s case, Martínez, the Spanish attorney, underscored how the criminal complaint against Chambers raises charges related to the protest against the New Hampshire factory for Elbit Systems, Israel’s largest arms manufacturer, but leaves out how federal prosecution efforts ended up with minor convictions for Shergalis, Ross, and other activists.

“The people who carried out the acts received a minor sentence,” he said. “They leave this out. This is bad faith.”

“Why don’t they tell this to Spain?” he said. “It’s likely that Spain won’t turn someone over based on actions that got 60-day sentences.”

Martínez said Chambers’s opposition to the Israeli genocide in Gaza is the real reason behind the case. “I believe this is part of the persecution against pro-Palestine protest. The U.S. has even sanctioned the International Criminal Court because of this.”

Of Chambers’s case, Martínez said, “This is one more attack.”

The post Fergie Chambers Faces Extradition to U.S. Despite Never Being Indicted, Says Lawyer appeared first on The Intercept.

💾

QuillMark, iterated. How user research helped us evolve an AI-enhanced Drupal style guide assistant

AI and UX Innovation Intern Shlok Gupta and I worked together to build and test Quillmark, an AI-powered Drupal content design tool that tackles the persistent problem of keeping content consistent with the University’s style guide. This post covers how we iterated from version 1 to 2.

Leading a UX Service, it’s critical to stay informed about the latest technologies, as these dictate user expectations and perceptions. I recognised the potential for AI to transform publisher experiences of using Drupal when Drupal AI experts Freely Give came to work with our team in January 2025. Since then, I’ve been committed to experimenting with AI application in content management, both through my involvement with the Drupal AI initiative and by supporting a succession of interns in my UX team at the University.

As a technology, AI is becoming increasingly mainstream. That said, its rapid rate of evolution and flux means adopting it consistently remains a challenge, as does designing AI features that are centred around user needs and expectations. AI features can be built and released in a matter of days, but can just as quickly become superseded and obsolete as technologies and capabilities change, and user expectations and perceptions of AI features can vary widely depending on individual experiences, trust factors and preferences. Continuous research is necessary when developing any user-centred software, but it’s particularly important when designing user-centred AI features, which I wrote about in a related blog post:

Stop chasing, keep researching: Why continuous contextual learning is the only way to build useful AI features

In the spirit of continuous research, the students who occupy the AI and UX Innovation Intern role in my UX team spend as much time testing as they do building. Shlok Gupta joined the team from May – August 2026, in which time he prototyped and tested two versions of an AI-enhanced style guide checker tool in Drupal. Shlok described his process to build and test Quillmark v1 in two blog posts, and also produced a video to show it in action:

Building QuillMark: testing a Drupal style-guide assistant with web publishers

Quillmark: the technical details behind my Drupal style-guide assistant

View a video of Quillmark v1 on MediaHopper

In this post, I continue the story, to explain how version 2 was built based on feedback from version 1, and what we learned testing version 2 with publishers.

QuillMark v1 had a non-AI stage and an AI stage and the ability to flag and fix errors

Shlok designed QuillMark v1 to have two stages as a way of making most economical use of AI time and tokens. Stage 1 used basic pattern-matching and code-based rules to catch straightforward style-guide errors without AI, and stage 2 then brought in AI to find and recommend fixes for deeper issues. This meant AI resource wasn’t spent identifying and resolving simpler problems that didn’t need it. The screenshots indicate how v1 worked.

Screenshot showing Quillmark v1 (in the right-hand panel of a Drupal site) ready to review content

Screenshot showing Quillmark v1 (in the right-hand panel of a Drupal site) ready to review content

From right-left, four screenshots showing detail of the QuillMark guide in the right-hand panel before a scan, the panel expanded to show the guide, results of a stage 1 scan and detail of selected stage 1 findings

From left to right, detail of QuillMark in the right-hand panel – before a scan, expanded to show the guide, results of a stage 1 scan and detail of selected stage 1 findings

Three screenshots of QuillMark, showing the panel ahead of running the stage 2 scan, combined results of the stage 1 and stage 2 scans and detail of selected stage 1 and stage 2 findings alongside each other

From left to right: the panel ahead of running the stage 2 scan, combined results of the stage 1 and stage 2 scans and detail of some stage 1 and stage 2 findings alongside each other

QuillMark screenshot showing how a finding from a stage 2 scan mapped to a sentence in the passive voice highlighted in the editorial interface

QuillMark screenshot showing how a finding from a stage 2 scan mapped to a sentence in the passive voice highlighted in the editorial interface

QuillMark screenshot showing the highlighted sentence changed to active voice - which resulted from pressing the ‘Apply fix’ button on the finding

QuillMark screenshot showing the highlighted sentence changed to active voice – which resulted from pressing the ‘Apply fix’ button on the finding

Tests revealed the need to simplify QuillMark v1

In the tests of QuillMark v1, participants were asked to read a guide about how the tool worked, use it to scan some pre-prepared content and then review the resulting findings and say how they would act upon them. The results indicated several areas for improvement.

All participants understood that QuillMark v1 was a tool to help them correct content errors. Despite being directed to read the guide upfront, however, some participants were unclear of the difference between stages 1 and 2.  Having run stage 1, participants were uncertain what stage 2 of the tool would do. Some identified the AI detail in the stage 2 labels and therefore realised that stage 2, unlike stage 1 used AI, but others thought stage 2 was the ‘repair’ or ‘fix’ stage to follow stage 1 as the diagnostic stage.

As they reviewed the different categories of finding in the right-hand panel, most participants said they felt the amount of information was overwhelming, and difficult to scan read. They especially found it difficult to interpret abstracted recommendations to fix errors, preferring to receive suggested fixes through the ‘Apply fix’ option. As a way to reduce the overwhelm, some participants said they would be inclined to go and fix several of the errors manually first, and then rescan, so that the tool only presented them with the errors they missed themselves.

Other observations from the test participants fell into two categories, lack of understanding of how Quillmark worked, and feedback on how they felt it could work better for them.

Participants were confused about how to use QuillMark and how it worked

Several aspects of participants’ behaviours indicated they weren’t sure how QuillMark worked. These were as follows:

  • There was some confusion over how to start QuillMark running. Participants did not immediately realise that the Stage 1 and Stage 2 buttons would start the tool. They looked for a button that said ‘Run’ or similar. When they worked out how to activate the different stages, they were unclear about what was happening in each.
  • Several participants raised questions about the cost and environmental impact of running the AI stage of the tool, saying this would affect whether they would choose to use it.
  • There was a lack of clarity from participants about whether QuillMark was using generic grammatical rules to flag errors and make recommendations or if it was using the specific University of Edinburgh style guide rules
  • Several participants did not initially recognise that QuillMark could suggest fixes as well as flagging errors.

Participants suggested ways to change QuillMark, to help it support publishing practices better

When they had got used to working with QuillMark, several participants suggested ways they felt it could work better. There were as follows:

  • A request to be able to apply bulk fixes to recurring errors, rather than addressing them one-by-one (for example, removing full stops in repeated headings or switching sets of times from the 24 hour clock to the 12 hour clock)
  • An ask from several participants to be able to preview fixes offered by the ‘Apply fix’ buttons before accepting them to change the text in the editorial interface (however, they soon realised they could switch between the ‘Apply fix’ and ‘Revert fix’ buttons to achieve this).

QuillMark v2 worked in the same way but the interface was simpler

Taking on board the feedback from the QuillMark v1 tests, Shlok made a version 2 which included several changes:

  • A single ‘Scan’ button to start both stages of the tool working, replacing the need for publishers to run stage 1 and stage 2 scans in sequence
  • Progress indicators that appeared once ‘Scan’ had been pressed, to communicate what was happening, and to affirm that the editorial style guide was being checked
  • Inclusion of an ‘Advanced settings’ panel giving users the option to decide whether to include deterministic error scanning and fixing and the use of AI to suggest replacements
  • A panel that estimated monetary cost and environmental impact of each scan resulting in the findings

View a short video demonstration of QuillMark v2 on Media Hopper

The screenshots indicate how v2 worked and show the differences between v1 and v2

QuillMark screenshot showing the tool in the right-hand panel ahead of a scan being run on a page of content titled ‘Research projects’

QuillMark screenshot showing the tool in the right-hand panel ahead of a scan being run on a page of content titled ‘Research projects’

Series of QuillMark screenshots, from left to right, showing the tool with the guide displayed, and the successive stages once ‘Scan’ has been pressed – reviewing, preparing, checking editorial style rules and then the notification that QuillMark has completed the scan.

QuillMark screenshots, from left to right, showing the tool with the guide displayed, and the successive stages once ‘Scan’ has been pressed – reviewing, preparing, checking editorial style rules and then the notification that QuillMark has completed the scan (showing that AI suggestions are included in the ‘Advanced settings’ pane

Tests showed v2 was better, but still had room for improvement

The testing protocol for QuillMark v2 remained the same as for v1, however, this time participants were asked to use the tool on three separate pages of University website content, to give them more practice of engaging with the tool to learn how it worked.

Participants found it easier to understand how QuillMark v2 worked

With the new blue ‘Scan’ button, participants were more easily able to get started with running QuillMark. Since it was running an AI and a non-AI stage QuillMark v2 took longer to produce findings than QuillMark v1, but the newly added progress indicators kept participants informed about what was happening.

The indicator with the data about environmental and monetary costs was noted by all participants, and some said this was welcome information to help them make responsible choices about AI use.

Participants were still directed to the guide, which some wanted to refer back to once they had got started with the tool, to remind them of how it worked.

There were fewer questions about the source of the rules powering Quillmark v2 than for v1, and several participants verified that the tool was using rules from the University editorial style guide by pressing the ‘Link to rule’ button on individual findings (which connected to the relevant page or section of the style guide).

Some still found the interface and display overwhelming

Although QuillMark’s interface had been simplified by the removal of stage 1 and 2 indicators, participants still commented it contained a lot of textual information and was difficult to scan. Some were unclear what the different labels in the findings meant (Errors vs Warnings vs Notes), and several found it easy to miss some of the tool’s functionality simply because there was too much to read through.

Participants were still uncertain about the ‘Apply fix’ button

As they worked through the individual findings, participants were able to recognise the need for corrections that had been highlighted, but some did not appreciate that QuillMark v2 offered a fix as well as flagging the error.

As they used QuillMark v2 to scan a page about research projects, the tool flagged an instance of poorly worded link text (‘Project Website’). The ‘Apply fix’ button contained a suggested improvement (‘Visit the Hillforts Atlas website’) but several participants did not select this, instead they manually addressed the error themselves, by checking the link destination and then writing appropriate link text. Those that did notice that ‘Apply fix’ had made a suggested improvement were happy to accept it and apply it.

Screenshot showing a QuillMark v2 finding flagging poorly written link text

Screenshot showing a QuillMark v2 finding flagging poorly written link text

Screenshot showing QuillMark v2 a fix to improve poorly written link text applied in the editorial interface

Screenshot showing QuillMark v2 a fix to improve poorly written link text applied in the editorial interface

They still wanted repeated findings to be consolidated, to be addressed together

Some categories of findings contained recurring instances of the same issue. Participants wanted these to be grouped or summarised instead of being listed individually, as they wanted to address all the findings on a particular issue together in one action (either dismissing them or applying suggested fixes), rather than going through them one-by-one. This problem was particularly prevalent on pages where the content followed a structural pattern, for example a series of headings all written in non-sentence case (with misuse of capital letters) or a labelling convention applied consistently to rows of a table (for example numerals in sequence).

Screenshot showing individual instances of an error flagged as separate findings in the QuillMark v2 interface

Screenshot showing individual instances of an error flagged as separate findings in the QuillMark v2 interface

There was concern over saving progress when working through lots of findings

In the tests, one of the pages scanned by Quillmark v2 generated 166 findings to be addressed. As participants worked through those in a particular category (for example ‘Links and calls to action’) they felt uncomfortable that they were unable to save as they went, seeking some reassurance that their work was being logged sequentially. They looked for a ‘Save’ button associated with each individual finding, and some wrongly assumed the ‘Dismiss’ button saved the change they had made (whereas in actual fact, this button removed the finding from the list to be addressed).

QuillMark was unable to reconcile multiple errors on the same content

In some instances, a piece of content contained multiple style guide errors, so it appeared in separate findings in separate categories. An example was ‘Prof Smith’s website’ used as a piece of link text. This error appeared in the ‘Spelling, wording and abbreviation’ category, flagged for the incorrect use of ‘Prof.’, but also in the ‘Links and calls to action’ category, flagged for unclear link text.

When participants encountered an error in one finding, they corrected it there, but then when the same piece of content was also flagged for another error in another category, Quillmark v2 had already noted that the content had been changed, and had no way of layering on another, different correction. In these instances, a warning flag disabled the ‘Go to field’ preventing participants from going to the incorrect content, therefore forcing them to try and find the location of the incorrect content themselves, which they found disorientating and tricky, especially in long pages of content.

Screenshot showing the blocker message that displayed when there were multiple errors on a single field of content

Screenshot showing the blocker message that displayed when there were multiple errors on a single field of content

Participants wanted QuillMark to fix heading levels and reposition inline links

Errors relating to content structure, such as incorrect heading hierarchies and inline links were flagged by Quillmark, but the tool was unable to suggest an automatic fix to apply. Several participants said they would have liked for an autocorrect functionality for these errors, since they found them difficult and fiddly to manage within the EdWeb2 editorial interface.

The next iteration of the tool will focus on one category of style rules: Links

Since the last round of tests on QuillMark v2, Shlok completed the internship, and was succeeded by Viktor Sharha in the role of AI and UX Innovation Intern, to continue the work on the Drupal style guide checker tool. Taking all the findings from the tests of QuillMark v1 and v2 together, I concluded that the most pressing problem to address was that of overwhelm.

When a page contains many errors or style guide violations, there is a dual design problem: Firstly how to detail each error, the root cause and the suggested fix, so that publishers understood what was wrong and how it can be corrected, and secondly to do this concisely, taking up the minimal space possible, to avoid publishers having a long scroll through multiple errors with the associated cognitive load.

Going forward, it made sense to focus on the first problem of presentation of individual findings first, and to do so at a site level (recognising that publishers may not do their checking on a page-by-page basis), before scaling this up to design for multiple errors. To maintain a tight remit, and to focus on the style guide violations which are highest priority to fix, we have decided to specifically look at links, to consider how the tool can spot instances of poor link text, how it can describe ways to improve these, and the options for applying automated fixes.

Reflections from the Scottish Web Folk Conference 2026 – ‘Human vs machine: who does it better?’

Scottish Webfolk has become a staple fixture in my October work calendar for the last three years. Despite the very early start to make it north for the conference starting just after nine, by the time you arrive you realise it was worth making the trip. This year there were over 100 attendees from 26 different universities, with a strong line up of presenters from Edinburgh.

Andrew Millar, Head of Digital Engagement & Marketing at University of Dundee started with his key note opening talk, which is always a highlight and this year was no different as he introduced the theme of the conference ‘Human vs machine: who does it better?’

Andrew’s talks are always grounded in realism, especially given the challenging times the higher education sector is facing, but with ample optimism and insightful narrative woven throughout so that by the end you feel energised for a day or learning, sharing ideas and discussing common challenges.

A different take on a familiar theme: AI

It’s probably not a great surprise that the conference had an AI theme. However, I felt this time it was as much about the importance and value of ‘keeping a human in the loop’ as it was about leveraging the benefits of AI-based technologies and tools.

In his talk Andrew referred to the quote: “the threat was never the machine, it’s how people use it” which really stuck with me.

AI is the latest in a whole historical timeline of technological advancements, as Andrew explained. Whilst it is revolutionary, it still needs humans to ensure that it’s used for the greatest benefit. So in that sense the day highlighted to me that machines and humans need to work in tandem, rather than in competition to get the best results.

My third presentation at the conference – ‘AI search summaries: a new lens on old content problems’

For this year’s conference I co-presented with Nick Daniels and Mel Batcharj for what was to be my last UX Service talk. We shared how we trained our web publishing community at Edinburgh on how to make their content AI-ready in the ever-evolving AI search landscape.

We highlighted how evergreen content design principles still stand strong in the new era of AI search and shared how we used the prominence of AI to teach these principles in a slightly reframed way. The aim being to enable publishers to optimise their content for AI search, whilst also tackling persistent problems with our web estate content.

The key takeaway was that website content that is well structured, well maintained and accessible is just as important for AI as it is for users.

You can read more about this training in my previous blog.

June Content Improvement Club: Is your content AI ready? 

Web governance: a problem shared is a problem halved

Another highlight of the day for me was the refreshing session which Stratos Filalithis from Edinburgh and Chris Purdy, Head of Digital Experience from the University of Glasgow hosted, which they called ‘Digital Unscripted’. There were no slides, instead an honest conversation about the challenges both universities are facing to tackle their huge, unwieldy web estates.

I’m used to starting off presentations at conferences explaining that Edinburgh has a huge web estate with over 1,000 web publishers (today was no different). This is often met by surprised faces, especially for those universities with a centralised digital marketing team who oversee the production of all web content. So, it was somewhat comforting to hear that Glasgow faced similar challenges to Edinburgh in terms of managing vast amounts of diverse web content and that both institutions were sharing knowledge and expertise to try to bring order to the chaos.

I found this interesting as a lot of my work recently has been focussed on developing guidance (alongside subject matter experts) for website owners on their key responsibilities when creating and managing a website.

The difficulties and governance risks associated with large web estates felt like a very relevant topic to be discussing given AI’s ability to unearth long forgotten about content in its answers, but also in the wake of the PHP vulnerability incident which highlighted the importance of ‘knowing what you own’ from a web registry perspective.

Scottish Web Folk – much more a community event than a traditional conference

I think the ‘Digital Unscripted’ session, along with the panel discussions where representatives from different universities shared their perspectives on challenges they were facing for me sums up that really Scottish Web Folk is more a community event than a traditional conference. There’s a real sense of sharing solutions to mutual problems and discussing the challenges that nobody has yet managed to resolve, rather than just highlighting successes. I think it’s the community emphasis and collegiality that keeps bringing people back year after year.

Right-Wing Media Watch: London phone theft hits four-year low, yet the media remains silent

Phone theft and robbery offences in London fell to their lowest August level in four years. Yet, if you relied on the right-wing press for your news, you might never know it.

New figures shared by the Metropolitan Police show phone theft and robbery offences fell to their lowest August level since 2022. In the West End, where nearly half of all phone thefts in London take place, offences have fallen sharply, with over 9,000 fewer thefts recorded in the last 12 months.

Commander Andy Featherstone, the Met’s lead for tackling phone theft, noted how phone theft offences are now at a four-year low “because of the Met’s relentless campaign to crack down on these criminals’’.

“This was our biggest operation yet, with officers targeting every stage of the organised criminal chain, including street thieves, handlers and exporters.”

London Mayor Sadiq Khan welcomed the progress, saying the “tide is definitely turning” on mobile phone crime in London with 16,000 fewer mobile phones stolen in the past year and neighbourhood crime falling further too.

“Record funding from City Hall is empowering the Met to go after every single part of the £50million-a-year trade in stolen phones.”

Yet this is precisely the sort of development that has struggled to attract the attention lavished on stories portraying London as a crime-ridden dystopia.

One of the few outlets to give the issue attention was LBC, which published an article by Khan, arguing that progress on phone theft and other crime “has not happened by chance.”

“Backed by massive investment and support from City Hall, the Met has launched the largest anti-phone theft operation in the history of the UK,” he wrote.

Predictably, the article’s comments section became a platform for racist abuse and hostility towards the London Mayor, with some contributors seeming more interested in attacking the mayor than engaging with the figures.

“Loving the comments on this thread, denying the facts and angrily stating their hate,” one commenter observed.

The reaction reflects a wider pattern in the political campaign against Khan, from the hostility directed at his Ultra Low Emission Zone (ULEZ) expansion to the relentless attempts to discredit his record as mayor.

As we have previously explored, Khan has become a convenient whipping boy for the right, with opposition to ULEZ often descending into a campaign of personal attacks. The irony is that the policy was originally conceived under Boris Johnson when he was London mayor.

And this selective approach to London’s record on crime is nothing new.

Figures released earlier this year by City Hall and the Metropolitan Police showed that neighbourhood crime had fallen by around 14 percent over the preceding 12 months, equivalent to roughly 35,000 fewer offences across the capital.

Several outlets, including the BBC, LBC and the Independent, reported the figures prominently. Yet, much of the right-wing press showed considerably less enthusiasm for reporting evidence that challenged its preferred narrative.

The Daily Mail, the Sun and the Daily Express have all found plenty of column inches for stories depicting London as a city in decline. Evidence of falling crime, however, has proved far less enticing.

Consider the Daily Express’s coverage of the previous year’s crime figures, when it declared that Khan had been “humiliated” by supposedly “buried” statistics exposing the “true extent of lawless London.”

Rather than offering a balanced assessment of crime trends, the paper presented the figures as ammunition against the mayor.
When crime figures worsen, the public deserves to know. When they improve, the public deserves to know that, too.

Yet the disparity in coverage suggests that, for much of the press, crime is newsworthy primarily when it reinforces an established political narrative. Stories that portray London as a lawless mess are useful weapons against a Labour mayor; evidence of progress is considerably less convenient.

The post Right-Wing Media Watch: London phone theft hits four-year low, yet the media remains silent appeared first on Left Foot Forward: Leading the UK's progressive debate.

Using a survey to understand digital design tool usage across the University (as part of the Figma design component library project)

This year, as part of the Figma component library project, we researched how colleagues across the University use digital design tools in their work. This post explores how we approached the research, from designing and distributing the survey through to analysing the responses and identifying emerging themes. 

In a previous blog post, intern Kaile Liu introduced the wider Figma project, and its aims and objectives: 

What I am working on as a Digital Developer Intern (Figma) 

Request access to the project brief for more details:

Figma project brief

We needed to understand how digital design work happens across the University 

To begin with, we needed to understand how staff across the University design, collaborate and deliver digital work. 

There are a wide range of tools, workflows and practices currently in use. Understanding these existing ways of working would help us explore where Figma fits within the wider digital landscape, rather than looking at Figma in isolation. It also supports the work we are doing to improve our Figma component design library.

To hear from colleagues across a wide range of roles and disciplines, we chose a survey as the main method for this research.

Five questions framed our research 

As well as understanding what tools people use, we wanted to find out how those tools support their work and where there may be opportunities to improve existing ways of working.  

Our research was underpinned by five key questions: 

  • What tools are people using day-to-day? 
  • How do those tools support their work? 
  • Where do people experience challenges or inefficiencies? 
  • How do teams collaborate when creating digital content and services? 
  • Where are there opportunities to provide better support, guidance and training? 

These questions helped us build a broader picture of digital working practices across the University. Additionally, working this way allowed us to look beyond any individual or singular tool.

Hearing from more than just traditional design roles was important 

Design work happens across many different roles at the University, including roles not traditionally associated with design or that do not have ‘design’ in the job title. For example, a communications officer creating digital content, a developer sketching a wireframe, a UX practitioner co-creating a prototype or a learning technologist building online resources may all be making design decisions as part of their work. 

This meant looking beyond traditional design roles and hearing from colleagues who use digital design tools in different ways.  

Initial conversations helped us shape the research 

Before designing the survey, we carried out an initial set of user interviews with staff from across the University. We also drew on existing University communities and communities of practice to understand the different roles involved in digital design work. These conversations gave us an early view of how colleagues use and collaborate through digital tools. They helped us identify the groups we wanted to hear from and shape the questions we wanted to ask in the survey.

Adapting our survey to broaden our understanding of ways of working

Based on these interviews, we recognised that a single set of questions would not capture the differences between roles particularly well. Instead, we adapted the survey so that respondents would answer shared questions and then be filtered to questions relevant to their role and ways of working.

This, in essence, would give us a more consistent set of responses while still allowing us to explore some of the differences between roles.

Role categories allowed us to tailor the survey 

We created a filter with seven options: 

  • Marketing and Communications 
  • UX and Human-centred Design 
  • Graphic and UI Design 
  • Developer 
  • Project or product manager 
  • Research 
  • Other (for participants who did not feel represented by the other groups) 

Participants selected the options that best reflected their work, determining which role-specific questions they were shown. They also provided their job title.

The survey combined common and role-specific questions 

The survey consisted of three main sections. The questions included a mixture of multiple-choice and open-ended responses. This allowed us to identify broader patterns while also giving colleagues opportunities to explain their experiences in more detail. 

The opening section included five common questions about participants’ roles, the types of digital design work they do and the tools they use, including tools for collaboration, diagramming and presentations. 

The middle section included around four to six role-specific questions, depending on the participant’s selected group. These explored aspects of digital working relevant to each group. For example, marketing and communications colleagues were asked about the tools they use when designing marketing materials, while developers were asked about the tools and approaches they use during the design phase of projects. 

The closing section included 15 common questions focused on colleagues’ experiences and expectations of digital design tools, including Figma. We asked which tools colleagues would be likely to use, whether they experienced challenges with their current tools and how their work might be affected if they lost access to Figma. 

We wanted the survey to reach as many colleagues as possible

We distributed the survey primarily through existing Teams channels and University communities, which helped us reach a wide range of roles. These included groups focused on marketing and communications, human-centred design and digital development, as well as distribution via heads of IT. 

The survey received 55 responses  

We heard from 55 staff across a range of roles. Based on the categories participants selected when completing the survey, these were as follows: 

  • Marketing and Communications: 20 
  • Developers: 10 
  • UX and Human-Centred Design: 6 
  • Graphic and UI Design: 3 
  • Project or product manager: 2 
  • Other: 14 

Although seven categories were available in the survey, no participants selected ‘Research’ as their primary category, so it is not shown in the breakdown. 

The ‘Other’ category included colleagues working in areas such as product and project management, learning technology and academic support. 

We refined the groups when analysing the responses 

The survey categories gave us a useful starting point, but participants did not always recognise themselves within the roles specified (even when their job title directly reflected one of the options). For example, a participant selected themselves as ‘Other’, but their job title indicated that their work was within graphic design.

In order to evaluate the responses effectively, we revisited participants’ selected categories alongside their job titles and descriptions of their work.

This helped us six create groups that gave us a more useful basis for comparing responses:

  • Developers and technical specialists 
  • UX practitioners 
  • UI and graphic designers 
  • Marketing and communications staff 
  • Product and project managers 
  • Learning technology and academic support staff 

Some of these groups needed to be created on the back of this, as we had not identified those specific roles. For example, Learning Technologist was not an option for participants to select, but emerged as a useful category based on the number of respondents who had this as their job title. 

After this assessment, we were in a better place to begin analysis, as these groups gave us a more useful basis for comparing responses while still reflecting the range of roles represented.

Analysing the survey results required two approaches 

The survey produced both quantitative and qualitative responses, and we used different approaches depending on the type of question and response. 

For the role-specific questions, we used FigJam (Figma’s whiteboard for online collaboration) to review and compare responses across the different groups. This included both quantitative and qualitative responses, allowing us to look at the detail within each role as well as compare responses across the wider dataset. We used Power BI, a data visualisation platform, to explore the common quantitative questions, which gave us a consistent set of responses across all participants. 

We used FigJam to explore the role-specific responses 

We created a large collaborative FigJam board to organise the responses. FigJam supported discussion within the project team, allowing us to work in tandem and analyse the data as a group (in person and asynchronously).

We read through responses from each group, compared them across different roles, and identified recurring patterns and themes. FigJam also allowed us to consider the quantitative responses alongside the more detailed qualitative answers, giving us a fuller picture of ways of working. 

Screenshot of three frames on FigJam full of stickies. There is a blue section, titled Developers, an orange section titled Marketing and Communications, and a green section titled Graphic visual and UI design.

Section of our analysis on the FigJam board

Power BI helped us explore the common quantitative responses 

Power BI allowed us to visualise responses across the opening and closing questions. We wanted to do this as they were common questions asked of all participants. Power BI allowed us to bring our data to life by presenting the data in a more visual way, highlighting the common patterns and themes more easily.

Screenshot of Power BI visualisations. There are seven individual bar graphs of different colours, alongside a larger bar graph with these seven combined. The large bar graph has a right skewed narrow tail. There are also two sets of pie charts, each consistening of seven smaller charts and one larger combined. The data itself is not visible.

Section of our Power BI visualisations for the project.

Grouping responses helped us identify recurring themes 

The open-ended questions in the role specific sections had more detailed responses. This required us to compare responses across the different role groups and group similar comments together to identify recurring themes. 

As we worked through the responses, we also noted areas where a follow-up conversation with a participant could provide more context.

We also captured key quotations that illustrated what participants were telling us in their own words. These will be useful for when we playback findings to colleagues and complete a written report. 

The research will inform the next stage of the project 

The research highlighted both the diversity of digital working practices across the University and common themes across different roles. 

The next stage will bring these findings together into a report. It will highlight where Figma currently supports existing workflows and where its integration will provide more consistent, unified delivery of digital practices across the University.

❌