We’re super excited to bring you a new release of WP Offload Media.
Version 3.4.0 delivers full support for WordPress 7.1, performance improvements and bug fixes, along with foundational changes that unlock future features and further performance improvements.
WordPress 7.1 Compatible
WordPress 7.1’s client side media handling brings along three new fields to the _wp_attachment_metadata records in the postmeta table related to Media Library items.
Namely:
source_image: The uploaded image file that needed to be converted to another format, e.g. an HEIC file.
animated_video: The MP4 file created from an uploaded animated GIF.
animated_video_poster: A JPG extracted from an uploaded animated GIF to act as a placeholder for the MP4 version.
WP Offload Media now knows about these extra files, and will offload and remove them from the server as appropriate.
To accomplish this, we had to tap in to some in-progress changes to the plugin.
Preparing for the Future
We’ve been working on some changes to the internals of WP Offload Media to prepare for some features our customers have been asking for, while also improving performance, especially for sites with very large Media Libraries.
Custom Table Changes
When you upgrade to WP Offload Media 3.4.0, depending on how many offloaded items you have, you may see an upgrade notice in the settings page.
This upgrade routine will quietly background upgrade WP Offload Media’s metadata related to offloaded items to create a new as3cf_files table that lives alongside the existing as3cf_items table.
Although you won’t be able to make any changes to WP Offload Media’s settings or run any of its bulk management tools while this upgrade is in progress, all existing and new offloads will continue to work as usual.
This new as3cf_files table holds a wealth of information:
1-to-1 mappings of local media files to their path in the cloud storage bucket.
Information related to whether the files are private in the bucket or not.
A reference to the as3cf_items record which ties multiple files to a Media Library item or BuddyBoss avatar or cover item.
Performance Improvements
The as3cf_files table gives WP Offload Media much improved flexibility in how it keeps track of offloaded media, crucial for supporting the new Media Library metadata fields mentioned above.
However, the new table’s data structure also makes it far simpler and therefore faster for finding matching records when performing unique name checks, or rewriting URLs between their local and remote versions.
WP Offload Media no longer needs to reduce file names down to their base non-sized suffixed name and do potentially expensive LIKE table scans, it can do much simpler equality checks that use indexes for speed.
Because of these changes, it has been possible for us to reduce the processing required when doing URL rewrites. We’ve removed a whole pass through post content and its associated processing, and removed other loops that are no longer required.
We’ve also been able to vastly improve the way we cache the relationship between the URLs in a post’s content with their associated Media Library items. As such, you may see a second upgrade routine notice related to the removal of ye olde amazonS3_cache records from the postmeta table, which will be replaced by much better behaved as3cf_url_cache_local and as3cf_url_cache_remote records.
And for our most advanced customers that have their whole site behind a CDN such as CloudFront, and only use WP Offload Media to manage media in the bucket, we have a big performance boost for you. WP Offload Media no longer implements many of the usual frontend content filters if “Deliver Offloaded Media” is turned off, cutting out a lot of unnecessary checks and processing.
Small Steps
Along with the custom table changes that unlock future features and performance improvements, WP Offload Media will need to change how some of its internal code is organized.
We’re very lucky to have a number of plugins that integrate with WP Offload Media, and are aware of many customers that have custom code that relies on the existing internal API.
As such, we’ve been very careful to make these changes in a backwards compatible way, keeping the existing as3cf_items table data in sync with the data managed in the new as3cf_files table, and ensuring the classes and methods that work with the old data still work.
However, we have marked some functions as deprecated, and do intend to eventually remove them.
Our work in this area is not complete. WP Offload Media still uses some of the deprecated methods itself, and we have plans for further improvements to the data handling that unlock some exciting features, and continue to improve performance.
And More
As always, there’s a number of other bug fixes and improvements in this release.
For a full list of new features, improvements, and bug fixes, see the 3.4 Changelog.
Next Up
We hope you enjoy this foundational release of WP Offload Media.
We’re already working hard on the next release, and are excited to bring you the features and improvements you’ve been asking for.
Enterprise WordPress security is often discussed in technical terms.
Keep software up to date. Strengthen authentication. Monitor vulnerabilities. Choose secure infrastructure. Follow security best practices.
They’re all sensible recommendations.
The difficulty is that very few enterprise platforms become more or less secure because of a single technical decision. They change gradually as the organisation around them changes.
A new supplier joins a project. Marketing adopts another platform. A regional office needs its own publishing workflow. A business acquisition introduces another website. An AI tool is connected to editorial processes. Someone needs temporary access to production for a launch weekend.
None of these decisions appear particularly significant. They’re simply part of running a large organisation.
Taken together, they shape the security of the platform far more than many people realise.
In practice, enterprise WordPress security is heavily influenced by how organisations make decisions over time.
Enterprise WordPress security involves every team
One of the defining characteristics of enterprise organisations is that nobody sees the whole picture.
Editorial teams see publishing workflows. Developers see code and infrastructure. Marketing sees campaigns and customer journeys. Procurement sees contracts. Security teams see policies and risk. Regional teams see the systems they rely on every day.
Each perspective is valid. Each team is solving genuine business problems.
The challenge is that every decision made within those individual contexts also affects the wider platform.
A new integration might improve a marketing workflow while introducing another dependency that engineering needs to maintain. An AI service might reduce editorial effort while creating a new relationship with organisational data. A supplier might solve an immediate delivery challenge while increasing the number of people with access to production systems.
None of those outcomes necessarily make the platform less secure. They do illustrate why enterprise WordPress security extends well beyond the CMS itself. The platform becomes the point where hundreds of independent decisions intersect.
Enterprise WordPress platforms remember decisions long after projects end
Enterprise platforms have long memories.
Projects finish. Teams change. Agencies move on. Priorities shift. The platform remains.
Several years after launch, it’s common to find systems that nobody uses anymore, integrations whose original owners have left the organisation, or workflows that continue simply because they’ve never been revisited.
Sometimes those decisions still make sense. Sometimes the business has changed so much that nobody remembers why they were made in the first place.
This isn’t unusual. It’s how successful enterprise platforms evolve.
The organisations that manage this complexity well don’t rely on institutional memory. They create processes that make it easier to understand why decisions were made, who owns them today, and when they should be reviewed.
That’s an operational discipline as much as a security one, and it’s an important part of maintaining enterprise WordPress security over the lifetime of a platform.
AI is reshaping enterprise WordPress security
AI is becoming an increasingly important part of enterprise WordPress security discussions.
Teams that might previously have evaluated one or two new technologies each year are now assessing new AI capabilities every month. Editorial teams want content assistants. Developers are experimenting with coding agents. Marketing wants personalisation. Customer service teams are exploring conversational interfaces.
Each opportunity brings another decision.
Which provider should we use? What content should it access? Which teams can use it? How will it integrate with existing systems? Who remains accountable for the output? What happens if the organisation wants to adopt a different model next year?
These questions rarely have purely technical answers.
They require organisations to make consistent decisions across technology, operations, legal, procurement, marketing, and security. The faster AI evolves, the more valuable that consistency becomes.
What does enterprise WordPress security actually involve?
When people think about enterprise WordPress security, they often picture software updates, infrastructure, or vulnerability management.
Those are all essential, but they’re only part of the picture.
A mature approach to enterprise WordPress security also includes:
Governance and decision-making
Identity and access management
Integration and supplier management
Operational processes
AI governance
Change management
Clear ownership and accountability
Together, these practices help organisations maintain confidence as platforms evolve, technologies change, and digital estates become more complex.
Viewed that way, it’s easy to see governance as something that slows organisations down.
Enterprise organisations experience it differently.
Good governance reduces uncertainty. Teams understand how new technologies are evaluated. Suppliers know what’s expected of them. Decisions follow consistent principles rather than depending on who happens to be involved in a particular project. Similar problems are solved in similar ways, even when different teams are responsible for delivery.
That consistency becomes increasingly valuable as organisations grow because the volume of decisions continues to increase while the number of people making them grows alongside it.
Strong enterprise WordPress security depends on organisations making consistent decisions over many years.
Ultimately, enterprise WordPress security reflects how an organisation operates
Every enterprise platform tells a story about the organisation behind it.
Some platforms reveal years of carefully considered evolution, where new technologies have been introduced deliberately and operational practices have matured alongside the business.
Others reveal the opposite. Different teams have solved similar problems in different ways. Ownership has become unclear. Temporary decisions have quietly become permanent. Complexity has accumulated faster than understanding.
The technology may look similar in both cases.
The difference lies in how decisions have been made.
This is why enterprise WordPress security shouldn’t be viewed solely as a technical capability. It reflects how an organisation introduces change, manages complexity, and creates confidence that today’s decisions will still make sense several years from now.
Enterprise platform discussions often begin with software costs.
Licence fees, subscription models, implementation budgets, and support agreements are relatively easy to compare during procurement. They are visible, measurable, and usually well documented by vendors.
The challenge is that software costs represent only one part of a platform’s economic impact. Once a platform is embedded across teams, workflows, and business processes, a much broader set of costs begins to influence its value.
Integrations need maintaining. Governance models need evolving. New channels emerge. Teams expand into new regions. Business priorities shift. Technologies that were not part of the original requirements become important.
Over time, these factors often have a greater influence on platform economics than the original software agreement.
This is why enterprise organisations increasingly evaluate platforms through the lens of total cost of ownership (TCO).
The largest platform costs often emerge after launch
Many digital platforms begin with a relatively clear set of requirements. A website needs to be rebuilt. A content platform needs modernising. Multiple properties need consolidating onto a shared foundation.
Those projects have a defined scope and budget.
The complexity arrives later.
As organisations grow, digital platforms become connected to a wider ecosystem of services. Content management systems frequently sit alongside customer data platforms, analytics tools, ecommerce services, identity providers, DAM systems, marketing automation platforms, translation workflows, and increasingly, AI-powered tools.
Each integration creates value. Each integration also introduces dependencies that require maintenance, governance, and operational oversight.
At enterprise scale, platform ownership becomes less about running a CMS and more about managing an evolving digital ecosystem.
Understanding how a platform supports that evolution is central to understanding its long-term cost profile, and thus the total cost of ownership.
Why platform flexibility has financial value
Enterprise requirements rarely remain static for long.
A business may acquire a new brand, expand into a new market, launch a new product line, or introduce entirely new customer experiences. Regulatory requirements change. Internal operating models evolve. New technologies create opportunities that were not anticipated when the platform was first selected.
Every one of these developments places demands on the underlying platform.
Some platforms accommodate change relatively easily. Others require significant redevelopment, specialist expertise, or commercial agreements before new capabilities can be introduced.
The difference has a direct financial impact.
When introducing a new integration takes months rather than weeks, costs increase. When teams are forced to work around platform limitations, productivity declines. When architectural decisions made years earlier restrict future options, innovation becomes slower and more expensive.
This is one reason enterprise leaders increasingly assess a platform’s adaptability alongside its feature set.
Understanding the economics of proprietary platforms
Proprietary platforms provide a clear commercial model. Organisations pay for access to software that is owned, developed, and governed by a vendor.
For many businesses, this structure offers reassurance. Product roadmaps, support models, and accountability are clearly defined.
As digital estates grow, however, the relationship between platform usage and platform costs often becomes more complex.
Licensing models frequently scale alongside adoption. Additional users, environments, websites, markets, or capabilities may introduce additional costs. Access to advanced functionality may require higher pricing tiers. Integrations and customisations can become dependent on vendor-approved approaches or specialist expertise.
None of this is unusual. It reflects the incentives built into commercial software businesses.
The important consideration for enterprise buyers is how those costs behave over time. Growth, complexity, and change are constant features of large organisations. Understanding how a platform responds to those forces is often more valuable than comparing feature lists during procurement.
Where open source creates a different economic model
Open source platforms approach the same challenge from a different direction.
Rather than charging for access to the software itself, open source shifts investment towards implementation, operations, and capability development. Organisations retain ownership of their code, data, infrastructure decisions, and platform architecture.
This changes how investment is allocated.
Budget that might otherwise be committed to recurring licensing costs can be directed towards improving editorial workflows, strengthening integrations, enhancing customer experiences, modernising infrastructure, or introducing new capabilities. The organisation has greater discretion over where resources are invested and how priorities are balanced.
Control also extends beyond budgeting.
Teams can choose hosting providers, adopt new technologies, work with different implementation partners, and evolve their architecture as requirements change. Decisions are shaped by business priorities rather than vendor roadmaps or commercial constraints.
For enterprise organisations operating in environments where change is constant, that flexibility has practical and measurable value.
Vendor lock-in is an operational and financial consideration
Vendor lock-in is often discussed as a technical issue, but its effects extend much further.
Organisations that become heavily dependent on a single vendor ecosystem can find future decisions increasingly constrained. Replacing services becomes more difficult. Negotiating commercial agreements becomes more challenging. Migrating data or introducing alternative technologies requires greater investment.
These constraints affect both risk and the total cost of ownership.
By contrast, platforms built on open standards and open technologies provide more options when business requirements change. That does not eliminate complexity, but it does reduce dependency on a single supplier or ecosystem.
For many enterprise leaders, preserving optionality has become a strategic objective in its own right.
The cost that rarely appears in TCO models
One area that receives relatively little attention in platform evaluations is the cost of delayed innovation.
Organisations compete through their ability to adapt. New products, services, workflows, and customer experiences all depend on how quickly teams can turn ideas into reality.
When platform constraints slow experimentation, the impact is rarely captured in procurement spreadsheets. Lost opportunities do not appear as line items. Delayed launches rarely show up in platform budgets.
Their effect is still significant.
Teams that can test new ideas quickly tend to learn faster. Organisations that can integrate emerging technologies more easily tend to adapt more effectively. Platforms that support continuous evolution create fewer barriers between strategy and execution.
These advantages accumulate over time.
A broader view of return on investment
Enterprise platform decisions influence far more than technology stacks.
They affect how teams collaborate, how quickly organisations can respond to change, how easily new capabilities can be introduced, and how much control businesses retain over their digital future.
Viewed through that lens, total cost of ownership becomes a measure of resilience and adaptability as much as financial efficiency.
The most valuable platforms are rarely those that simply minimise costs. They are the platforms that allow organisations to evolve without repeatedly rebuilding, replatforming, or renegotiating the foundations of their digital estate.
Download The Enterprise WordPress Playbook to explore platform strategy, governance, composable architecture, AI adoption, and the factors that shape long-term enterprise platform success.
Download The Enterprise WordPress Playbook to explore platform strategy, governance, composable architecture, AI adoption, and the factors that shape long-term enterprise platform success.
What does it actually look like to work with AI every day as an engineer?
In this piece, Human Made Senior Engineer Ivan Kristianto shares a practical, battle-tested workflow for building with AI agents. From spec-first thinking and parallel execution to disposable code and “vibe user” testing, this is a candid look at what works, what breaks, and how to stay effective as the tooling evolves almost daily.
I use AI agents every day: not just to write code, but for research, brainstorming, planning, and user testing. This post is not a tool recommendation. It is a set of patterns I have found effective: staying tool-agnostic, working spec-first, building skills, isolating work in worktrees, spawning agents in parallel, and using AI away from the keyboard. The goal is to show what a real AI-augmented workflow looks like, trade-offs and constraints intact.
The Non-Deterministic Reality
The first thing to accept about AI is that it is non-deterministic. Run the same prompt twice and you get two different results. This is not a bug to work around. It is the nature of the medium, and once you accept it, everything else about how to use these tools becomes clearer.
Because output varies, I do not commit to one tool or one model. I move freely between Claude Code, Gemini CLI, Copilot CLI, Codex CLI, Codex App, OpenCode, and Anti Gravity, picking whatever fits the task or the moment. The landscape changes fast; most mornings there is a new model or a new release to try. Locking yourself to a single tool means constantly leaving capability on the table.
Spec-First, Then Build
Before writing any code, I spend time on the spec. This single practice separates productive AI usage from frustrating AI usage.
My framework is obra/superpowers, which implements a seven-stage development process: brainstorming, worktree setup, plan writing, subagent-driven development, test-driven development, code review, and finishing. I do not follow every stage mechanically, but the core sequence, brainstorm, spec, plan, build, review, is the backbone of how I work.
Step 1: Create the Worktree
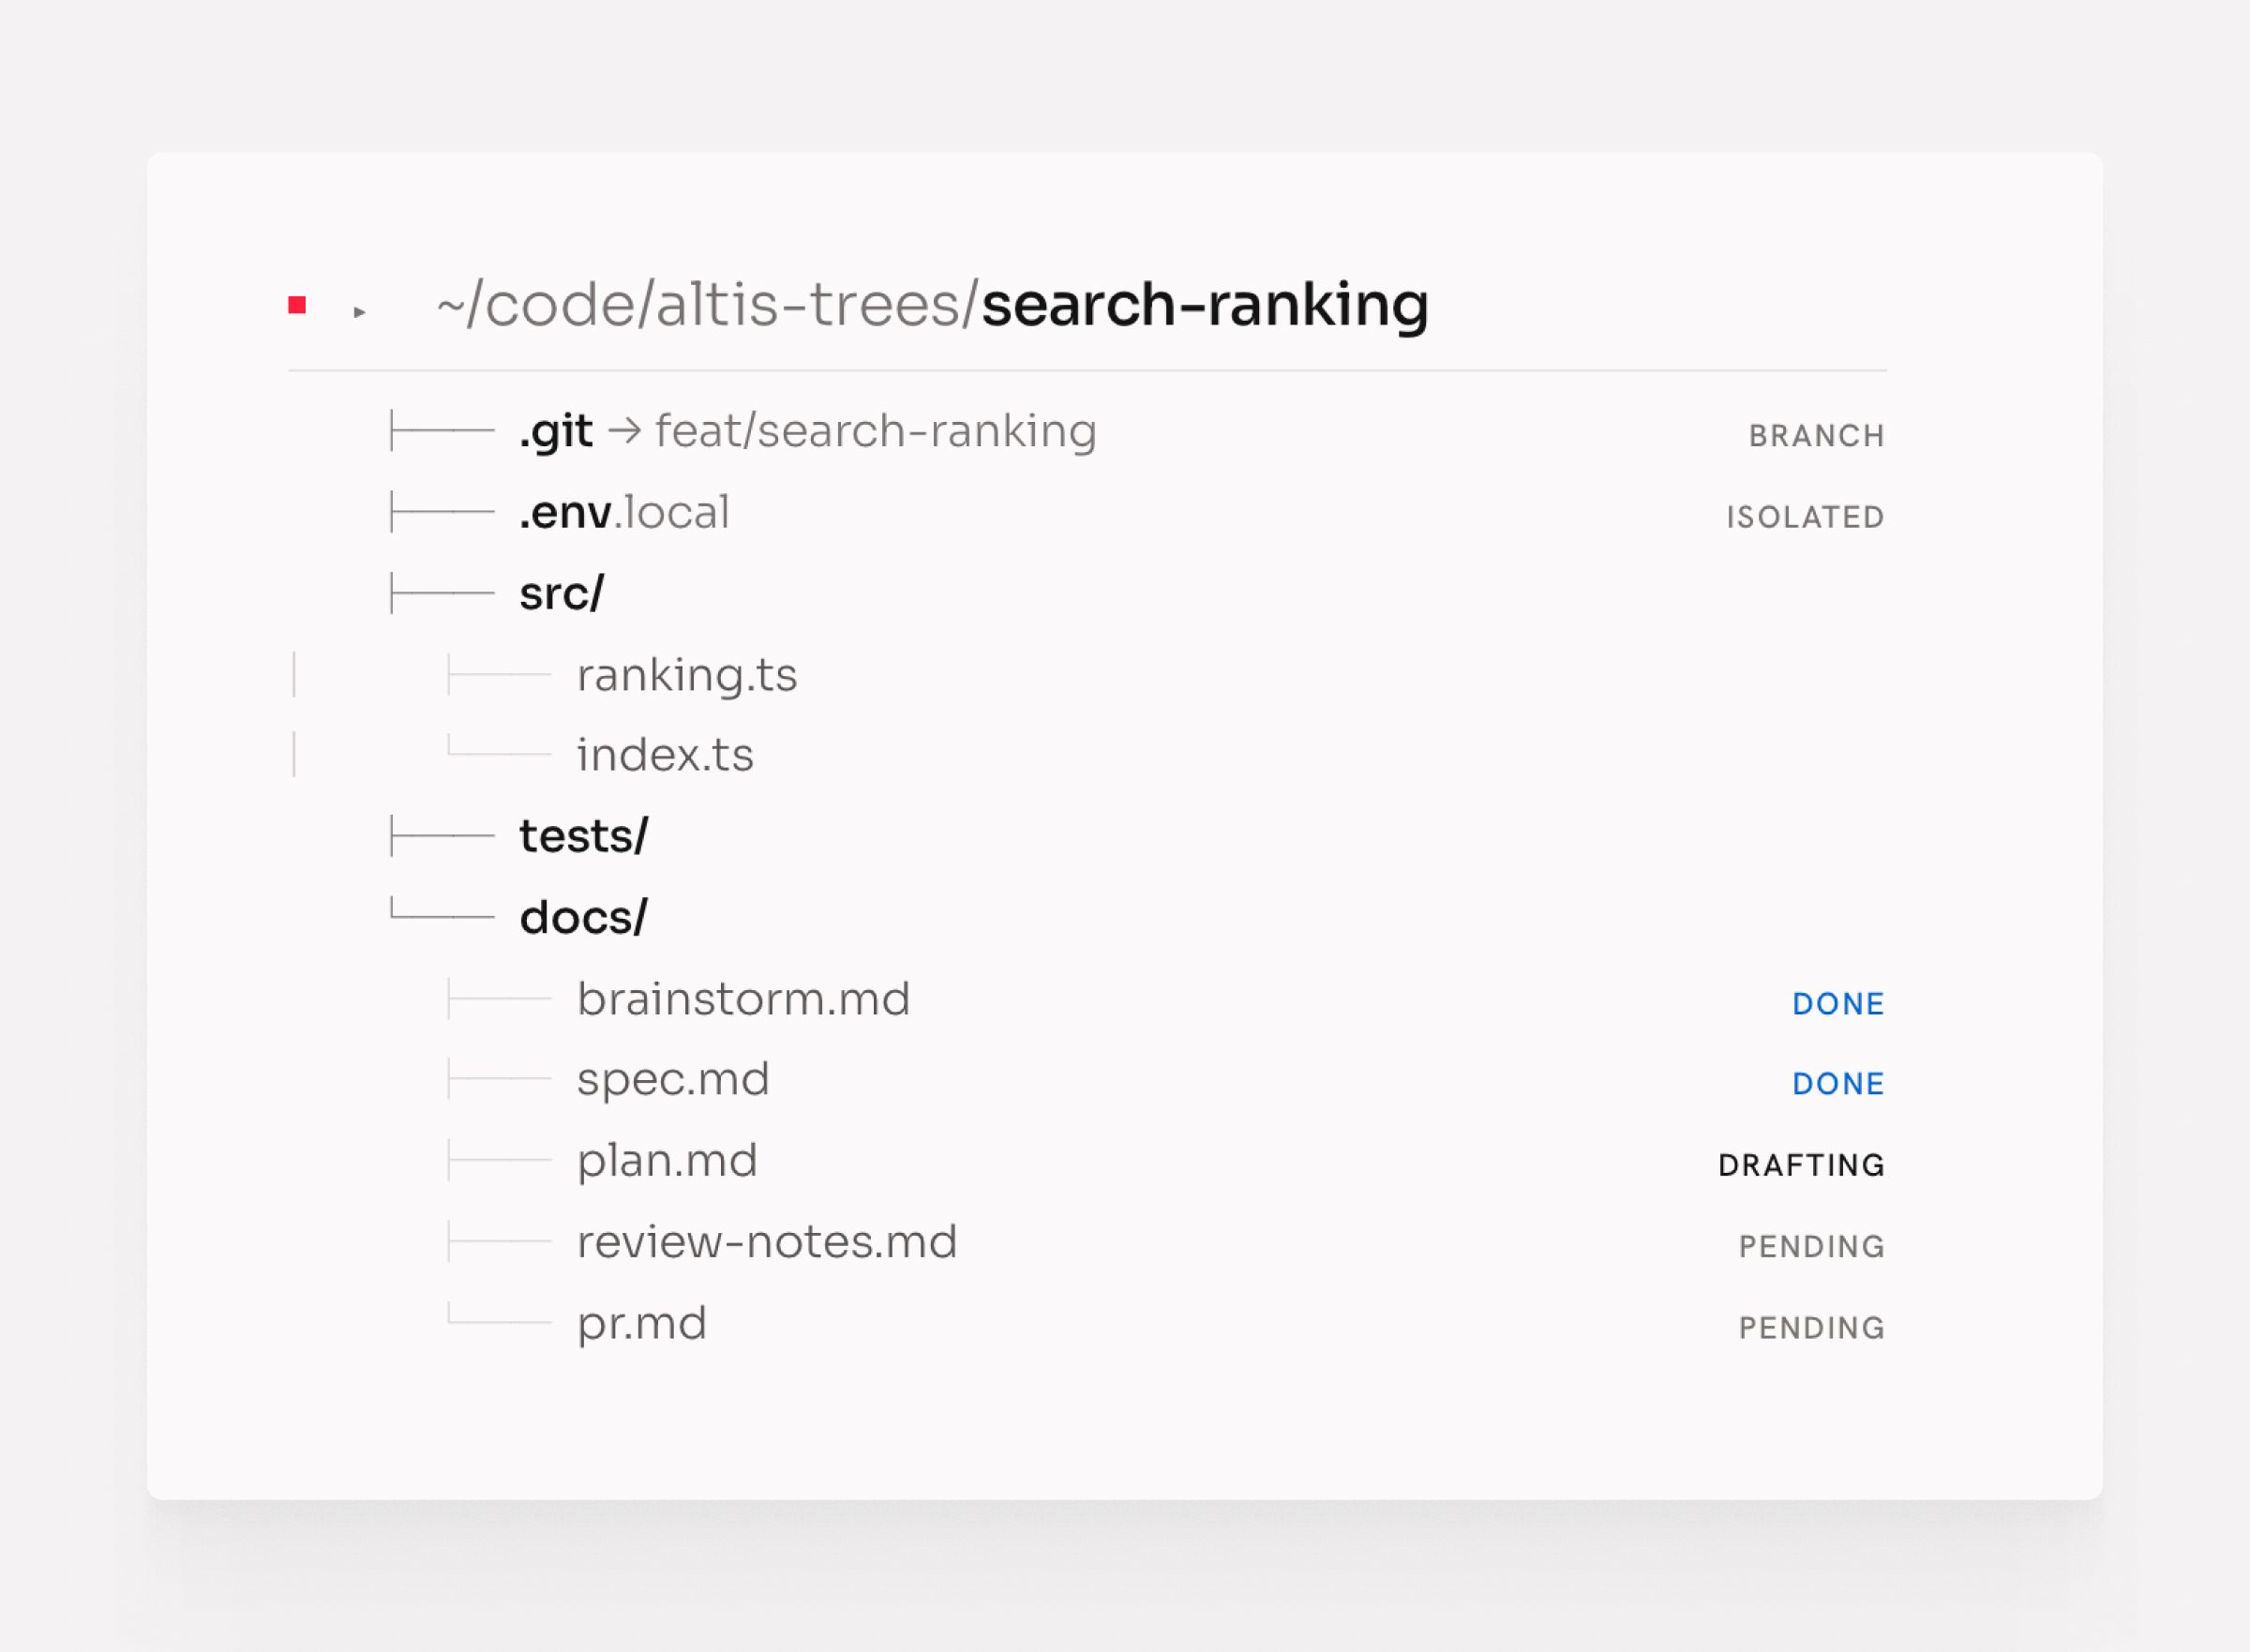
Every piece of work starts with its own Git worktree. A personal skill creates worktrees in an opinionated, consistent way: the right branch name, the right directory structure, the right environment. One command, and the workspace is ready.
This matters because everything that follows happens in isolation. The worktree is the container for the entire feature, from first brainstorm to merged PR.
Step 2: Brainstorm With the Agent
With the worktree ready, I open a brainstorming session using the superpowers brainstorming skill. The agent interviews me, asks questions to understand the problem, explores different approaches, and sometimes visualizes options: diagrams, flow descriptions, comparisons. It does not start designing until it understands what I actually want.
This step is slower than typing “build X.” It is also why the output is worth building.
Step 3: Write and Review the Spec
Once the agent has enough context, it writes the design spec. I read it carefully and improve it where my thinking has evolved. Then I bring in a second agent: I share my vision for the feature and ask whether the spec aligns with that vision. A fresh agent without prior context finds gaps I glossed over.
The spec is the source of truth for everything that follows. Getting it right here prevents rewrites later.
Step 4: Build the Implementation Plan
With a solid spec, I ask the agent to write an implementation plan. Superpowers breaks this into small tasks: each two to five minutes of work, with exact file paths, complete code intent, and verification steps.
I read the plan thoroughly. When I find gaps or steps that do not match my intent, I tell the agent to change them. A vague step in the plan produces vague code. I fix the plan until every step is something I would hand to a junior developer with no further explanation.
Step 5: Cross-Review Spec Against Plan
Before building starts, I spawn a fresh agent and ask it to review the spec and the implementation plan side by side. Does the plan deliver what the spec describes? Does every acceptance criterion in the ticket have a corresponding step in the plan?
This agent reports gaps. I fix them. Then building can start.
Step 6: Execute the Plan
When the plan is solid, I run the executing-plans skill. This dispatches subagents that execute each task sequentially, running checks between steps and stopping if something goes wrong.
I use a detailed prompt for this step to give the agent the right context and constraints:
/superpowers:executing-plans
docs/plans/path-to-implementation-plan.md

Follow the plan strictly and complete tasks sequentially and do not stop until finish.

Execution Rules

1. Implement tasks one by one in the order defined in the plan.
2. Create a separate commit for each completed task.

Code Review Phase
3. When all tasks are completed:
- run the requesting-code-review skill
- review the code changes against the implementation plan
- fix any valid feedback or implementation gaps.

Finalization
4. Run all tests and quality gates again.
5. If everything passes:
- commit final changes
- push the branch

Output
6. Provide a concise summary including:
- tasks completed
- commits created
- issues fixed during reviews
- manual test results
- test and quality gate results
- link to the created PR.
I start it and leave. The agents work through the plan without me.
Step 7: Review as a User
When execution finishes, I review the result as a user, not as an engineer. I do not read the code at this stage. I use the feature. I look for whether it does what I asked, not whether the implementation is elegant.
If the result is significantly wrong or too much is missing, I reset. I discard the code and return to the plan: refine it, try a different model, or rethink the spec. Starting over is faster than patching something fundamentally off.
If the result is mostly right with some gaps, I continue.
Step 8: Code Review by Three Agents
For the code review, I spawn three subagents in parallel, each focused on a different angle:
Maintainability: is the code readable, consistent, and easy to change?
Performance: are there obvious bottlenecks or inefficiencies?
Security: are there vulnerabilities, unsafe inputs, or exposed data?
Each agent reviews independently. When the results come back, I triage them: critical issues get fixed immediately, lower-priority findings get addressed or noted. Then I ask the agent to implement the fixes.
This cycle repeats until the code meets the bar.
Step 9: Ship to PR and Test
When the code passes review, I open a pull request and do a final manual review of the diff. Then I create a test plan as a user: a checklist of scenarios a real user would walk through.
I give that test plan to an agent with browser access and ask it to execute each step using the Chrome integration. The agent runs through the plan, reports what passes and what fails, and I address the failures.
This cycle, fix, retest, fix again, continues until the feature works end to end as a user would experience it.
When it does, I merge.
Code Is Cheap: The Throw-Away Mindset
I treat generated code as disposable by default.
The agent builds. I review. If the result falls short, I throw it away and start again: with a different model, a different prompt, or a refined implementation plan. This sounds wasteful. In practice it saves more time than it costs. Iterating on code going in the wrong direction is expensive. A clean start with a better spec is cheap.
Code is cheap now. The expensive part is reading, deciding, and knowing when to stop.
This mindset only works if you are honest during review. The temptation is to keep patching something that is mostly right. Resist it. If you would not write it yourself, and the agent cannot fix it cleanly in one more pass, throw it away.
Quality Gates: Built-In Self-Correction
The single biggest improvement to agent output quality is not a better prompt or a smarter model. It is a strict set of quality gates that run before every commit.
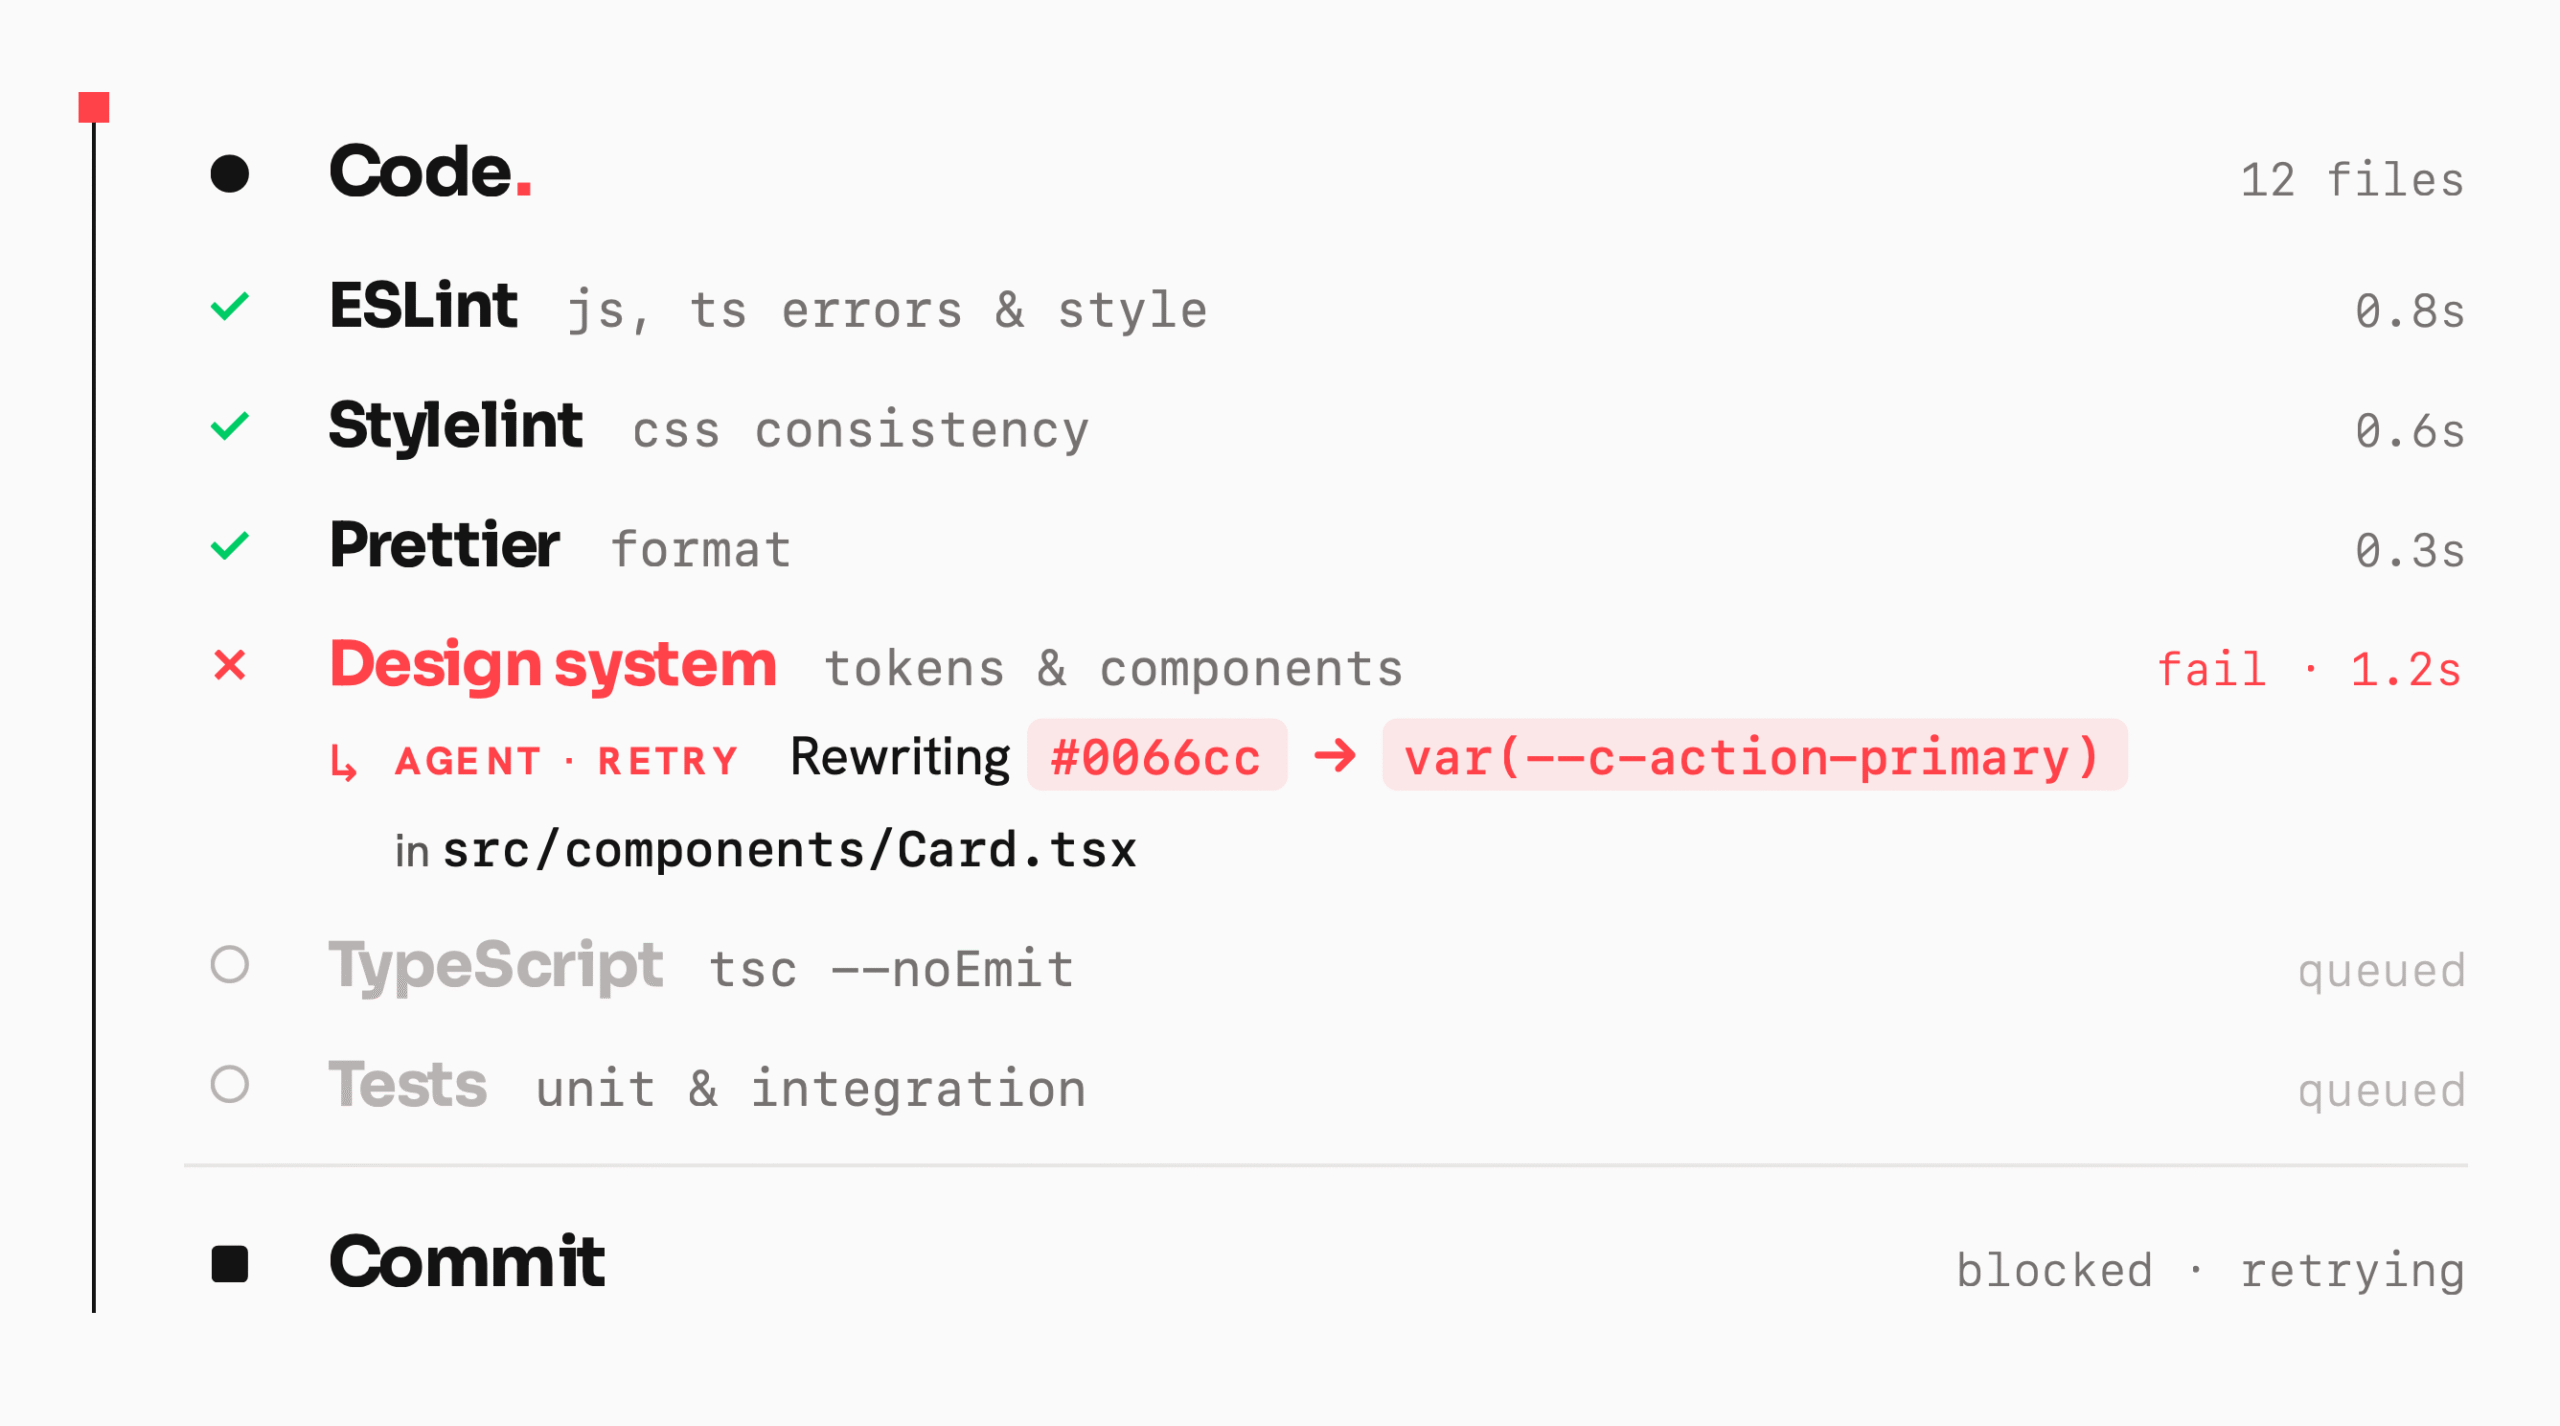
Agents still hallucinate (a lot). They produce code that looks right but breaks something subtle. Quality gates change that: the agent catches its own mistakes without you having to notice them. The gates fail, the agent reads the error, fixes it, and tries again. By the time you see the output, it has already corrected itself.
The Gates I Run
I enforce six checks on every project:
ESLint catches JavaScript and TypeScript errors, enforces code style rules, and flags patterns that cause bugs. The agent cannot commit code that fails this.
Stylelint enforces CSS and SCSS consistency. Without this, agents drift into inconsistent naming, specificity problems, and unmaintainable styles.
Prettier formats all code uniformly. It removes every formatting argument and keeps diffs clean.
Design system compliance is a custom check that verifies the agent is using the correct design tokens, components, and patterns rather than inventing its own. This gate most often catches an agent going off-script.
TypeScript typecheck runs tsc --noEmit to catch type errors that ESLint misses. Agents frequently produce type-unsafe code that passes linting but breaks at runtime.
Unit and integration tests run on every commit. If the agent breaks something that was working, the tests catch it immediately rather than at review time.
Why This Works
Each gate provides fast feedback. The agent does not wait for a human review to learn it got something wrong; it gets an immediate, machine-readable description of exactly what needs to change. It reads the error, fixes it, and commits.
This loop, write, check, fix, commit, runs automatically inside the executing-plans skill on every task. By the time the skill finishes, the code has passed all six gates on every commit in the plan.
The code quality you get back is substantially higher than what agents produce without gates, not because the agent got smarter, but because it corrected itself dozens of times before you saw the result.
Skills: Build Once, Reuse
A skill is a reusable prompt or workflow: a precise set of instructions for doing a specific thing well, invocable with a single command. Skills eliminate the overhead of re-explaining context every time.
Finding Skills
Before building a skill, I search for one that already exists. I use skills.sh, a tool that searches available skill libraries and surfaces what fits the task. Most of the time, someone has already built what I need.
When I find a candidate, I read it carefully before downloading. A skill that looks useful can encode assumptions that conflict with how I work, or instructions I would not want an agent following automatically. Reading it first costs a minute; discovering the problem mid-task costs far more.
If the skill works, it earns a permanent place in my toolkit. If it does not, I delete it and move on. No friction, no sunk-cost trap.
Building Custom Skills
For tasks I repeat often and cannot find a skill for, I build one. The process is straightforward: describe what I want to achieve, have the AI draft it, read it carefully, refine it, and test it. Once built, I run it, step away, and come back to the result.
The fire-and-forget pattern works because the skill captures the reasoning once. I do not re-explain the standard every time; I invoke it.
I build new skills whenever I find myself writing the same instructions more than twice. That threshold is the signal.
Skills I Use
These are the skills currently in my toolkit across ~/.claude/skills and ~/.agents/skills:
Skill
What it does
worktree-environment-setup
Creates a Git worktree in an opinionated, consistent way: branch name, directory structure, environment
multi-reviewer-code-review
Spawns three subagents in parallel to review code for maintainability, performance, and security
generate-test-plan
Produces a user-facing test plan from git changes
execute-test-plan
Runs a test plan using Chrome browser automation, step by step
Turns a rough idea or bug description into a well-formed GitHub issue
agent-browser
Browser automation for agents: navigating pages, filling forms, extracting data
writing-clearly-and-concisely
Applies Strunk’s rules to any prose I write or edit
reflect
After a session, extracts learnings and patterns worth keeping
skill-creator
Builds, tests, and improves skills, including benchmarking and eval runs
frontend-design
Generates production-grade frontend components with high design quality
gemini
Runs Gemini CLI for code analysis, refactoring, or automated editing
codex
Runs Codex CLI for the same
lfg
Full autonomous engineering workflow, end to end
debug-optimize-lcp
Debugs and optimises Largest Contentful Paint using Chrome DevTools
seo-audit
Audits a site for technical SEO issues
Worktrees: One Branch, One Environment
I use Git worktrees heavily. The rule is simple: one branch of work equals one worktree.
This lets me run multiple repos and multiple workstreams at the same time without context switching. I use supacode.sh daily, which makes managing multiple worktrees across multiple repos workable. Each worktree is isolated: its own environment, its own agent session, its own state.
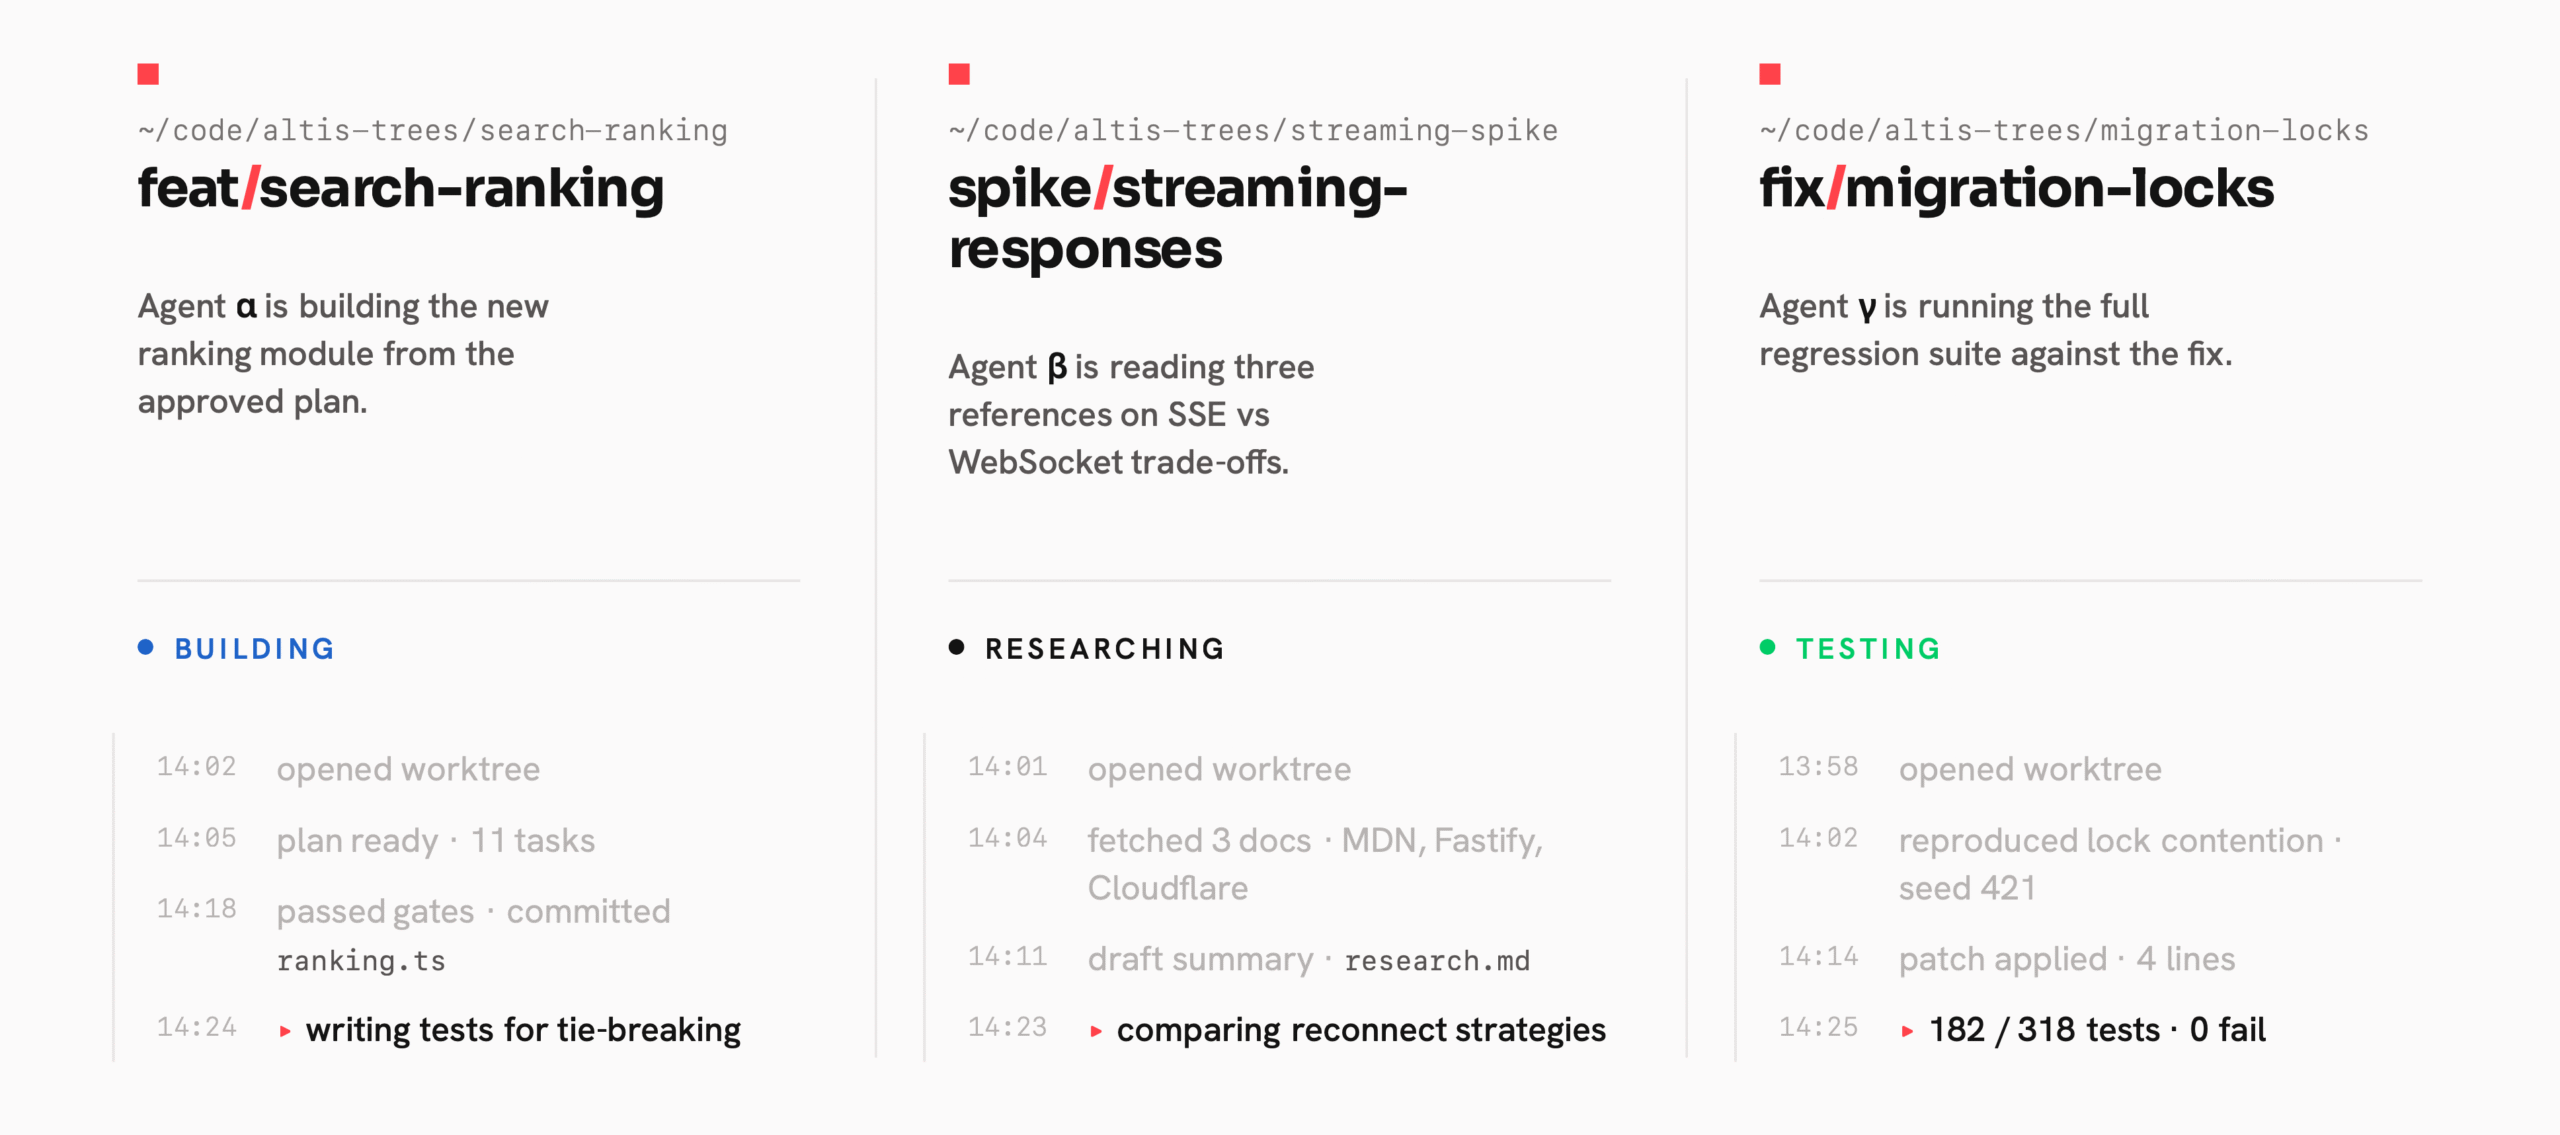
The practical effect is that I can run three or four things in parallel without losing track of any of them. One agent is building a feature. Another is doing research. A third is running tests. I move between them when there is something to review, not before.
Parallel Agents: Do More at Once
Whenever tasks are independent, I spawn multiple agents or subagents in parallel. This is one of the most direct ways to save time.
Instead of running three research tasks in sequence and waiting for each one, I fire all three at once. When they are done, I read the results. The same logic applies to code generation, code review, brainstorming, and exploratory analysis. If the work does not depend on other work completing first, it should run in parallel.
This requires a slight shift in how you think about task planning. Before starting, I ask: which parts of this depend on each other, and which parts are independent? The independent parts go in parallel. It takes practice but becomes instinctive quickly.
Vibe User: Let the Agent Be the User
One technique that most developers miss: ask the agent to use the app as a normal user would.
I call this “Vibe User.” Rather than always using agents to build or review code, I give them browser access, via Chrome DevTools MCP, agent-browser, or the Claude Chrome integration, and tell them to explore the app as a real user with no prior knowledge. The agent navigates, finds friction, forms opinions, and returns ideas, suggestions, and critiques.
This is valuable precisely because I built the thing and know too much. I know where to click, what each error means, where the sharp edges are. A user does not. The agent-as-user surfaces problems I would not notice because I am too close to the code.
Vibe User works well for UX review, early-stage product testing, and any time you need a fresh perspective on something you built. It complements Vibe Coding rather than replacing it.
This is an example of the prompt I use to do UX research on a web app:
You are a Senior Product Designer with 15+ years of experience shipping consumer and B2C products at companies known for design excellence.
Your expertise includes interaction design, information architecture, usability, and design systems.

Role
Act as my design partner and perform a usability and product design review of the application.

Target App
http://YourURL.local/

Method
Use the Chrome DevTools (or Agent Browser) skill to:
1. Open the application.
2. Log in using the provided demo credentials.
3. Explore the product as different user roles.
4. Visit all accessible pages and test core features and workflows.

Demo Credentials

Admin
Email: demo@example.com
Password: demo123456789

Review Framework

For each page you visit, document:

Page
- Page name / route

Observation
- What the page does
- Key UI components and interactions

Critique
- Usability issues
- Interaction friction
- Information architecture problems
- Design system inconsistencies
- UX clarity or affordance issues

Improvement Suggestions
- Specific design improvements
- Interaction changes
- IA or layout changes
- Component-level recommendations

Final Output

After reviewing the entire application:

1. Summarize the overall UX quality of the product.
2. Identify recurring design problems or patterns.
3. Provide the **Top 3 highest-impact improvements** that would most improve usability or product clarity.
4. For each improvement include:
   - Problem
   - Proposed solution
   - Expected impact.
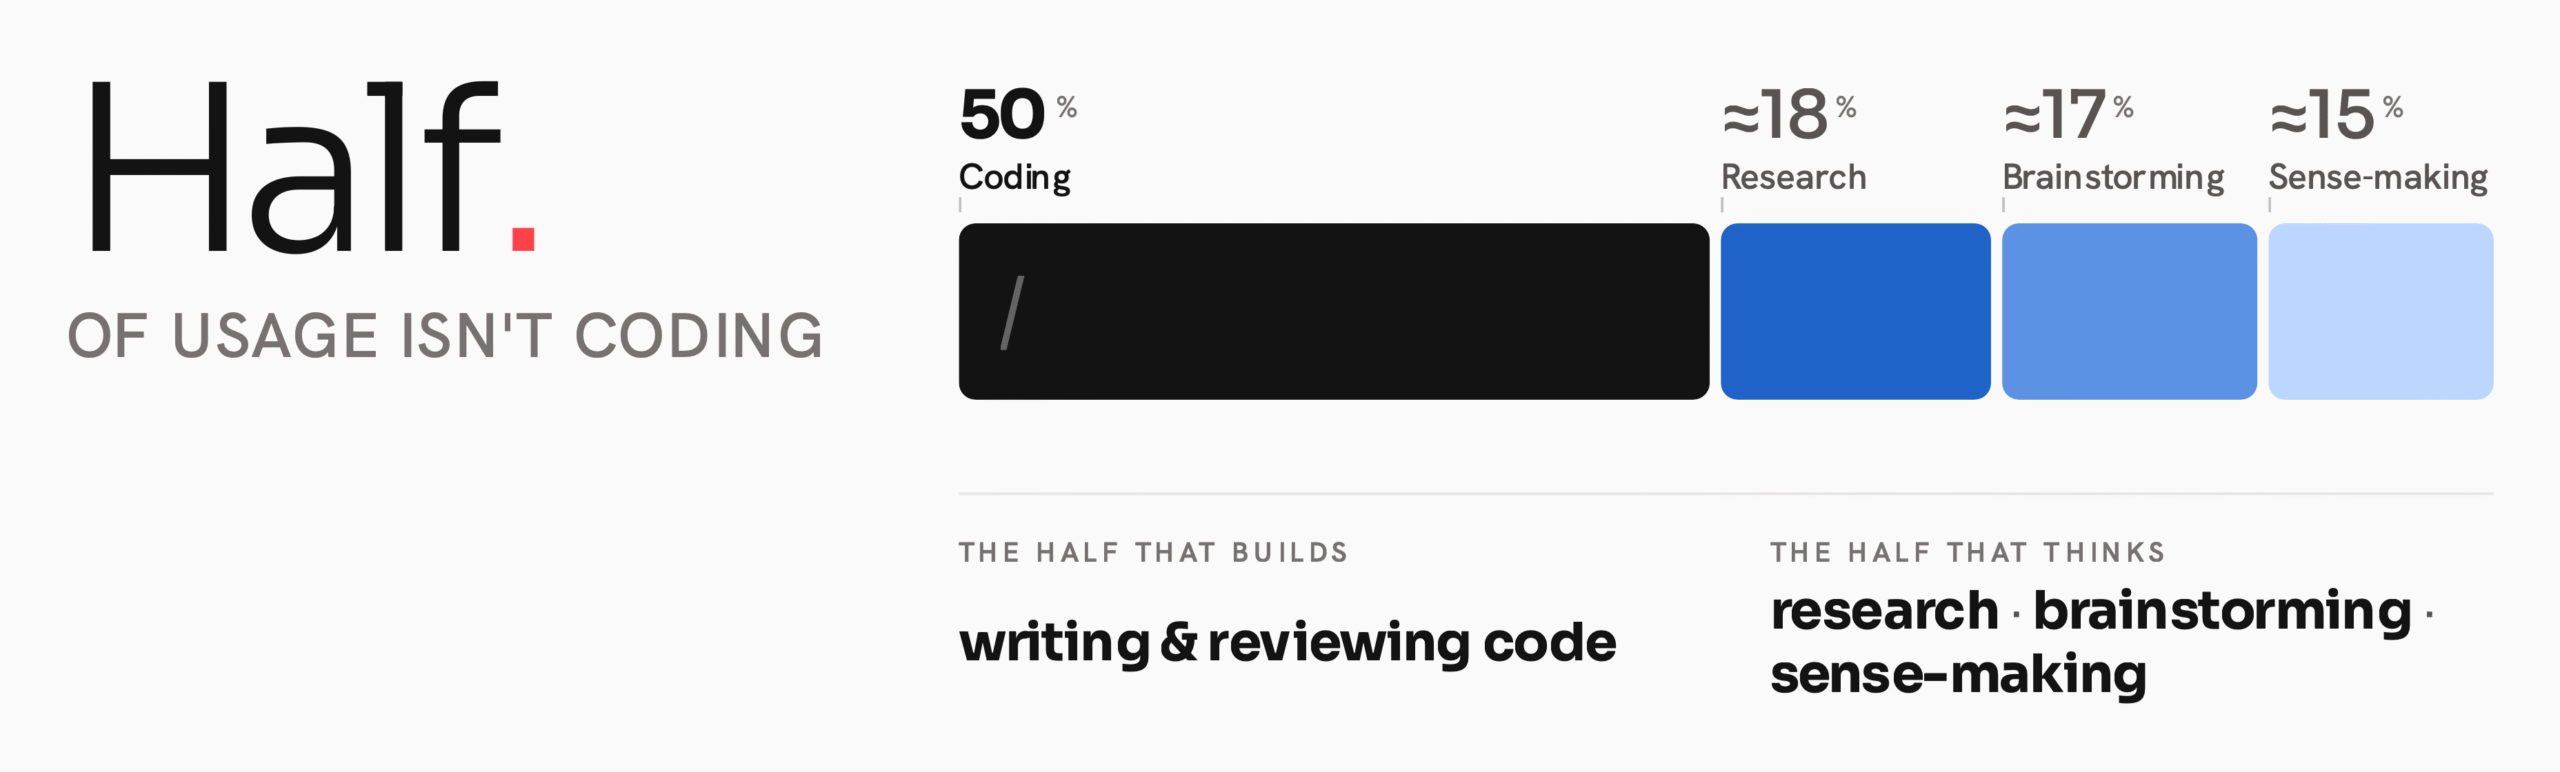
Half of This Is Not Coding
If I add up where my AI usage actually goes, roughly half is not coding at all. It is research, brainstorming, and making sense of information. Agents are as useful for thinking as they are for building, sometimes more so.
On Mobile: Fire and Forget
I use Gemini, Claude, and ChatGPT from my phone throughout the day. When an idea surfaces, on a walk, between meetings, late at night, I open a new thread, ask a question using a skill, gem, or custom GPT, and leave it. I come back when it is ready.
This works because of skills. A good skill means I do not re-explain the context or the standard I am working to. I invoke it, set it running, and move on. Ideas get explored the moment they arise, not when I next find time at a desk.
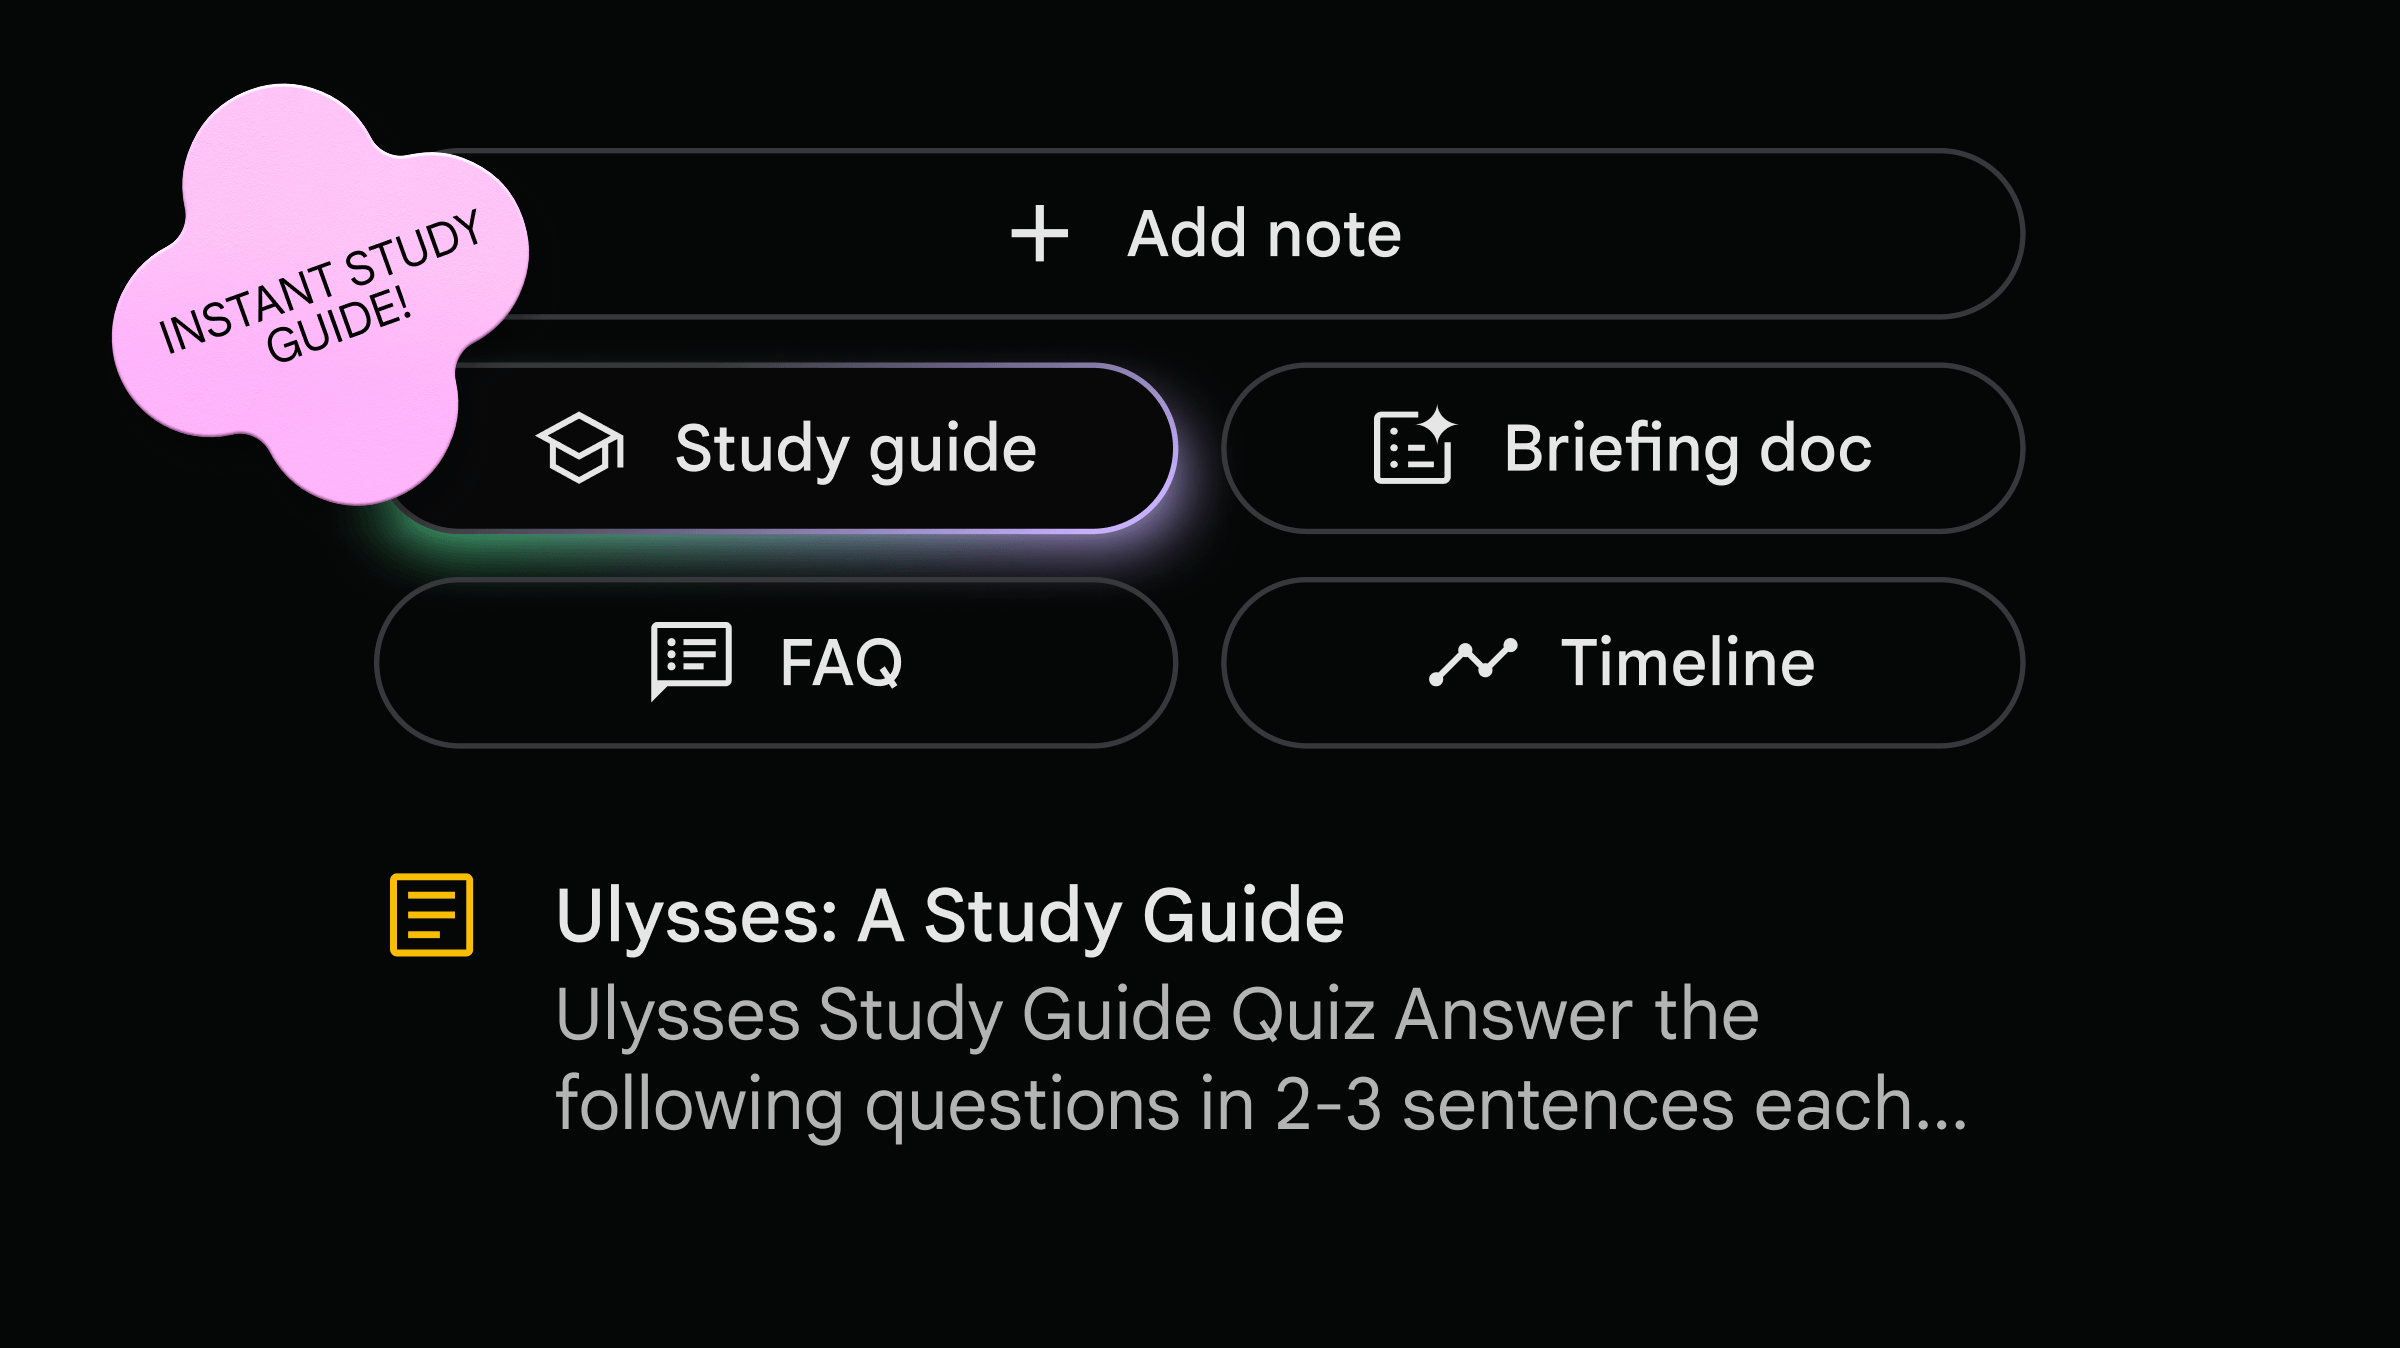
NotebookLM: Making Sense of Messy Sources
For client-facing and sales work, I use Google NotebookLM. The problem it solves is: I have an RFP, a set of Slack notes, a GitHub thread, a Fathom call transcript, and a slide deck, and I need to understand all of it quickly enough to respond well.
I put everything into NotebookLM. Then I ask questions, request summaries, and build mind maps until I have a clear picture of what the client needs. It replaces hours of reading and cross-referencing with a focused conversation.
Two things make NotebookLM useful for this work. First, it hallucinates less than most tools. Second, it cites its sources. Every claim traces back to the document it came from. When I am preparing for a client call, I need to trust what the tool tells me; source citations make that possible.
The Pattern
The pattern is the same across all of it: define the question, send the agent, move on. Come back to the answer.
The agents run while I am doing something else. The work does not wait for my attention. That is the point.
What This Adds Up To
AI agents do not replace thinking. They compress the time between an idea and a result, but only if you show up with clear intent.
The patterns in this post each solve a specific problem. Staying tool-agnostic means no single model’s bad day blocks your progress. Spec-first work means the agent builds what you actually wanted. The throw-away mindset means bad output costs almost nothing. Skills mean repeated work gets faster over time. Worktrees mean you can run many streams without losing track. Parallel agents mean independent work does not wait in a queue. Vibe User means you get honest feedback on what you built.
Together these let you handle more work with less friction. That is the practical part.
What I Had to Unlearn
The harder lesson was emotional.
Early on, I put emotion into my prompts. When the agent produced wrong output, I grew frustrated. When it hallucinated, I pushed back as if it had made a choice. When it kept apologising for the same mistake, I got angry. None of that helped. The agent has no feelings, does not remember being scolded, and frustration in a prompt produces worse output, not better.
I no longer put emotion into how I work with agents. When something goes wrong, I stop, create new session and ask a clear, direct question: what specifically is wrong, and what should change? One precise instruction produces better results than a paragraph of exasperated corrections.
When I genuinely do not know what to do, when I am stuck or the problem is beyond what I understand, I stop guessing and ask the agent to research it. I ask it to return options and reasoning, not an answer. Reading those options helps me think. Then I choose what to do next.
When the output is bad, I throw it away. No negotiating, no patching, no sunk cost. Throw it away, adjust the spec or the model or the approach, and start again. Repeat until it is right.
The Mindset That Stays
The tools will keep changing: new models, new interfaces, new integrations, every week. The underlying approach does not:
There are still much to explore, but I have to pick and choose what works for me and improve my flow better.
PS: I brain dumped all my thoughts for this article into Claude Cowork and Claude Code. This article has been through many cycles of review by myself before publishing.
AI is already part of how enterprise teams work. Quietly in some places, more visibly in others.
Editors use it to summarise long-form content. Marketers lean on it for campaign copy and optimisation. Content teams use it to analyse performance and spot gaps. What started as experimentation has moved into daily workflow faster than most platforms have been able to keep up with.
That gap is where things start to get messy.
Where things start to break down
In many organisations, AI still sits outside the core publishing environment.
An editor drafts in the CMS, switches to an AI tool to generate a summary, copies it back, tweaks it, then repeats the process for metadata, headlines, or social variations. Multiply that across teams, regions, and content types, and it quickly becomes fragmented.
It works, up to a point. Then it doesn’t.
Outputs vary in quality. Content loses structure. There’s no consistent way to apply standards or track how AI is being used. What feels like a productivity boost at the individual level starts to create friction at scale.
The platform, instead of supporting the workflow, sits slightly to one side of it.
Bringing AI into the editorial experience
The real shift happens when AI moves into the platform itself.
Inside WordPress, AI can become part of the editorial flow rather than something separate. Editors can generate summaries, refine copy, suggest metadata, or enrich content without leaving the interface they already know.
That alone reduces friction. But the bigger impact comes from what happens behind the scenes.
Because the content stays structured, those AI-generated elements are more than text pasted into a field; they’re part of a system that can be reused, queried, and adapted across channels. A summary becomes an input for search. Metadata feeds personalisation. Structured content opens up new distribution paths.
Small changes in workflow start to compound.
From isolated tasks to connected workflows
Most early AI adoption focuses on speeding up individual tasks.
Write this faster. Summarise that quicker. Generate a few variations.
Useful, but limited.
The bigger opportunity sits in connecting those tasks together into workflows that build on each other. Analysing a content archive to surface high-value material. Extracting entities and applying consistent taxonomy. Feeding that structure back into new content creation.
Over time, the platform becomes smarter about the content it holds.
Teams spend less time repeating the same work and more time shaping outputs. Editorial effort shifts from production to refinement. Consistency improves without adding overhead.
That is where scale starts to show.
Making governance part of the system
As AI becomes more embedded, the conversation quickly moves beyond productivity.
Accuracy matters. Bias matters. Brand voice matters. At enterprise scale, those concerns cannot be handled informally or left to individual judgement.
They need to be designed into the system.
WordPress gives teams the ability to do that. Review steps can be built into workflows. Permissions can define who can generate, edit, and publish AI-assisted content. Prompts can be managed centrally. Outputs can be tracked and audited.
Nothing sits in a black box.
This creates a different dynamic. Teams can move quickly, experiment with new use cases, and still maintain control over what goes live. Governance becomes part of the workflow, not something layered on afterwards.
Why flexibility matters more than ever
AI capabilities are evolving at pace.
New models, new providers, new use cases. What works today might not be the right fit in six months. Locking into a single approach too early can limit what teams are able to do later.
This is where platform flexibility becomes critical.
With WordPress, AI integrations can be adapted over time. Different services can be connected through a consistent interface. Workflows can evolve as teams learn what delivers value. There is room to experiment without committing to a fixed path.
That ability to adjust matters just as much as the initial implementation.
It also points to where things are heading. WordPress is beginning to move beyond simple integrations towards a more agent-driven model, where AI can take on more active roles within workflows. If you want a deeper look at that direction, this piece on WordPress as an agentic platform explores what that could mean in practice.
Publishing is becoming more dynamic
Content no longer moves in a straight line from draft to publish.
It is analysed, enriched, updated, and redistributed across multiple touchpoints. A single piece might feed a website, an app, a newsletter, a recommendation engine, and a search experience. AI helps drive that process, but only when it is connected to where the content actually lives.
Otherwise, it becomes another disconnected layer.
Platforms that support this kind of dynamic publishing tend to share a common trait. They treat content as structured data, not just formatted text. That structure is what allows AI to add value beyond surface-level generation.
It is what makes content reusable, adaptable, and easier to govern.
Closing the gap between capability and execution
AI adoption is accelerating, regardless of whether platforms are ready.
Teams will continue to use it where they can. The risk is not adoption itself, but inconsistency. Different tools, different standards, different outputs. Over time, that becomes harder to manage and harder to scale.
Bringing AI into the core platform closes that gap.
For enterprise teams working with WordPress, that shift is already underway. The platform’s extensibility makes it possible to integrate AI in ways that reflect real workflows, not idealised ones. It allows teams to move faster while keeping structure, visibility, and control.
That balance is what turns AI from a useful tool into a meaningful capability.
And it is what will define how publishing continues to evolve.
Enterprise platform decisions are often framed as a choice between build or buy. Either you invest in something bespoke, or you purchase a proprietary system that promises speed and structure.
But for many enterprise organisations, that framing no longer fits.
Digital platforms now have to support multiple brands, markets, teams, channels, integrations, and increasingly, AI-enabled workflows. Requirements change quickly. New services need to be added. Legacy systems need to be replaced gradually. Teams need to move faster without losing control.
In that environment, the strongest platform strategy is not always to rebuild from scratch or commit to a single vendor-led roadmap. It is to evolve.
The limits of traditional replatforming
Large-scale replatforming projects often begin with good intentions. The current platform feels too slow, too expensive, or too difficult to change. A new system promises a clean break.
The problem is that enterprise complexity doesn’t disappear when a platform changes. It moves.
Content models, integrations, governance, editorial workflows, compliance requirements, performance needs, and internal processes all still need to be understood and supported. A big-bang migration can create risk, delay value, and force teams to make decisions before they have had a chance to test what works.
By the time the new platform is live, requirements may already have shifted.
Why evolution is a better fit for modern digital teams
An evolution-led approach treats platform change as an ongoing process, not a one-off transformation.
Instead of replacing everything at once, organisations build on a flexible foundation and improve it over time. Capabilities can be added, replaced, or refined as business needs change. Integrations can be modernised in stages. Teams can validate decisions earlier and reduce disruption.
This is where open platforms like WordPress are especially powerful.
WordPress gives enterprises the ability to shape the platform around their needs, rather than adapting their organisation to fit a fixed product model. It can support traditional, headless, hybrid, multisite, and composable architectures, depending on what each part of the business requires.
Flexibility reduces long-term risk
At enterprise scale, the cost of change matters.
A platform that is quick to launch but difficult to adapt can become expensive over time. Licensing tiers, constrained integrations, vendor dependencies, and customisation limits all affect how easily an organisation can respond to new priorities.
Open architecture changes the equation.
With WordPress, teams can change hosting providers, integrate specialist tools, adopt new services, and evolve workflows without being tied to a single vendor’s roadmap. That flexibility reduces lock-in and gives organisations more control over both cost and direction.
Evolution supports better governance
Continuous evolution doesn’t mean uncontrolled change.
In fact, it works best when governance is built in from the start. Shared standards, reusable components, role-based permissions, approval workflows, security practices, and clear ownership models all help distributed teams move quickly while staying aligned.
For global, multi-brand, or multi-language organisations, this balance is critical. Central teams can maintain consistency while local teams retain the flexibility to serve their own markets.
The role of WordPress in an evolving enterprise stack
Modern enterprise platforms rarely operate alone. They sit within a wider ecosystem of DAMs, CDPs, analytics tools, commerce platforms, search services, and AI providers.
WordPress fits naturally into this kind of composable architecture. It can act as the content layer, the publishing interface, the integration point, or part of a wider digital experience platform.
That makes it well suited to phased change. Organisations can start with a focused use case, prove value, then expand over time.
From replacement mindset to evolution mindset
The most successful enterprise platforms aren’t static; they improve continuously.
That requires a shift in mindset. Instead of asking which platform will solve every problem today, leaders should ask which platform gives them the most room to adapt tomorrow.
For many organisations, WordPress provides that foundation: open, extensible, widely adopted, and capable of supporting complex digital operations at scale.
Replatforming may still be necessary. But the goal should not be another fixed end state.
The goal should be a platform that can keep changing.
At WP:26, Human Made’s virtual event exploring the future of WordPress, much of the conversation focused on what’s changing across the web. AI is accelerating workflows, enterprise platforms are becoming more complex, and expectations around digital experiences continue to rise.
But in the middle of all that change, one session brought the conversation back to something more fundamental.
In a conversation with Rian Rietveld, we explored accessibility not as a compliance exercise or a checklist, but as a core part of how we design and build for the web. It quickly became clear that while the tools and technologies around us are evolving rapidly, the question of who we are building for remains just as important as ever.
Throwing off the shackles of compliance checklists, Rian delivered a clear and focused take on how accessible design fundamentally impacts your audience reach and revenue. Across an insight-packed 30-minutes, she guided us through the current state of WordPress accessibility, the awesome WP Accessibility Knowledge Base project she’s been working on, and—crucially—the highest-return investment teams can make today.
Read on to get the key moments and insights from Rian’s session.
From compliance to commercial reality
One of the most striking themes from the session was how quickly the conversation around accessibility is shifting. What was once framed as a compliance requirement is increasingly being recognised as a commercial imperative.
Excluding users with disabilities doesn’t just create a poorer experience, it actively limits your audience. As Rian pointed out, that audience is far from marginal. In fact, the cost of getting accessibility wrong is measurable, with billions in lost revenue each year in markets like the UK alone.
For teams building on the web, this reframes the challenge. Accessibility is no longer about meeting minimum standards or ticking regulatory boxes. It is about ensuring your product is usable by as many people as possible, not only because it is the right thing to do, but because it directly impacts reach, engagement, and ultimately, revenue.
Accessibility, AI, and search are converging
One of the most interesting parts of the discussion was how accessibility is increasingly intersecting with other concerns that teams are already prioritising, particularly around AI and search.
As highlighted throughout WP:26, machines are playing a growing role in how content is discovered, interpreted, and acted upon. Whether it is search engines, assistive technologies, or AI agents, all of these systems depend on the same underlying signals to make sense of the web.
Those signals are not new. They include things like semantic HTML, clear heading structures, meaningful labels, and predictable interactions. In other words, the same practices that have always underpinned accessible design.
What is changing is the level of importance. Accessibility is no longer a separate consideration running alongside SEO or AI readiness. It is becoming part of the same foundation. If content is not structured in a way that machines can understand, it becomes harder to find, harder to interpret, and ultimately less useful.
That convergence raises the stakes. Getting accessibility right is no longer just about supporting specific users. It is about ensuring content works in an increasingly machine-mediated web.
Actionable strategy: The highest-return on investment
If advising a digital leader, Rian shared the single highest-return investment in 2026:
Training people: Train your designers, content creators, and developers on how to build accessible products. Most accessibility is “just decent code, decent HTML.”
Prioritise keyboard navigation: A website and all its functionality must be able to work with the keyboard only. This is the essence of accessibility and should be a non-negotiable testing priority.
Contribute to the Knowledge Base: Rian encouraged the community to get involved with the WP Accessibility Knowledge Base to create one central source of truth for all WordPress accessibility documentation.
“If you create only for perfect people, people who have perfect eyesight, are clear of mind, can move their hands, are web savvy. Well, then you say, okay, only those people are allowed in my web shop and the rest of the people I don’t give access to and the rest of the people are quite a lot of people. So you have to take into account that you build for everyone, not only for perfect people.” – Rian Rietveld, Web Accessibility Specialist.
New campaigns launch. Product updates go live. Traffic spikes. Leadership wants reporting. And suddenly your WordPress platform is under more scrutiny than ever.
If you manage an enterprise WordPress estate, performance is not just a technical concern. It directly impacts revenue, search visibility, user satisfaction, and operational efficiency.
Before the new quarter begins, now is the time to pressure test your platform.
Here is a practical checklist of five performance audits every enterprise team should complete before Q1 kicks off.
1. Full-stack performance benchmarking
Before you optimise, you need a clear baseline.
Enterprise sites are complex. Multiple integrations, global audiences, high editorial velocity, and layered caching all influence performance. A superficial PageSpeed score is not enough.
Start with:
Real user monitoring data, not just synthetic tests
Core Web Vitals across key templates
Performance under peak load conditions
Geographic performance for global audiences
Logged-in versus anonymous user experiences
Look at performance by template type, not just the homepage. Product pages, landing pages, search results, and editorial content often behave very differently.
You should be asking:
Where are we slowest, and why?
Are performance issues systemic or template-specific?
How does performance change during traffic spikes?
Are recent releases impacting speed?
For enterprise WordPress, performance issues are often architectural, not cosmetic. This audit helps identify whether you are dealing with frontend inefficiencies, backend bottlenecks, infrastructure constraints, or a combination of all three.
2. Infrastructure and hosting review
Your infrastructure is the foundation of performance. If it’s misconfigured or under-provisioned, no amount of frontend tuning will compensate.
Before Q1, review:
Hosting architecture and scalability model
Autoscaling policies and thresholds
Database performance and indexing
Object caching implementation
CDN configuration and cache hit rates
PHP version and runtime configuration
Enterprise traffic patterns are rarely consistent. Campaign launches, media coverage, and seasonal demand create unpredictable spikes. If your autoscaling policies have not been tested recently, you are taking a risk.
Load testing is critical here. Simulate realistic Q1 traffic scenarios. Don’t just test maximum concurrent users. Test editorial workflows, logged-in traffic, API usage, and background jobs running simultaneously.
A mature enterprise platform should degrade gracefully under load, not fail abruptly.
3. Plugin and dependency audit
Enterprise WordPress sites accumulate plugins over time. Some are essential. Others linger long after their purpose has passed.
Each plugin introduces:
Additional database queries
Extra HTTP requests
Potential conflicts
Security and maintenance overhead
Before Q1, conduct a thorough plugin and dependency review.
Ask:
Is this plugin still necessary?
Can its functionality be consolidated or custom-built more efficiently?
Is it actively maintained and compatible with your WordPress version?
Does it introduce frontend performance overhead?
Pay particular attention to:
Page builder plugins
Analytics and tracking scripts
Marketing automation integrations
Search enhancements
Personalisation tools
Also review third-party scripts injected via tag managers. Marketing tags often expand quietly over time, increasing JavaScript execution costs and affecting Core Web Vitals.
Enterprise performance is often eroded gradually. This audit should help you regain control.
4. Frontend performance and Core Web Vitals deep dive
These days, Core Web Vitals aren’t just SEO metrics; they’re user experience indicators. And for enterprise brands, experience is everything.
Audit:
Largest Contentful Paint on key templates
Cumulative Layout Shift caused by dynamic content
Interaction to Next Paint and JavaScript execution time
Image optimisation and responsive image handling
Critical CSS and render-blocking resources
Enterprise WordPress themes evolve over years, and design refreshes, campaign components, and microsite features accumulate. The result can be bloated bundles and redundant CSS.
Look for:
Unused JavaScript
Excessive client-side rendering
Overuse of large component libraries
Inefficient image formats or missing lazy loading
Web font loading strategies
If your design system has expanded without a performance review, this is where you’ll find hidden costs.
5. Editorial workflow and backend performance audit
Performance concerns what users see, but it’s also about how your teams work.
Slow admin screens, delayed publishing, and heavy block editor experiences reduce productivity and create operational friction.
Audit:
Admin load times
Block editor responsiveness
Media library performance
Search performance in large content repositories
Background processing queues
Enterprise WordPress sites often contain hundreds of thousands of posts, assets, and metadata entries. Database growth affects both frontend and backend performance.
Check:
Database indexing and query efficiency
Post revisions and autoloaded options
Taxonomy usage and optimisation
Cron job configuration
If your editorial team is preparing for Q1 content pushes, campaign launches, or product updates, backend performance matters just as much as frontend speed.
A fast publishing workflow supports business momentum.
Why this matters before Q1
Q1 is when budgets reset, expectations rise, and new initiatives go live.
Performance issues during this period are more visible, more disruptive, and more costly.
An enterprise performance audit before Q1 helps you:
Reduce risk before traffic spikes
Protect SEO visibility
Improve conversion rates
Support marketing and product teams
Strengthen confidence at leadership level
It also gives you a clear roadmap for prioritising improvements, instead of reacting to issues once they surface.
Ready to audit your platform?
Enterprise WordPress performance is rarely about a single fix. It is about architecture, governance, infrastructure, and ongoing optimisation working together.
If you want a comprehensive, expert-led assessment of your platform, our team can help.
Explore our performance audit offering and speak to our specialists about preparing your WordPress platform for Q1 success.
At WP:26, Human Made’s virtual event exploring the future of WordPress, we brought together technologists, publishers, and platform leaders to discuss one big question:
What patterns are emerging that will shape WordPress in 2026 and beyond?
Across a day of talks and conversations, speakers explored how AI, accessibility, enterprise publishing, and evolving web standards are reshaping the role of a CMS.
To open the event, Human Made’s CGO and Partner Noel Tock set the tone with a provocative idea:
What happens when software agents start interacting with websites as much as people do?
It’s a question that sits right at the centre of how the web is changing. AI systems are already summarising content, generating answers, and navigating websites programmatically. The next step is systems that don’t just read the web, but act on it.
And when that happens, the role of a CMS starts to look very different.
The web is becoming machine-operable
For most of the web’s history, websites have been designed primarily for human interaction. People visit a page, read content, click buttons, and navigate between sections.
But increasingly, machines are doing the same things.
Search engines have been crawling and interpreting websites for years. Now AI assistants and software agents are beginning to go further, understanding context, extracting information, and triggering workflows across systems.
As Noel put it during the talk:
“The web is shifting from something humans browse to something agents can act on.”
That shift has significant implications for how digital platforms are designed.
If agents can interact with websites directly, the web becomes less like a collection of documents and more like a network of programmable interfaces.
Rethinking what a CMS actually does
This is where the conversation gets interesting for agentic WordPress.
Traditionally, a CMS has been thought of as publishing infrastructure. A system for managing content, rendering pages, and delivering experiences to users.
But in an agent-driven environment, a CMS becomes something more powerful: a platform for orchestrating workflows between systems, people, and AI agents.
Content becomes structured data. Interfaces become programmable endpoints. Publishing workflows become automation pipelines.
That’s not a distant future scenario. In many organisations, it’s already starting to happen.
Why WordPress is well positioned for an agentic future
One of the most compelling ideas in Noel’s keynote was that WordPress may actually be unusually well suited to this transition.
Not because it was designed for AI agents — it wasn’t.
But because of the way the platform has evolved over time.
WordPress already has many of the characteristics needed for this next, agentic phase of the web:
Open APIs that allow systems to interact with content programmatically
Extensibility through plugins and custom development
Flexible architectures that support headless, hybrid, and full-stack approaches
A large ecosystem constantly experimenting with new patterns
In other words, the platform has the structural flexibility needed to adapt as the web changes.
That adaptability has been one of WordPress’s quiet strengths for more than two decades.
Open ecosystems move faster
Another thread running through the session was the role of openness.
When technology shifts quickly, proprietary systems often struggle to keep up. Innovation tends to happen faster in open ecosystems where developers can experiment, integrate new tools, and build on top of shared infrastructure.
We’re already seeing that pattern play out across the AI landscape itself, where many of the most influential tools and frameworks are emerging from open communities.
WordPress fits naturally into that model.
Its openness allows teams to integrate new AI capabilities, experiment with agent-based workflows, and adapt their platforms without waiting for a vendor roadmap to catch up.
From publishing system to programmable platform
If there was one idea that framed the rest of WP:26, it was this:
WordPress is evolving from publishing infrastructure into a programmable platform for intelligent workflows.
That doesn’t mean the fundamentals of content management go away. Publishing, editorial workflows, and content creation are still at the heart of the platform.
But the context around them is expanding.
Content isn’t just read by people anymore. It’s processed by systems. Websites aren’t just visited. They’re queried and acted upon.
And platforms that can support that shift will play an important role in how the next generation of digital experiences are built.
A fitting start to WP:26
Noel’s keynote set the tone for the rest of the event.
Throughout the day, speakers explored related themes from different perspectives: how AI is changing search and discoverability, how accessibility overlaps with machine-readable content, and how enterprise organisations are adapting their WordPress platforms to support increasingly intelligent workflows.
In many ways, those conversations all traced back to the same underlying idea.
The web is changing.
And platforms like WordPress are evolving right alongside it.
For a long time, enterprise teams have been stuck with an uncomfortable trade-off. In 2026, WordPress breaks it.
You could scale fast, but only by accepting rigidity, brittle tooling, and a growing maintenance burden. Or you could stay flexible, at the cost of control, consistency, and long-term sustainability.
That false choice has shaped how digital platforms are designed, built, and governed for over a decade.
Until now, that is. WordPress is no longer just a publishing platform: it’s evolving into an intelligent CMS. One that combines structured data, reusable patterns, and increasingly agentic workflows to help teams move faster without creating fragility.
This shift changes what enterprise teams should prioritise, what they can safely stop over-engineering, and how they can build systems that adapt over time instead of fighting change.
Here’s how to get the most out of WordPress in 2026.
1. Stop chasing stacks
For years, enterprise digital platforms have grown by accumulation.
Another tool to manage content. Another service to orchestrate workflows. Another layer of glue code to hold it all together.
The result is complexity that slows teams down and makes change expensive.
Modern WordPress reduces that complexity by delivering more integrated capability out of the box. Core concepts like blocks, patterns, data relationships, and extensibility now work together as a system rather than isolated features.
Less glue code. Fewer fragile integrations. More momentum.
The opportunity for enterprise teams is to simplify their stacks, not expand them, and to treat WordPress as a platform that can carry more responsibility without the traditional complexity tax.
2. Design systems, not pages
One of the most important mindset shifts is moving away from page-by-page thinking.
Reusable blocks and synced patterns allow teams to design systems rather than individual experiences. You build once, then scale everywhere. Updates propagate safely. Consistency becomes an asset rather than a constraint.
For large organisations, this changes how design, development, and content teams collaborate. Governance no longer means locking things down. It means defining strong patterns and letting teams move quickly within them.
3. Structure first, visual always
Enterprise platforms often fail editors in one of two ways.
Either they prioritise structure and governance but make publishing slow and frustrating. Or they prioritise visual freedom but sacrifice consistency and data quality.
WordPress in 2026 makes it possible to have both.
Structured data sits underneath flexible, visual interfaces. Editors can move quickly without breaking rules they never see. Platforms remain robust without feeling heavy.
This balance is essential for teams producing content at scale, across markets, brands, and channels.
4. Think in capabilities, not features
Traditional platforms are built around features. Each new requirement leads to another custom build or plugin.
WordPress is increasingly built around capabilities.
Block bindings, composability, and shared data models allow teams to create systems that evolve. Future change becomes configuration and extension, not a rebuild.
When platforms are designed this way, adaptability becomes the default. Custom code becomes the exception rather than the foundation.
5. Let workflows do the work
Another major shift is the rise of agentic workflows.
Repetitive effort that once required manual intervention can increasingly be orchestrated. Content preparation, transformation, quality checks, and distribution become coordinated systems rather than individual tasks.
This allows teams to scale output without scaling headcount. It also reduces risk by removing human error from routine processes.
For enterprise organisations under constant pressure to do more with less, this isn’t a nice-to-have – it’s a competitive advantage.
6. Govern without slowing down
Control and speed no longer need to be opposites.
Centralised patterns combined with decentralised execution allow platforms to remain governed while enabling teams to act independently. Standards are enforced through design, not policy documents. Guardrails replace bottlenecks.
This is where WordPress is heading, and where many enterprise platforms need to go if they want to stay relevant.
7. Build for what comes next
The real power of WordPress in 2026 is what it enables tomorrow.
Platforms built around adaptability outperform those built around custom code every time. They absorb change rather than resist it. They evolve without constant reinvention.
Enterprise teams now face a clear choice.
Build on an intelligent CMS. Or compete against teams who already are.
Go deeper: WordPress in 2026
This post only scratches the surface of what’s changing and why it matters.
Our new report, WordPress in 2026: The dawn of the intelligent CMS, explores what this shift means for enterprise teams, platforms, and the next decade of digital experiences. It covers what to prioritise, what to stop over-engineering, and how to design systems that remain resilient as WordPress continues to evolve.
We are also hosting WP:26, a dedicated event where we will unpack the themes from the report, share real-world examples, and explore what intelligent CMS architecture looks like in practice.
Accessibility often enters the conversation through the lens of compliance. Laws like the ADA or the European Accessibility Act make it non-negotiable. But compliance is only the beginning. Teams that treat accessibility as a strategic investment discover benefits that reach far beyond legal risk.
Accessibility drives performance, efficiency, and growth: the same outcomes every digital leader is trying to achieve.
Here’s how accessibility can unlock business advantage.
1. Accessibility improves conversion and retention
When a site is accessible, it reduces friction for every visitor. Accessible design is simply good design: faster, clearer, and easier to act on.
Consider these examples:
Forms that work with keyboard navigation also convert better on mobile.
Descriptive link text improves comprehension, which in turn supports SEO and click-through.
Readable contrast ratios reduce bounce rates by making content easier to scan in all lighting conditions.
A study by the UK’s Click-Away Pound project found that inaccessible sites cost British retailers £17 billion each year in lost revenue. The logic is simple: when people can use your site, they stay, buy, and return.
Takeaway: Every accessibility improvement increases usability, which directly impacts conversions and customer loyalty.
2. Accessibility lowers technical debt
Accessibility often feels expensive because teams try to add it after launch. Retrofitting fixes into an existing product is the real cost driver.
When accessibility is built in from the start — during design systems, component creation, and content workflows — it prevents common issues that later require developer rework.
Accessibility standards like semantic HTML, ARIA roles, and clear focus states also make code cleaner and easier to maintain. Teams gain long-term efficiency by removing ambiguity and duplication.
Takeaway: Accessibility built early saves both time and money later. It’s a form of quality assurance that protects future budgets.
3. Accessibility strengthens your brand and customer trust
Accessibility sends a clear signal about your organisation’s values. It tells people that inclusion is part of your culture, not a campaign.
Customers increasingly choose brands that reflect their ethics. Inclusive design and accessible experiences demonstrate respect for diverse audiences and reinforce trust — particularly important for sectors where credibility is key, like finance, healthcare, and higher education.
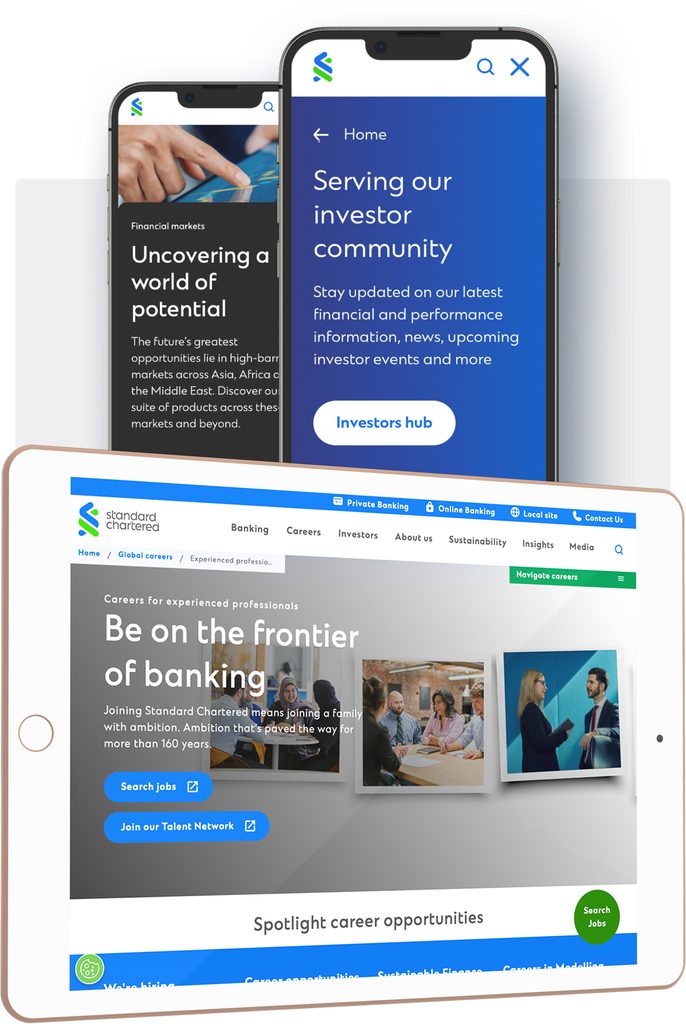
Human Made’s work with Standard Charteredis a strong example. Accessibility was treated as a global design principle across multiple markets and languages. The outcome was not only compliance but a more consistent user experience for every customer.
Takeaway: Accessibility builds trust at scale. It’s an investment in brand equity as much as technical capability.
4. Accessibility helps teams scale responsibly
Enterprise WordPress environments can span hundreds of sites, each with different editors, themes, and plugins. Without a shared accessibility standard, quality becomes inconsistent.
Embedding accessibility into design systems and governance models brings control and predictability. Reusable, accessible components make it easier for distributed teams to deliver consistent results without starting from scratch each time.
This also supports compliance across regions with differing regulations — a growing challenge for global organisations.
Takeaway: Accessibility governance creates efficiency and consistency across complex ecosystems.
5. Accessibility fuels innovation
Constraints are often where creativity begins. Designing for accessibility encourages teams to think differently about interaction, language, and structure.
Voice interfaces, dark-mode design, and responsive layouts all originated from accessibility thinking. Today, AI-driven captioning, pattern recognition, and alt-text generation are continuing that trend.
Teams that treat accessibility as a driver of innovation discover better solutions for all users — not just those with specific needs.
Takeaway: Accessibility challenges assumptions and leads to better digital products.
Building a culture of accessibility
At Human Made, we believe accessibility is a marker of maturity. It reflects how a company approaches design, development, and content creation as a unified practice.
That’s why we’re sponsoring accessibility specialist Rian Rietveld to create the WordPress Accessibility Knowledge Base, a central resource that will make accessibility knowledge easier to find and apply across the ecosystem.
Accessible design is not a compliance task. It’s an operational advantage — one that makes digital experiences faster, cleaner, more consistent, and more inclusive.
Take action: Start by auditing one site, one workflow, or one component library. Identify the quick wins — like colour contrast, form labels, or keyboard navigation — and build from there.
Every improvement you make strengthens your platform. Why wait to unlock the business advantage accessibility can bring?
The 2025 State of Enterprise WordPress report offers one of the clearest pictures yet of how large organisations are using WordPress to deliver at scale. The findings reveal a platform maturing in capability, broadening in adoption, and steadily gaining influence inside enterprise technology stacks. For teams navigating digital strategy, this year’s report provides valuable insight into what is working, where investment is growing, and how leaders are thinking about the future of their CMS ecosystems.
Here are the five takeaways that matter most.
1. Enterprise adoption is deepening across sectors and regions
WordPress is not only well established in the enterprise; it’s diversifying. Participation in the survey shows strong representation from media and technology, but also rising engagement from education, non-profit, and a wider mix of commercial sectors.
Organisations are also reporting far higher traffic volumes than in previous years. A growing share now serves more than ten million unique visitors each month. This shift signals confidence in the platform’s performance profile and a recognition that WordPress can anchor large scale digital estates.
2. The block editor is now the default way enterprises create and manage content
More than eighty percent of respondents are using the block editor in production. Teams report that it makes content creation significantly easier and supports more flexible workflows across large editorial groups. Daily usage of WordPress has also increased, which suggests that the editor experience is maturing in ways that genuinely support high output teams. As more organisations embrace block based workflows, the expectations for modular, reusable, and collaborative content operations continue to rise.
3. Headless adoption is expanding as organisations seek greater technical flexibility
Use of WordPress as a headless CMS more than doubled this year. The shift reflects a growing desire for decoupled architectures that support multi platform experiences, high performance front ends, and more specialised engineering choices. WordPress remains at the centre of the content layer, yet is increasingly paired with modern frameworks and custom delivery channels. For enterprises managing complex digital estates, the ability to choose the right tool for each part of the stack has become a major advantage.
4. Open source contribution is becoming a strategic priority
Two thirds of surveyed organisations now contribute to WordPress in some form. This is the highest level of participation ever recorded in the report. Large scale users are recognising that investing in the ecosystem is essential for long term stability, better tooling, and a healthier platform. Contribution is no longer viewed as a nice to have: it’s becoming part of responsible digital stewardship. Enterprises that shape the tools they rely on gain a more resilient and cost effective foundation for the future.
5. WordPress continues to win as a strategic choice rather than a cost saving measure
Functionality, scalability, usability, and extensibility are the strongest reasons organisations choose WordPress. These factors outrank cost by a wide margin. Senior leadership teams, including Boards and C level executives, are now more involved in CMS decisions. This shift signals a recognition that the CMS is not simply an operational tool. It is a strategic asset that influences speed to market, customer experience, and the ability to evolve digital products over time. WordPress is increasingly chosen for its adaptability and long term value rather than short term budget efficiency.
The 2025 report shows a platform that is scaling with enterprise needs and evolving through active industry participation. WordPress continues to offer a flexible foundation for organisations that want control of their digital futures. With rising investment in open source, stronger editorial workflows, and greater architectural choice, the enterprise WordPress ecosystem looks well positioned for another year of growth and innovation.

 Login